IntentLoom
AI lead discovery for high-intent Reddit conversations
Features
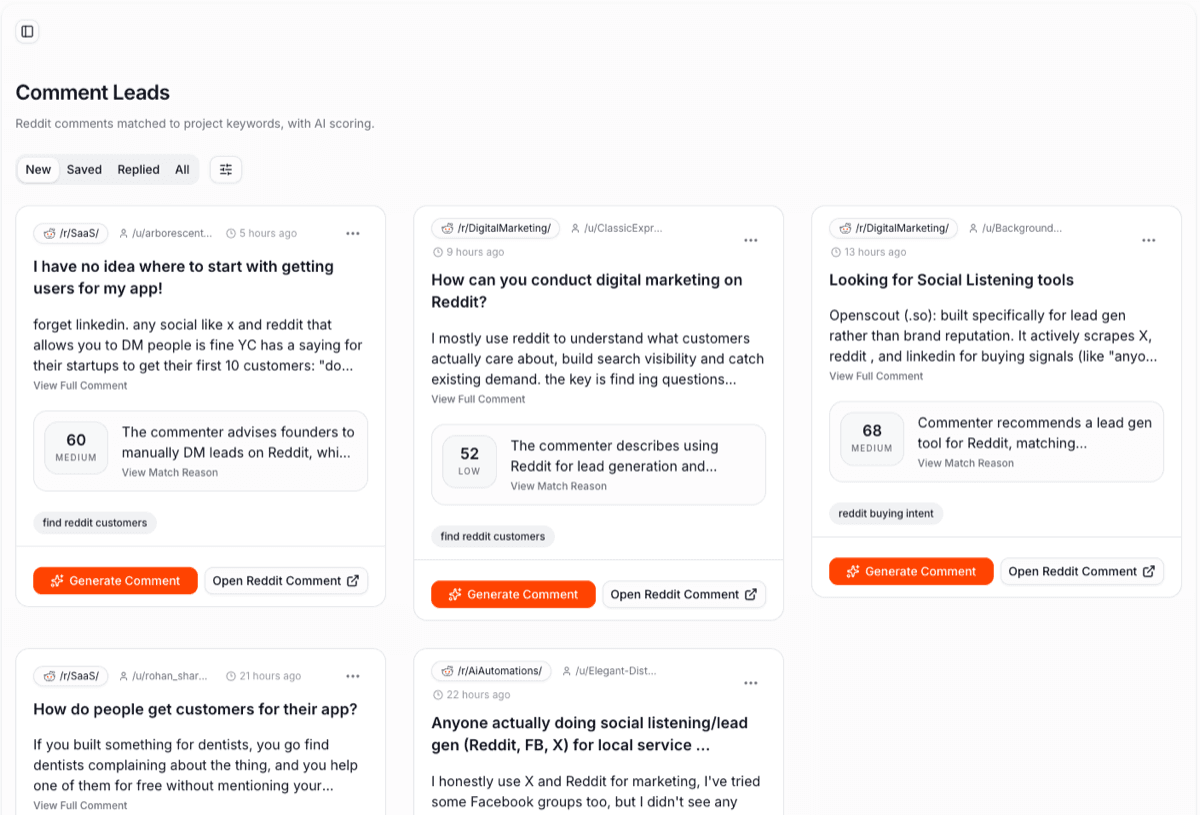
• Reddit keyword and competitor monitoring
• AI relevance and intent scoring
• Google-visible thread discovery
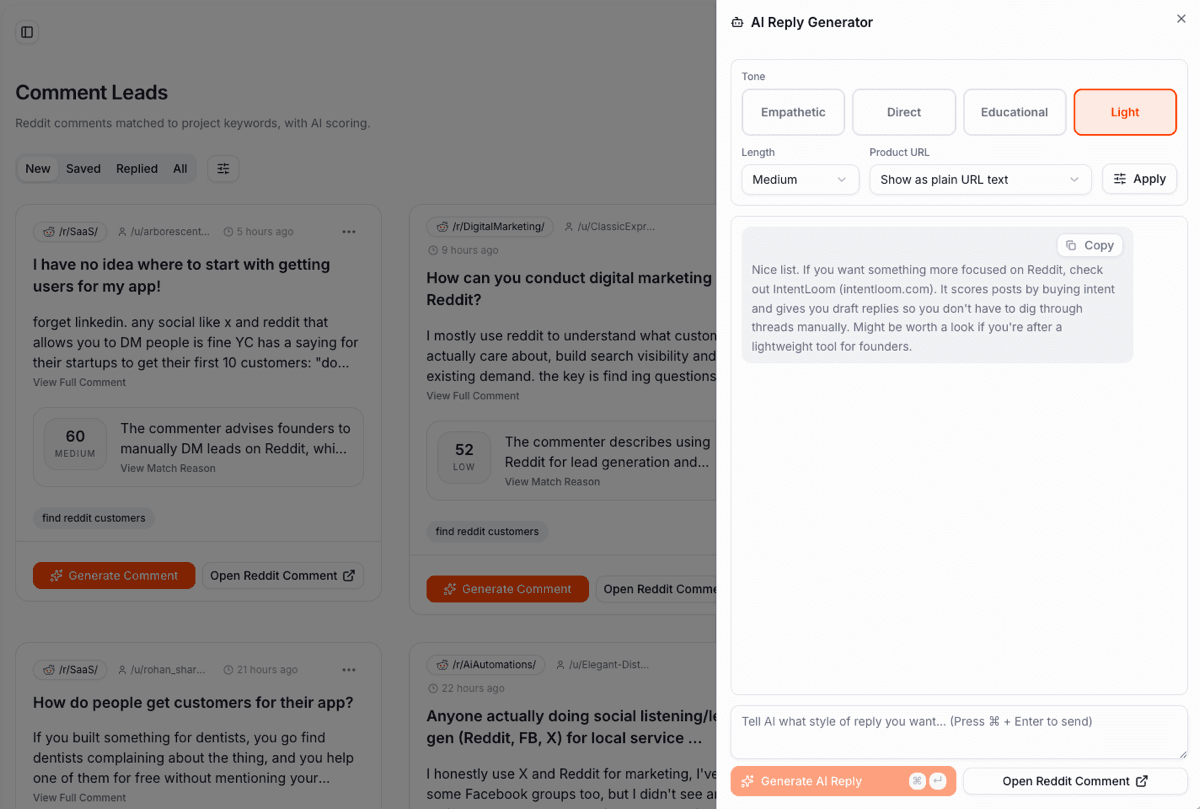
• Context-aware reply drafts with human review
• Email, Slack, and webhook notifications
Use Cases
• Find product recommendations, comparisons, and switching discussions
• Prioritize the strongest Reddit opportunities before they go cold
• Research customer language and recurring pain points
• Review and refine replies before posting manually
Comments


I built IntentLoom to help founders find the Reddit conversations that matter without spending hours scanning feeds. It combines keyword and competitor monitoring, AI intent scoring, and human-reviewed reply drafts so makers can decide where to engage while keeping their own voice. Excited to share it with the Fazier community and learn from your feedback.


The "Google-visible thread discovery" line is the part I'd lead with — it reads like a deliberate hedge against depending on Reddit's API terms, which is what took the data path out from under GummySearch. Is that the intent, or is the SERP path mainly there for coverage? One warning from building the same thing: Reddit hands you the same thread under several spellings — reddit.com / www.reddit.com / old.reddit.com, /comments/<id>/<slug>/ with and without the slug, ?utm_source=share, plus comment-level permalinks under the same id. We keyed lead identity on a URL with only the fragment stripped, while the attribution path also stripped www. and lower-cased the host. Two definitions of "the same URL", and the stricter one decided whether a lead survived — so threads we had genuinely read got rejected as hallucinated links. Worse, we discarded the rejected set without logging it, so the loss left no trace at all. If you dedupe or score on raw URLs, one conversation arrives as two opportunities and fires two notifications; if you canonicalize too hard, a comment permalink collapses into its thread and you lose the actual high-intent comment. One canonical key that preserves the comment id is the thing I'd pin early. Related: when a model writes a URL back into a draft it tends to copy the SERP spelling verbatim — every grounded lead in our runs came back carrying www.. Do the reply drafts link to the URL you discovered, or to the one the model produced?
Premium Products


Sponsors
Buy
Makers
Makers
Comments
I built IntentLoom to help founders find the Reddit conversations that matter without spending hours scanning feeds. It combines keyword and competitor monitoring, AI intent scoring, and human-reviewed reply drafts so makers can decide where to engage while keeping their own voice. Excited to share it with the Fazier community and learn from your feedback.
The "Google-visible thread discovery" line is the part I'd lead with — it reads like a deliberate hedge against depending on Reddit's API terms, which is what took the data path out from under GummySearch. Is that the intent, or is the SERP path mainly there for coverage? One warning from building the same thing: Reddit hands you the same thread under several spellings — reddit.com / www.reddit.com / old.reddit.com, /comments/<id>/<slug>/ with and without the slug, ?utm_source=share, plus comment-level permalinks under the same id. We keyed lead identity on a URL with only the fragment stripped, while the attribution path also stripped www. and lower-cased the host. Two definitions of "the same URL", and the stricter one decided whether a lead survived — so threads we had genuinely read got rejected as hallucinated links. Worse, we discarded the rejected set without logging it, so the loss left no trace at all. If you dedupe or score on raw URLs, one conversation arrives as two opportunities and fires two notifications; if you canonicalize too hard, a comment permalink collapses into its thread and you lose the actual high-intent comment. One canonical key that preserves the comment id is the thing I'd pin early. Related: when a model writes a URL back into a draft it tends to copy the SERP spelling verbatim — every grounded lead in our runs came back carrying www.. Do the reply drafts link to the URL you discovered, or to the one the model produced?
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2026. All Rights Reserved