UptimeEye
Monitor real user flows, APIs & cron jobs — 30s checks
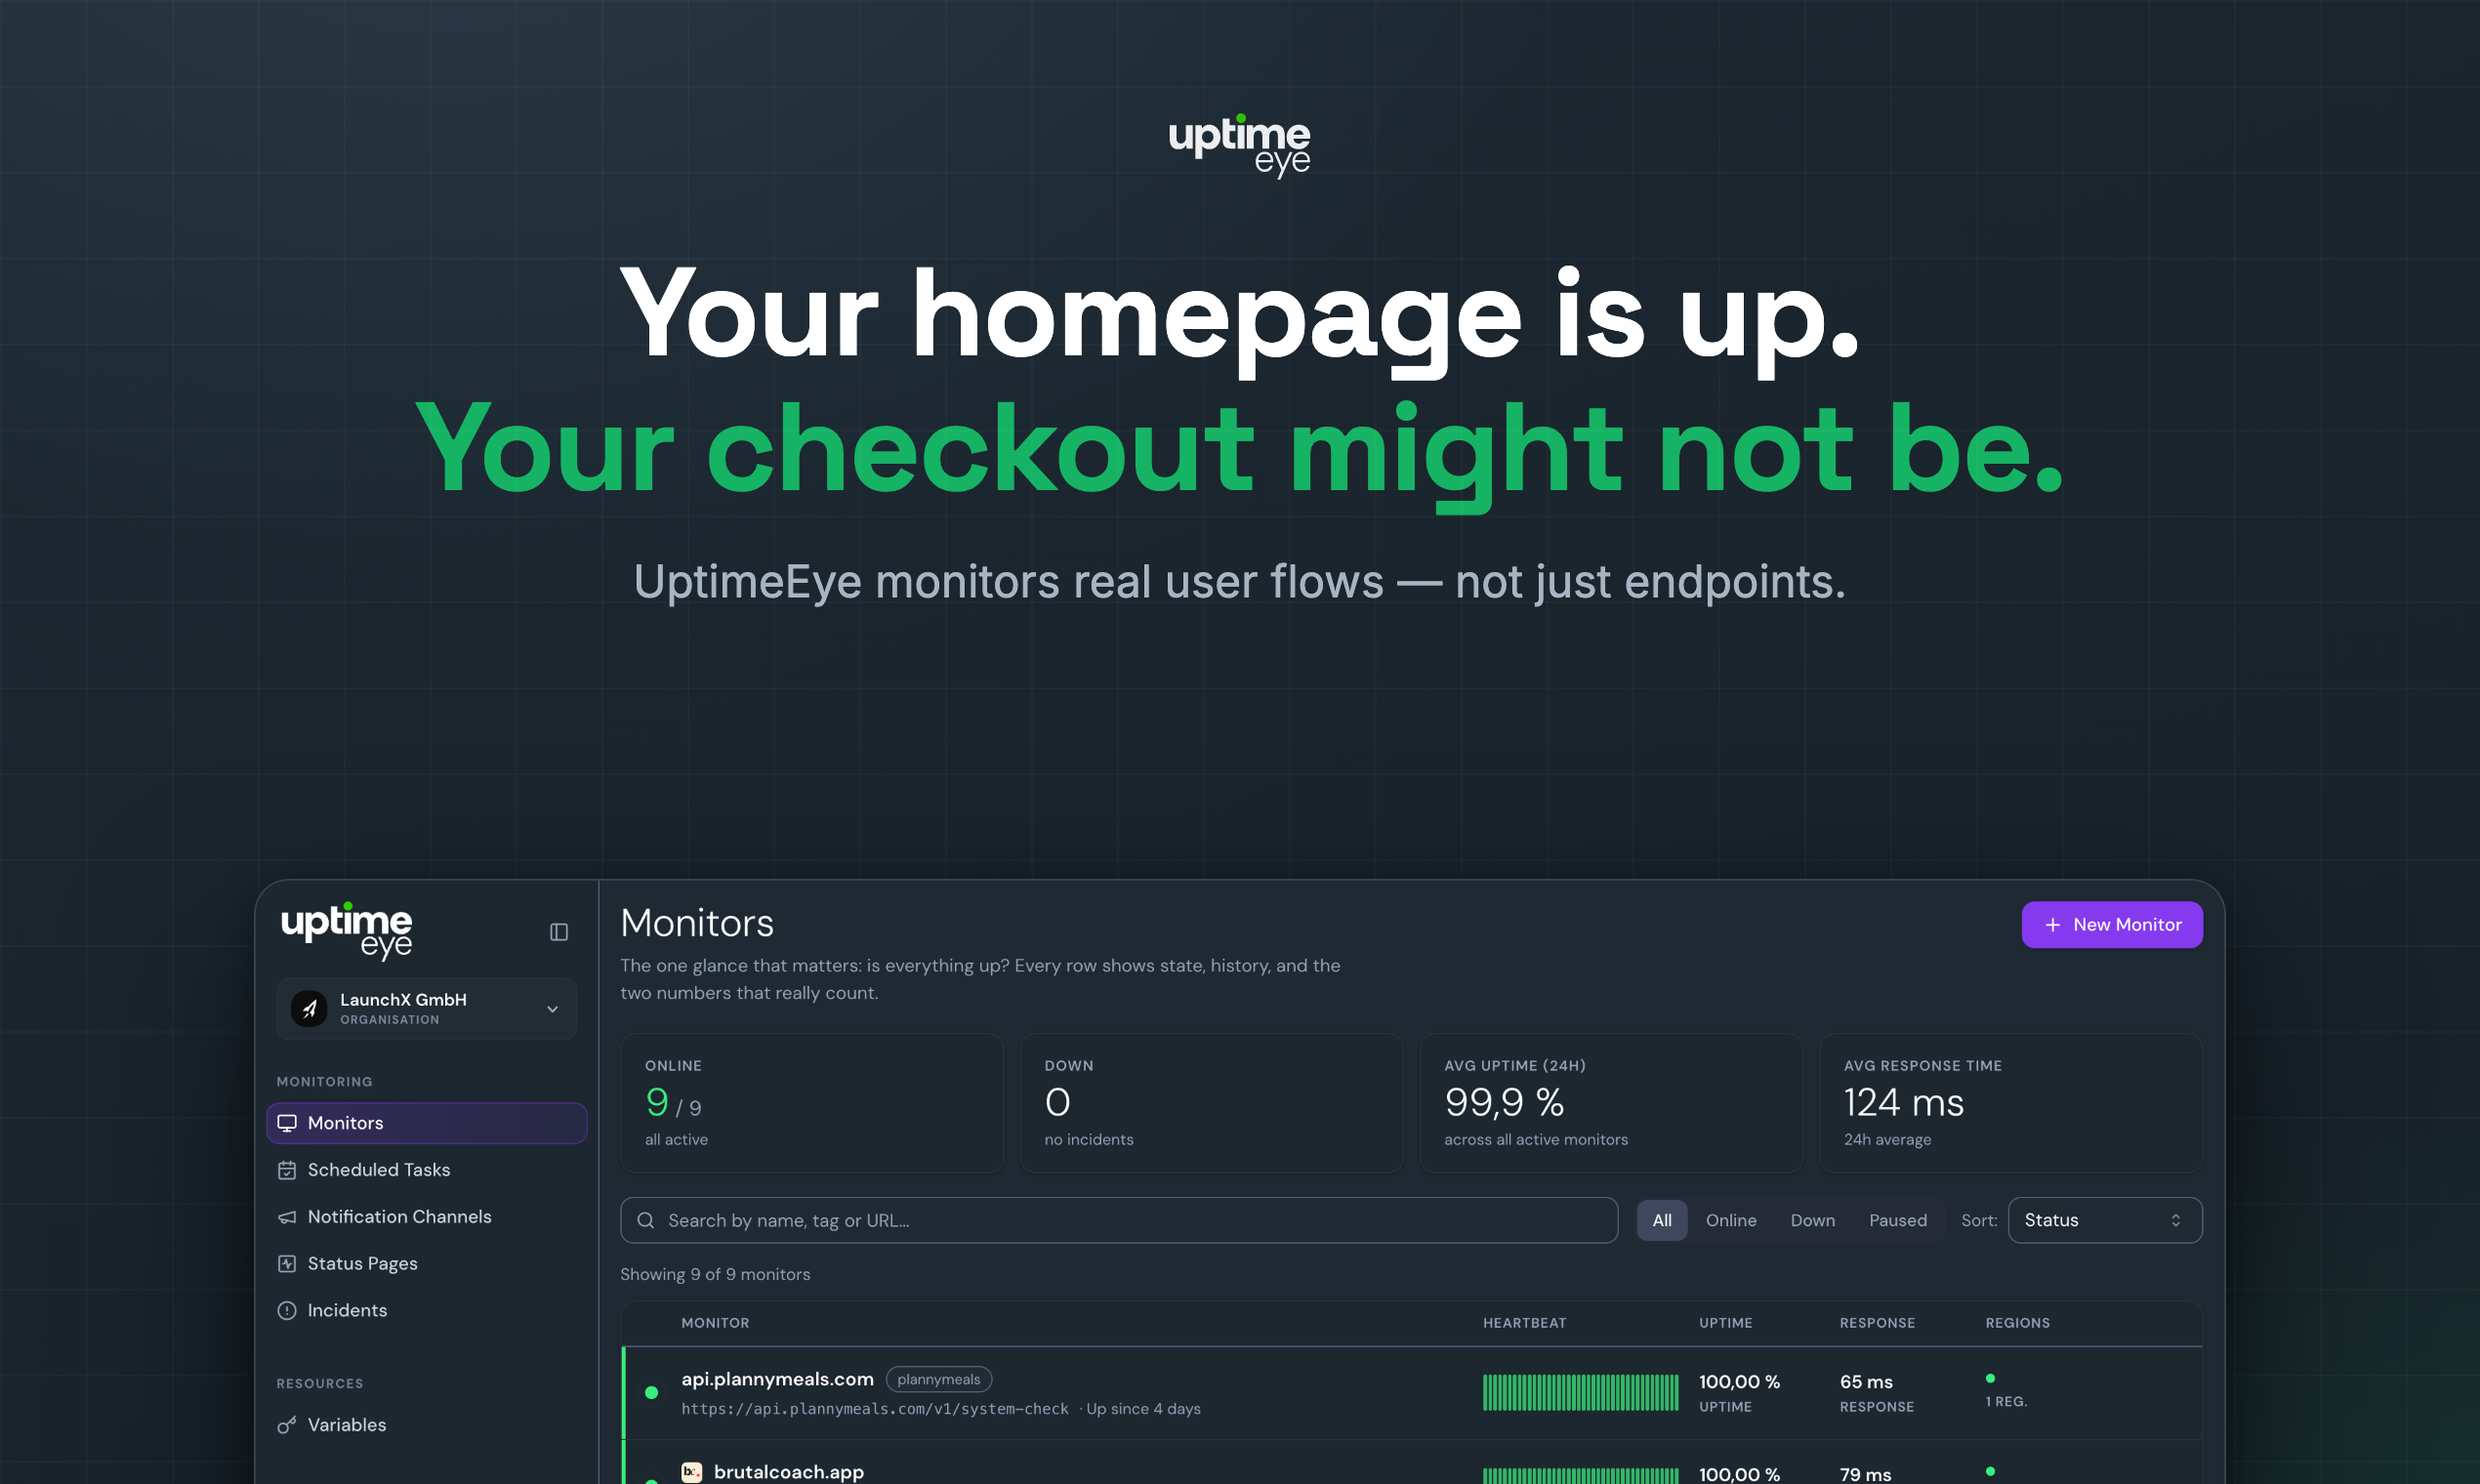
Ping monitors say "all good" while your login, checkout or API flow is silently broken. UptimeEye runs your real user flows every 30 seconds — multi-step checks, cron job monitoring, status pages, instant alerts. EU-hosted, free tier included.
Features
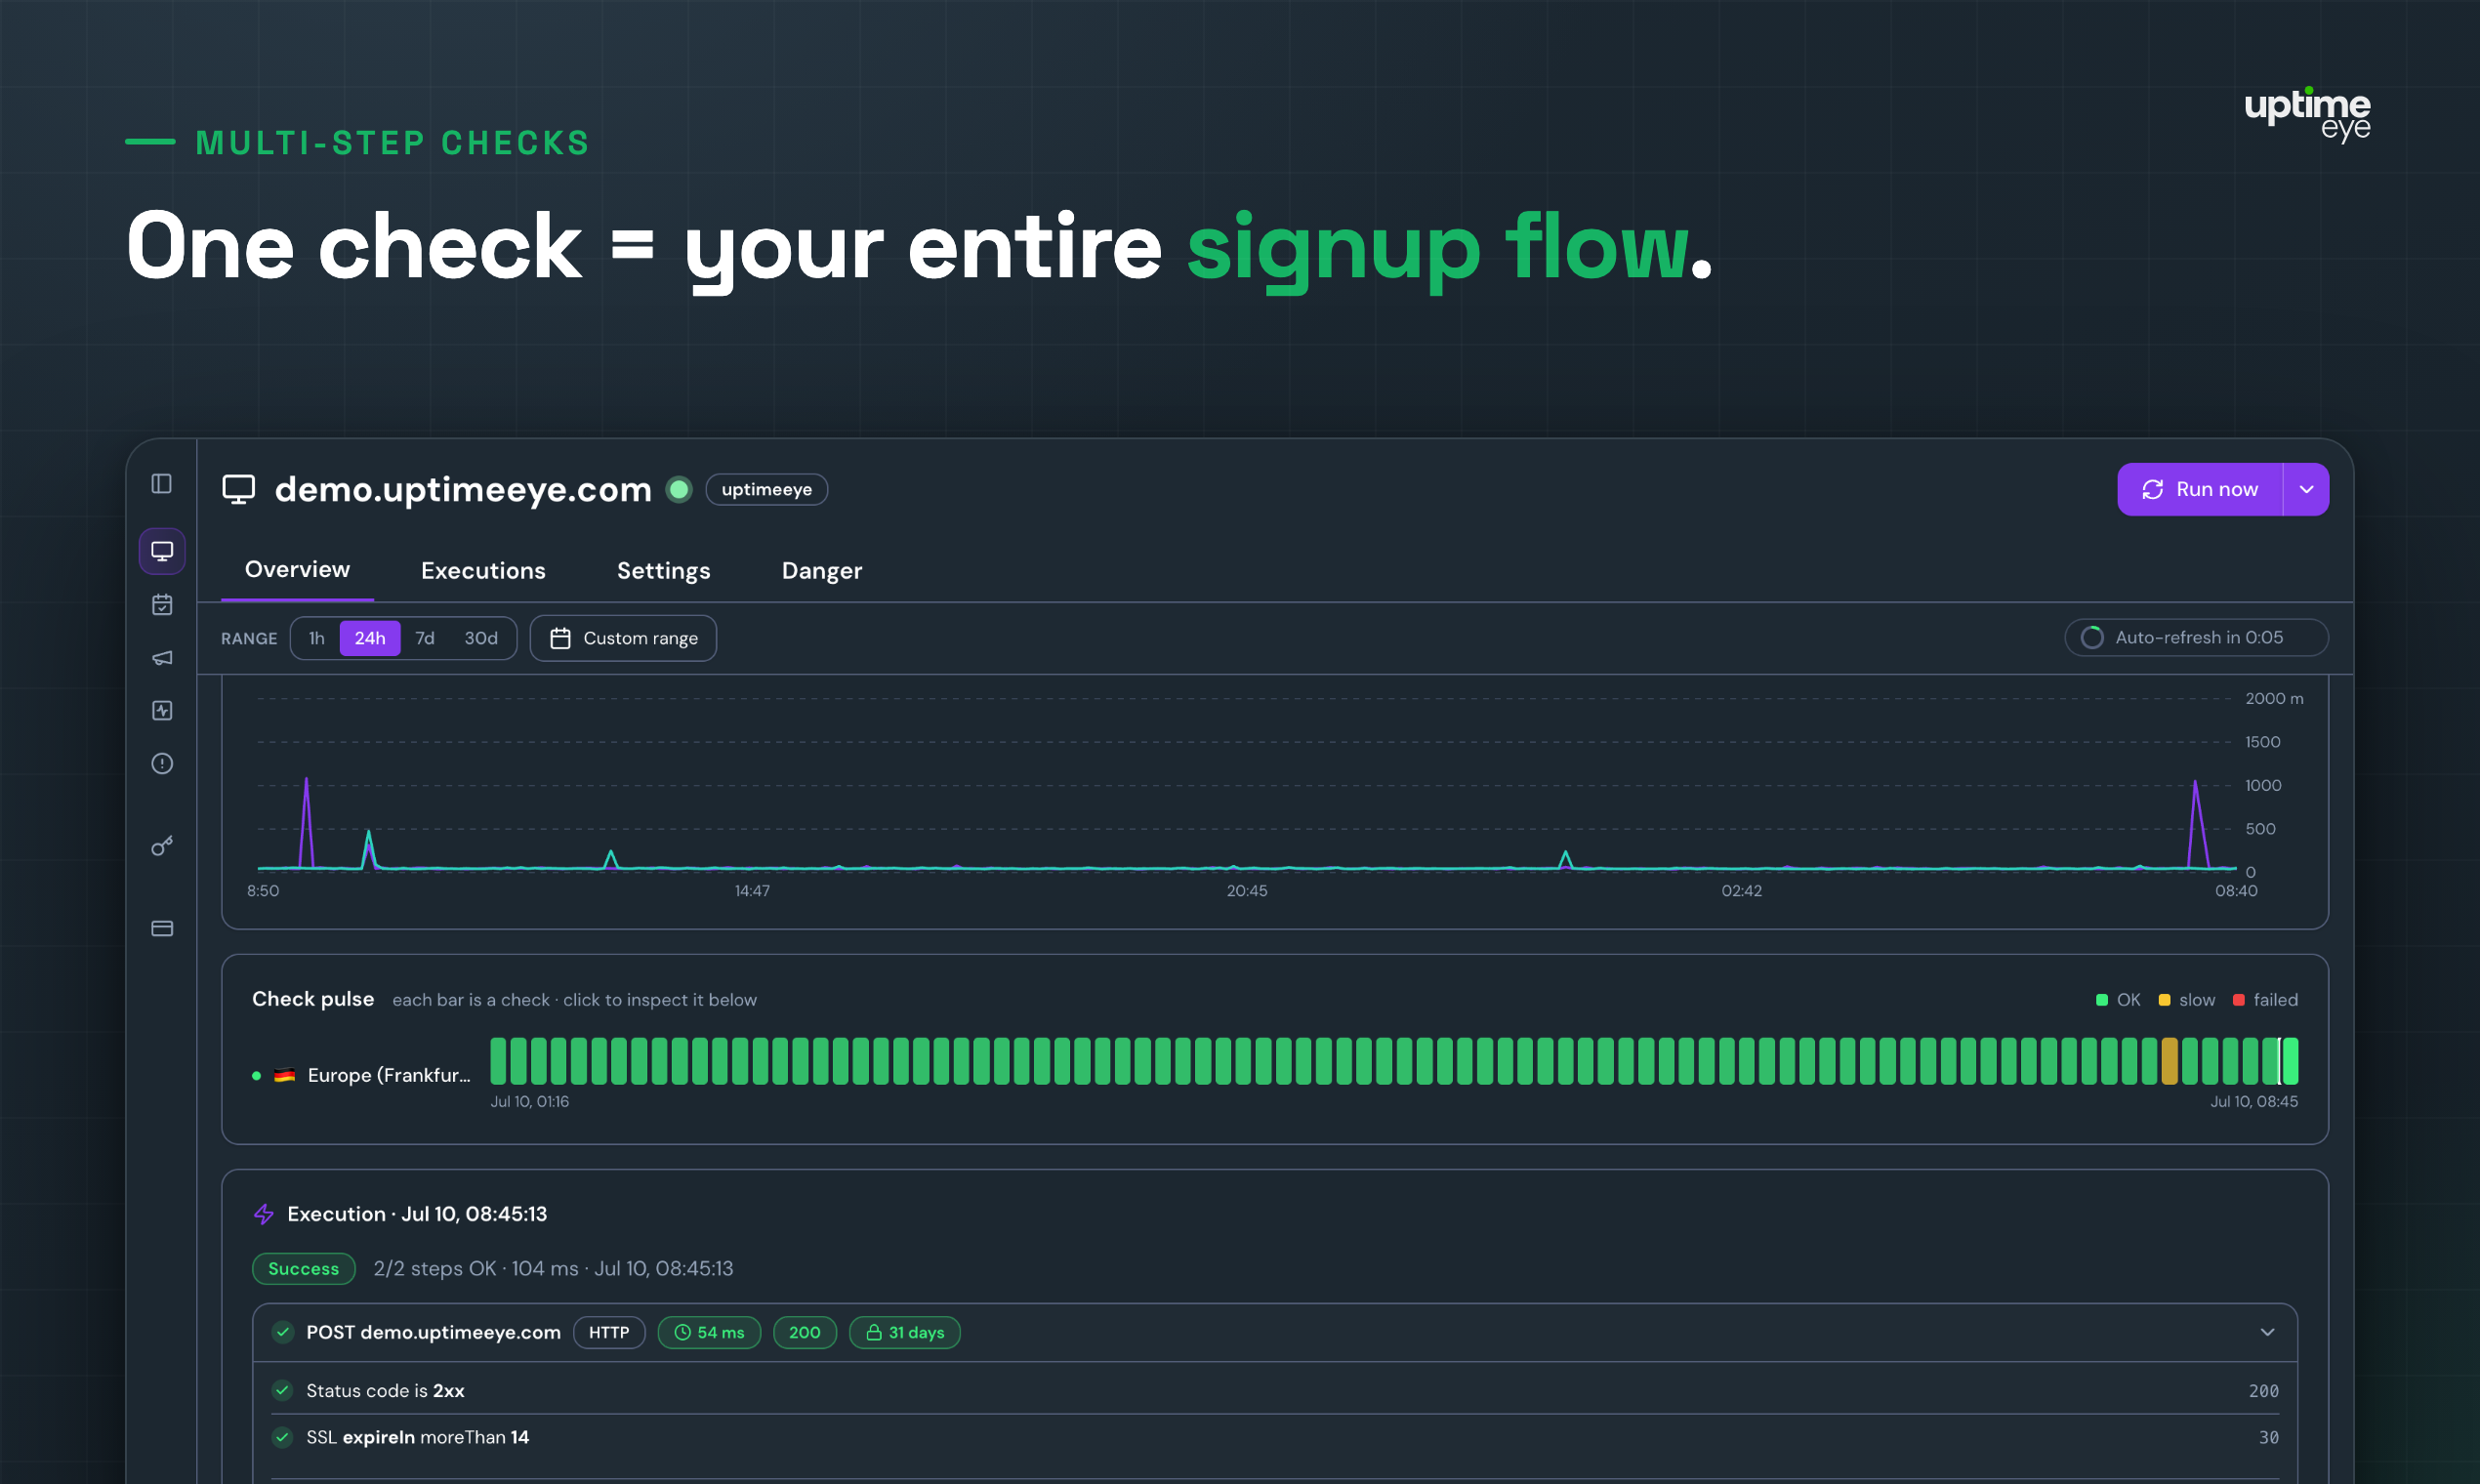
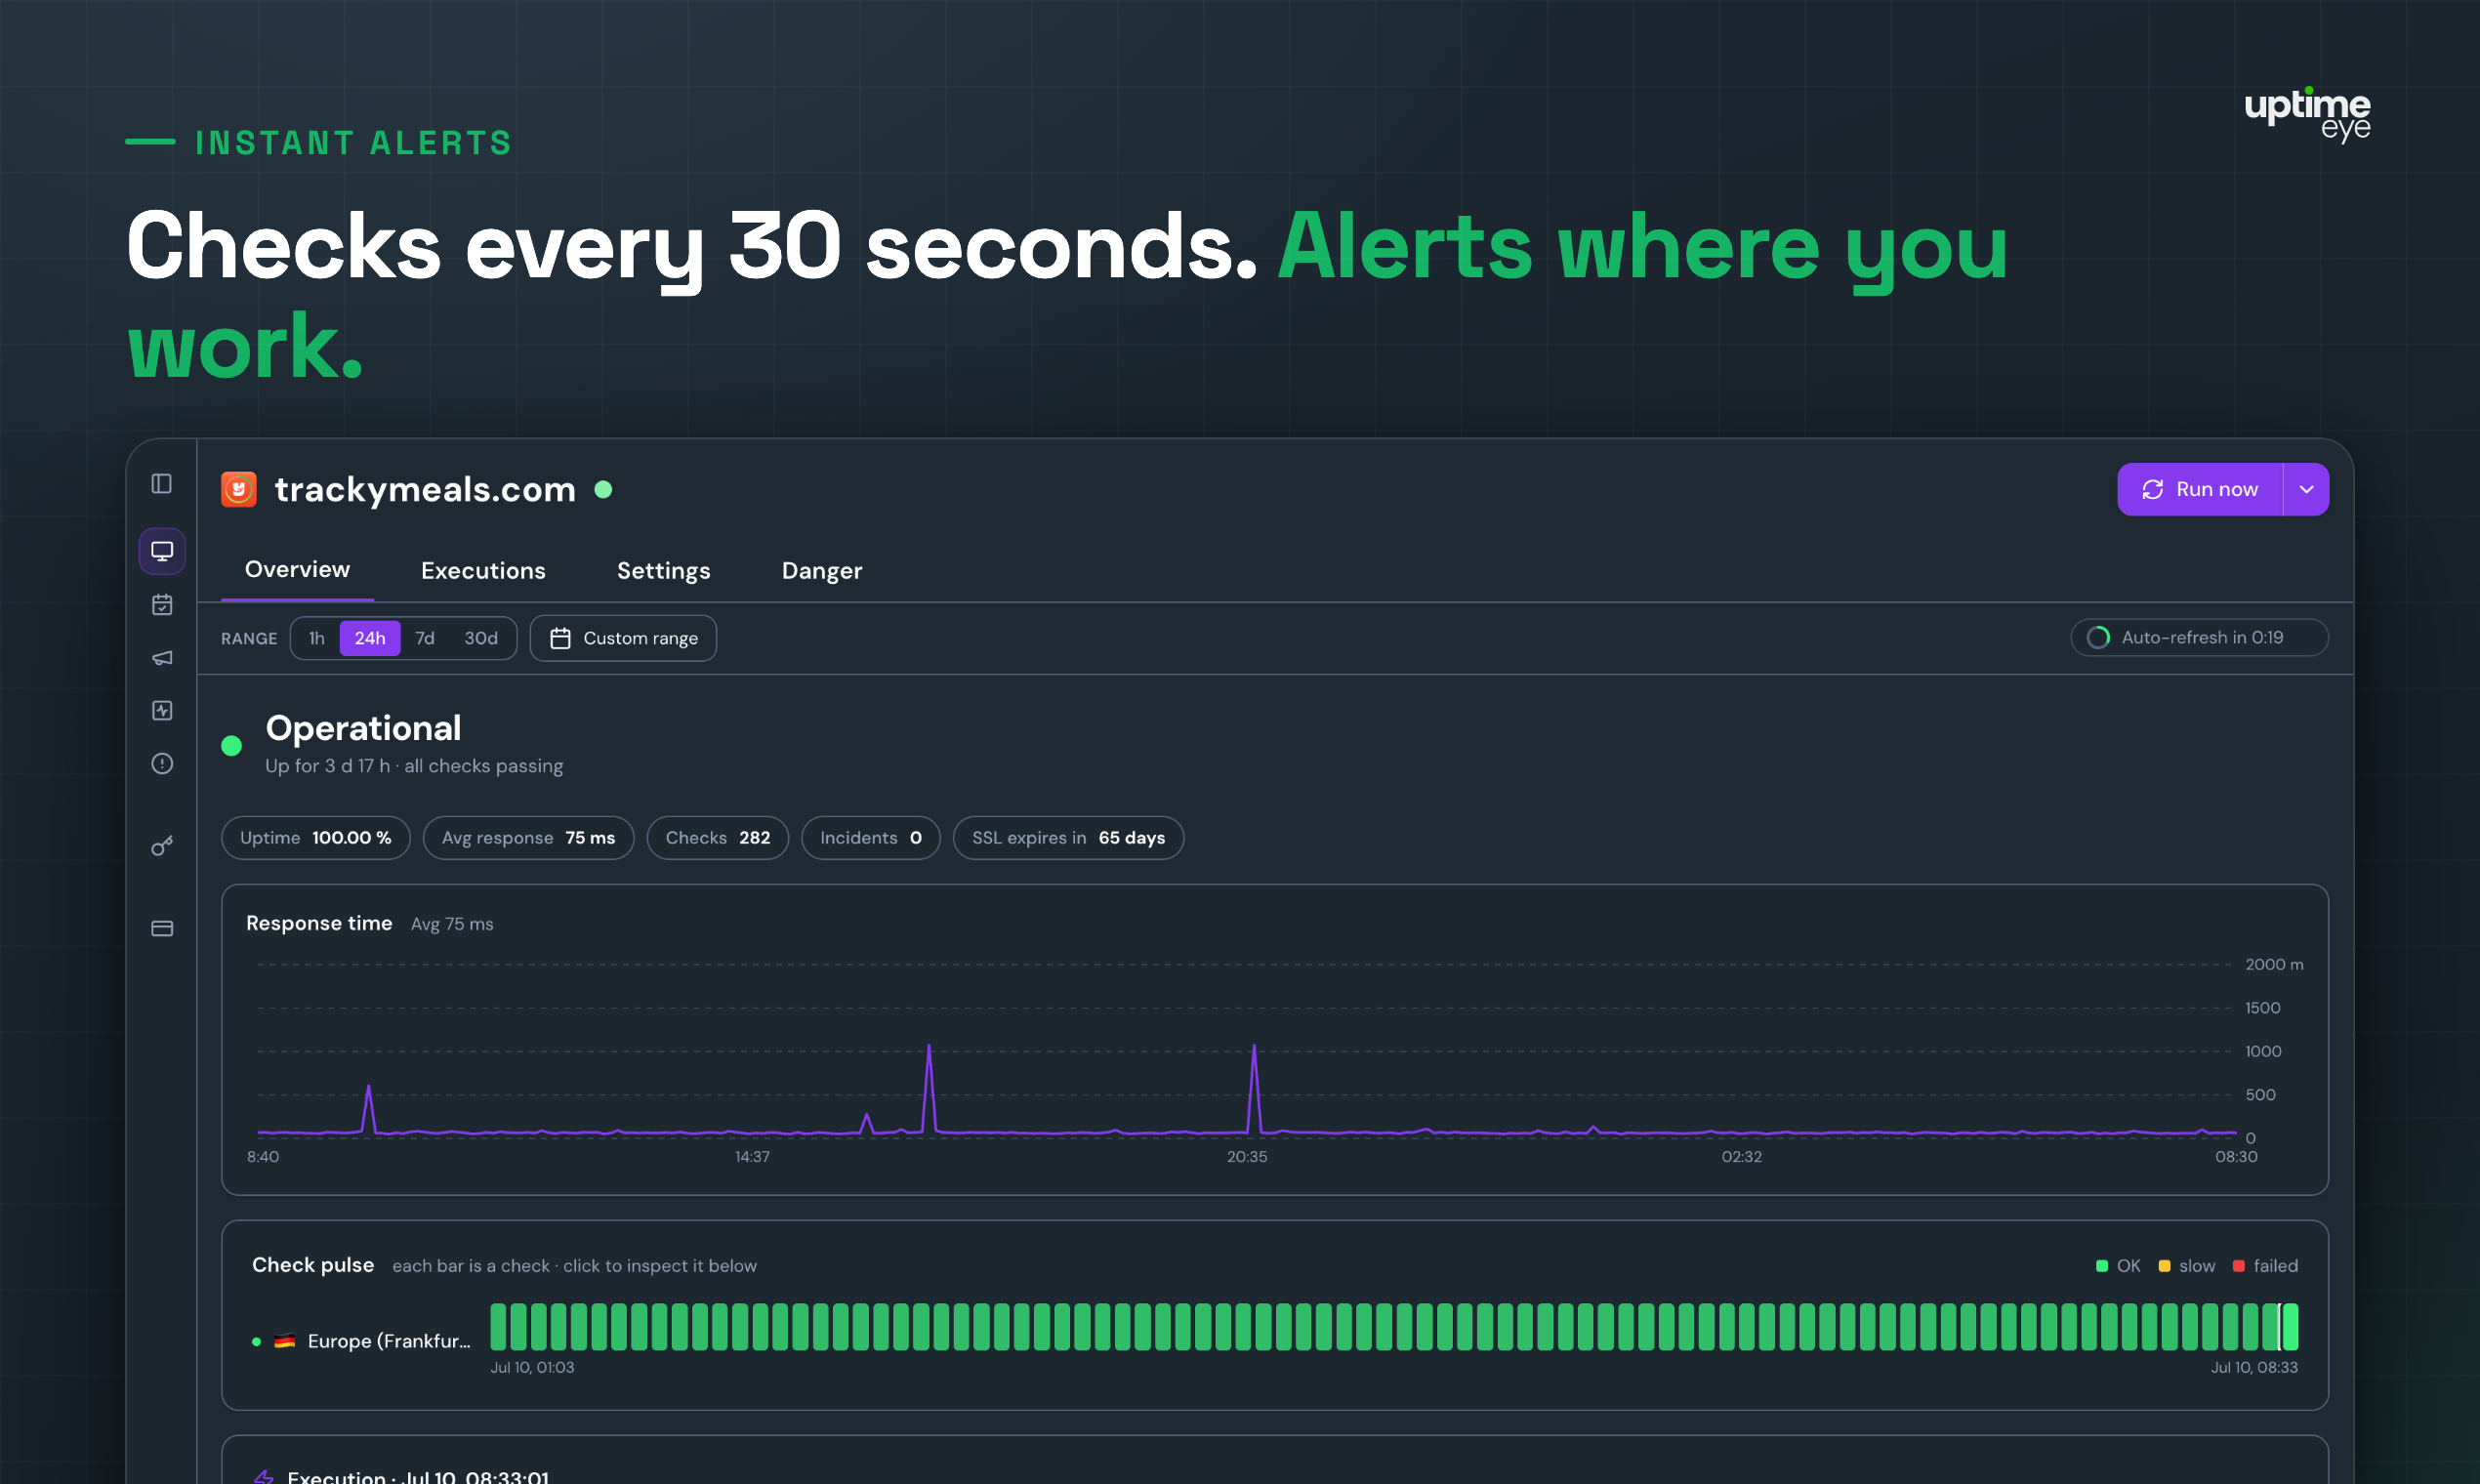
Multi-step user-flow checks (login, checkout, signup) every 30 seconds
API monitoring with assertions on status, headers and response body
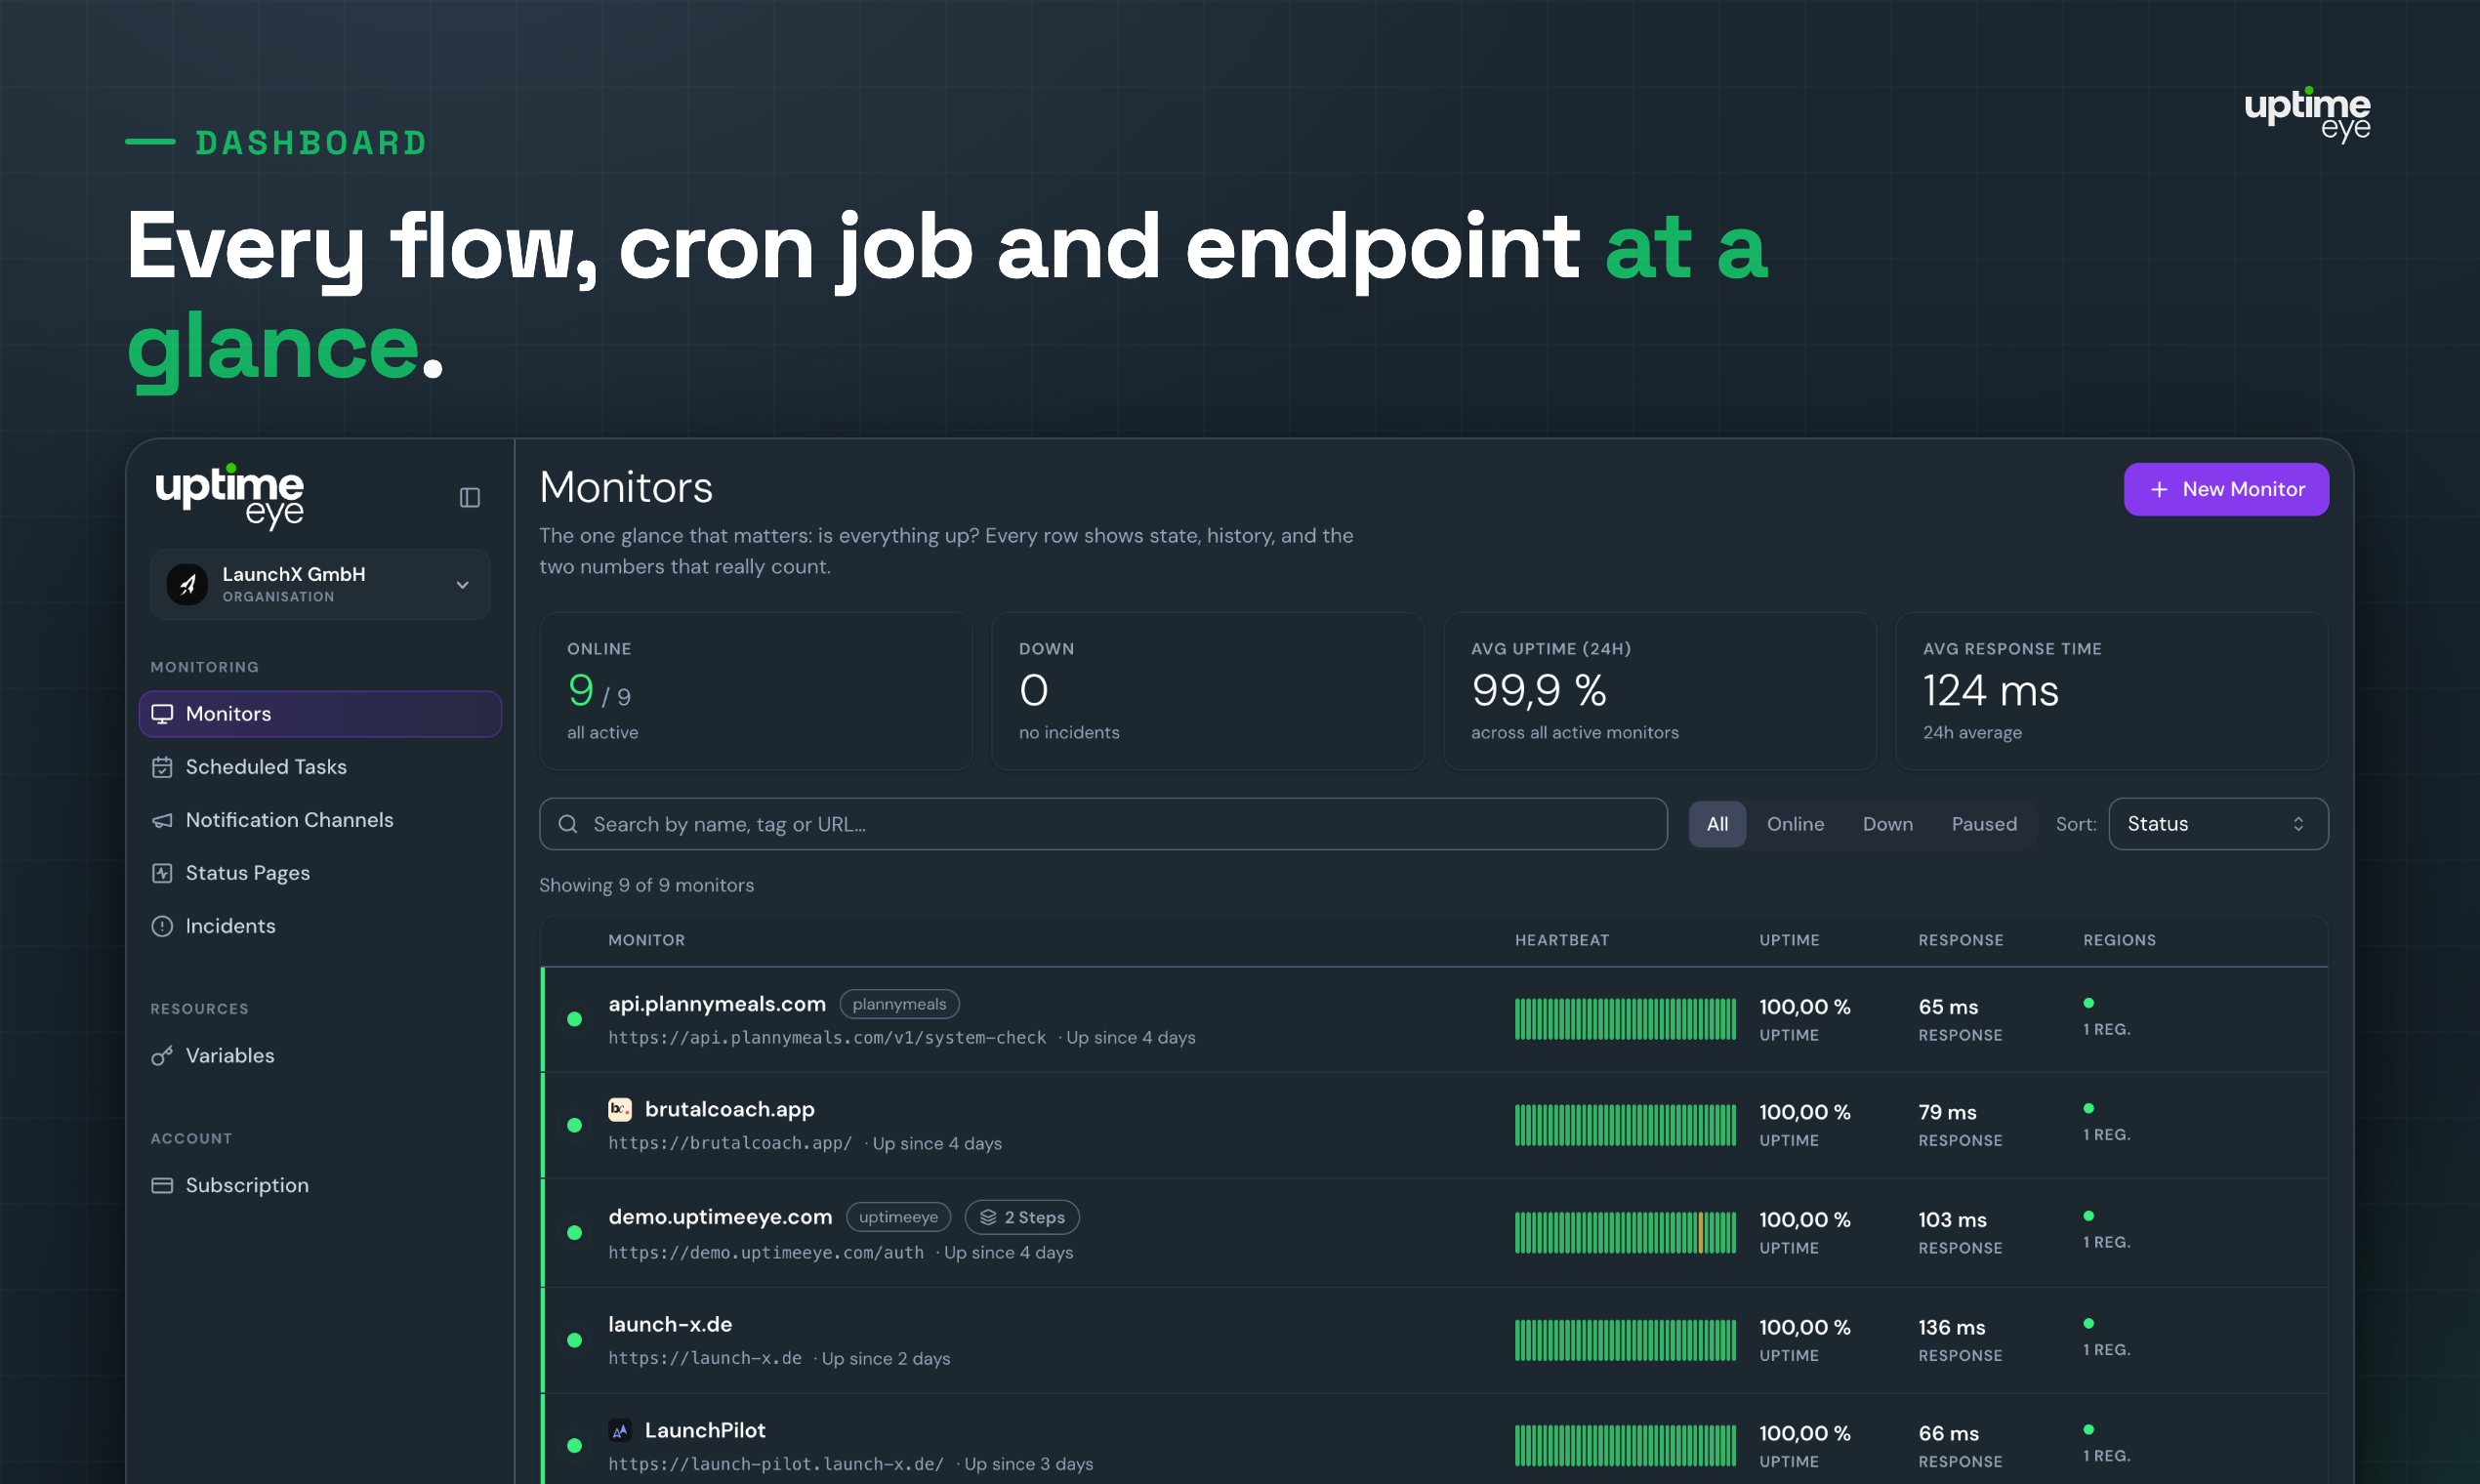
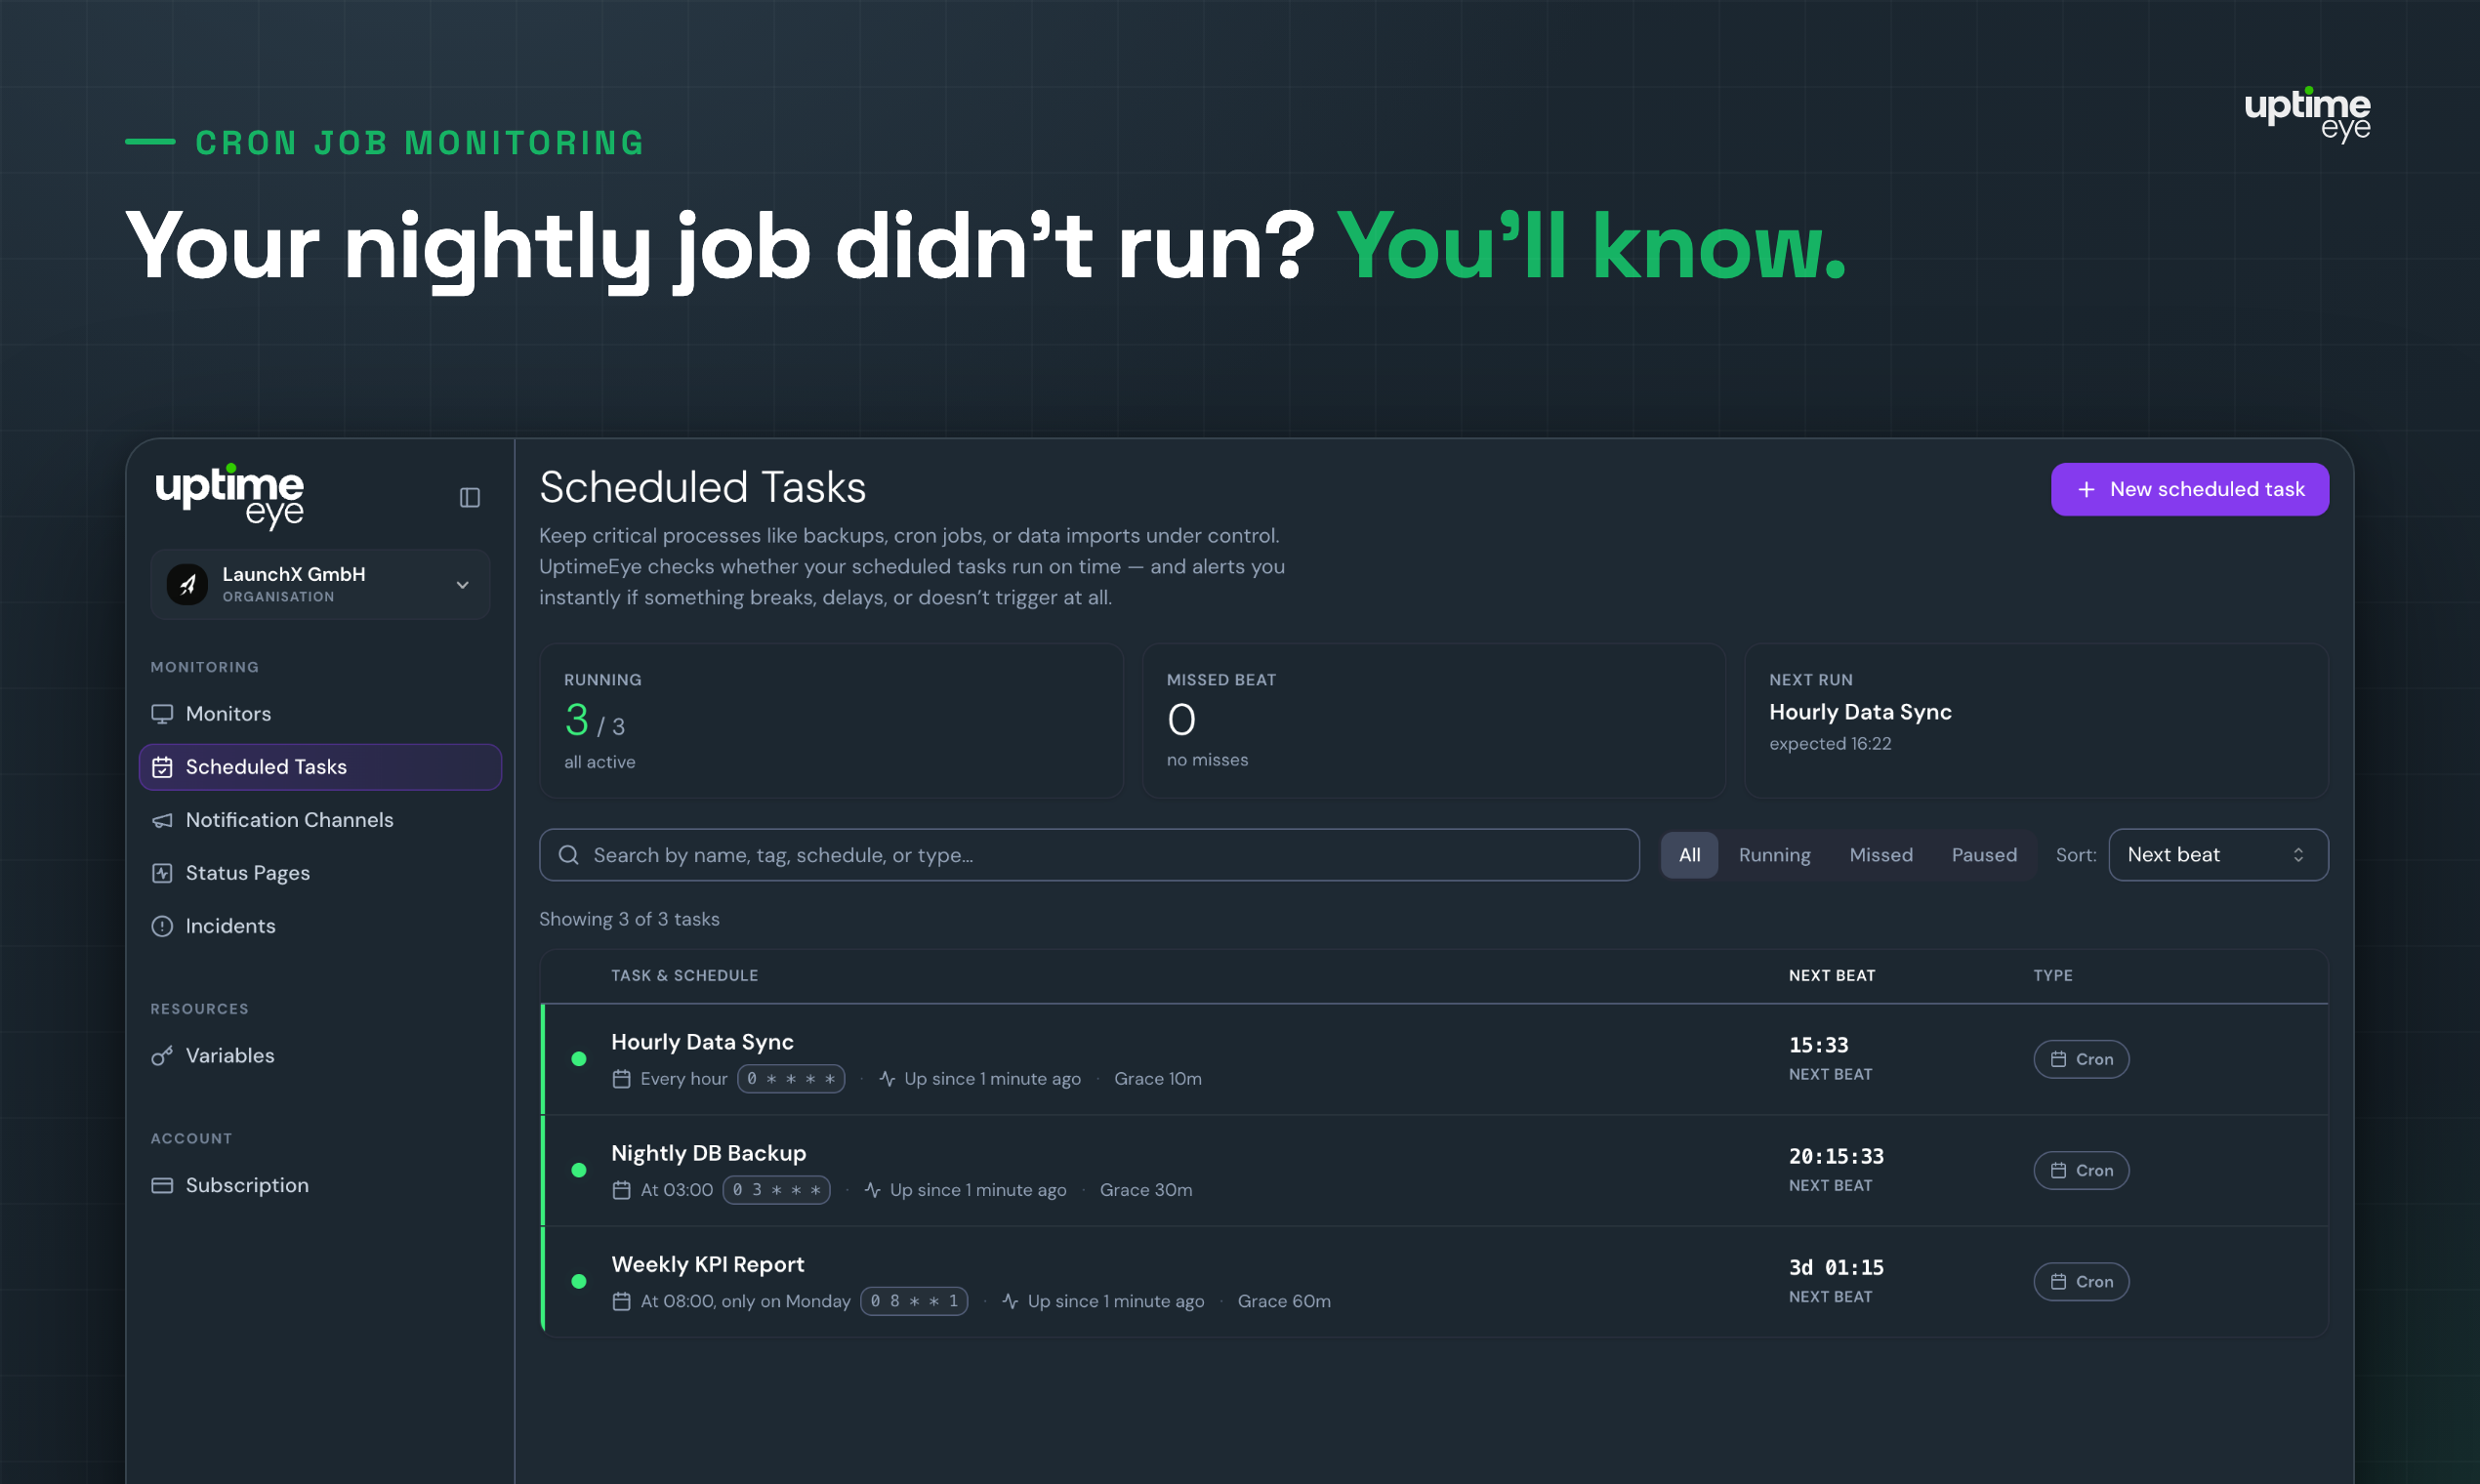
Cron job / scheduled task monitoring with heartbeat alerts
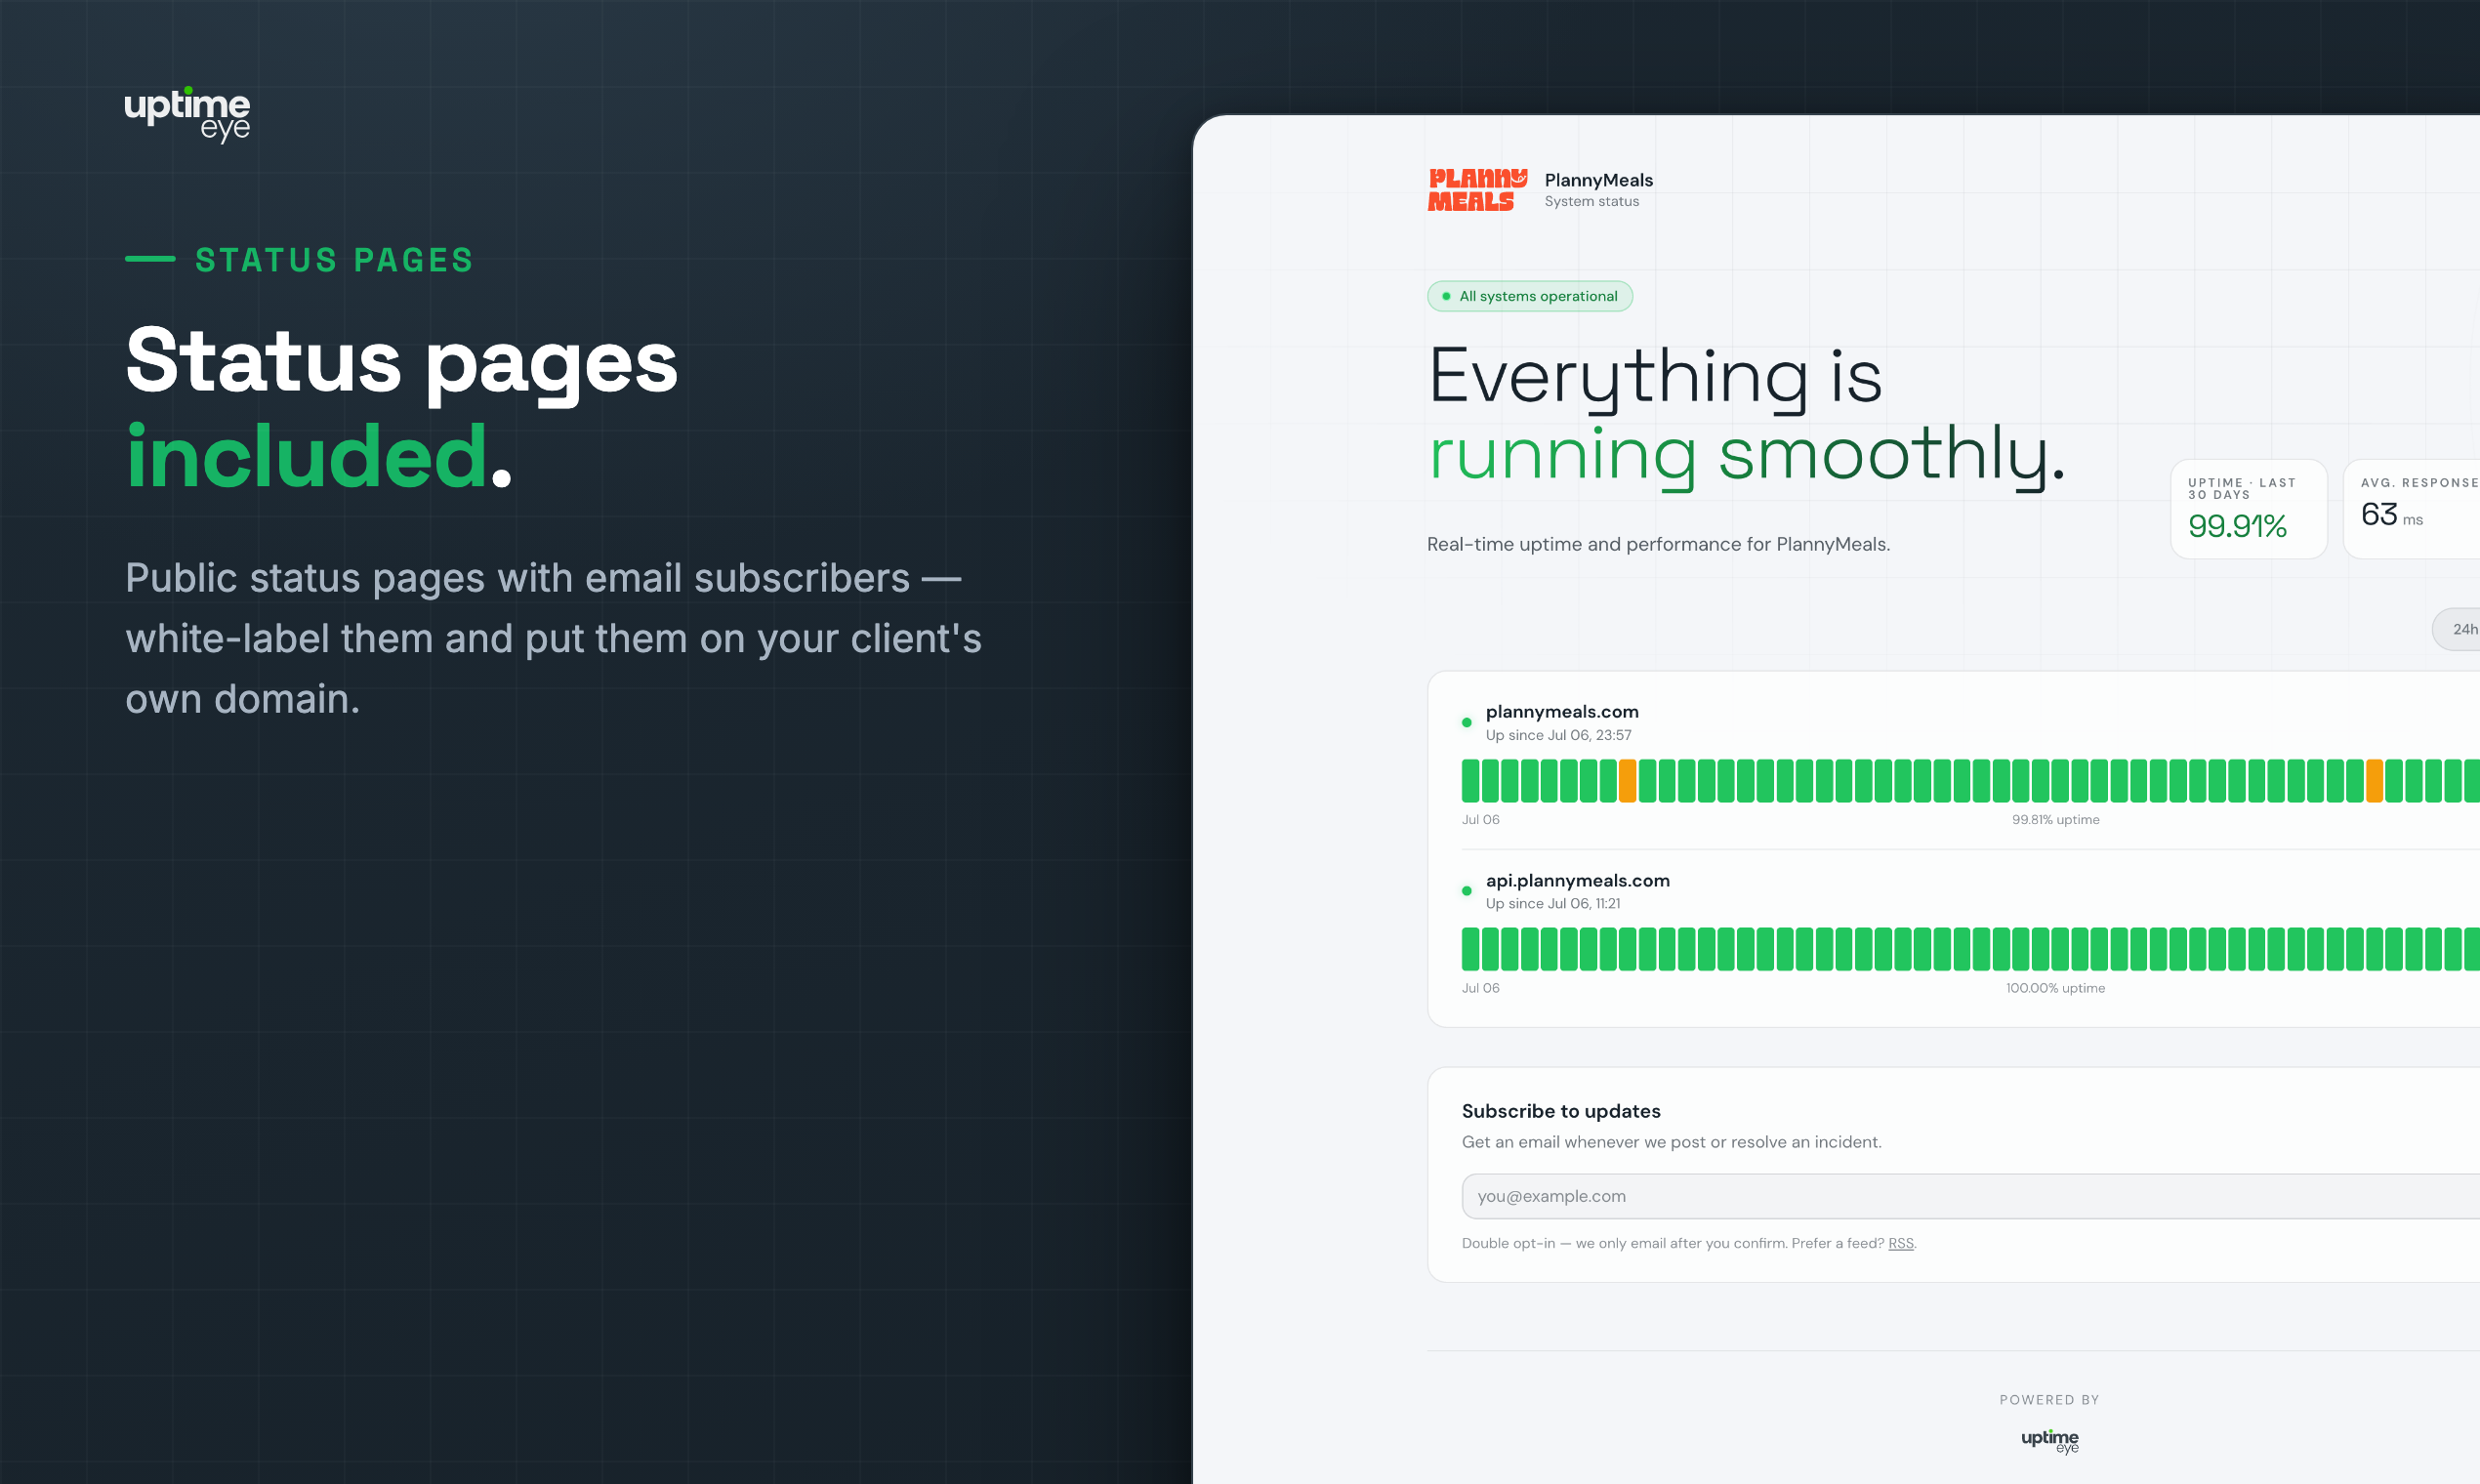
Public status pages
Instant alerts: Slack, Discord, Email, Telegram, MS Teams, PagerDuty, webhooks
Checks from up to 6 global regions, EU-hosted platform
Free tier included, no credit card required
Use Cases
Get alerted when checkout, login or signup flows break — before customers notice
Monitor REST APIs and microservices with response assertions
Catch silently failing cron jobs and scheduled backups
Give users a public status page for transparency
Agencies: monitor all client sites and flows from one account
Comments

Hi Fazier! 👋 UptimeEye exists because of a nightly job that silently stopped running on one of our own products — no error, no crash, and the uptime monitor stayed green because the homepage still returned 200. Users noticed before we did. Ping monitors can't see the things that are supposed to happen but don't. So we built UptimeEye: it runs your real user flows (login, checkout, API calls) every 30 seconds, treats cron jobs and scheduled tasks as first-class citizens, and alerts you the moment something breaks. EU-hosted, free tier included. Happy to answer anything!

Monitoring actual user flows instead of just checking for a 200 response makes a lot of sense. A homepage can be perfectly healthy while login or checkout is completely broken. I’m curious how you handle authenticated flows that involve expiring sessions or 2FA — can users periodically refresh credentials without rebuilding the whole monitor? That feels like one of the harder parts of making this reliable long-term.
The difference between checking that a server responds and checking that a user can actually complete their flow is night and day. I've been on teams where status pages said green, uptimebots said green, and users were silently getting errors on checkout or login. The 30-second heartbeat on full user flows plus cron job monitoring catches the things that traditional uptime tools miss. Real-world flows almost always have conditional branches - what if auth fails, what if the third-party payment service is slow. Having a tool that can do multi-step assertions and alert you before customers see the problem is genuinely valuable. The fact that it's EU-hosted and free tier included makes it accessible for small teams too.
What sold me on UptimeEye is the multi-step flow monitoring — it tells me exactly which step broke, not just "your site is down." Pasting a cURL command to create a monitor takes minutes, no agents or SDKs needed. The free tier allowing commercial use with all alert channels is a rare find these days

Monitoring actual user flows instead of just checking for a 200 response makes a lot of sense. A homepage can be perfectly healthy Ping monitors can't see the things that are supposed to happen but don't. So we built UptimeEye: it runs your real user flows (login, checkout, API calls) every 30 seconds

The 30-second check frequency for real user flows, APIs and cron jobs is a big differentiator — most monitoring tools miss the app-level view. Covering real user flows alongside API health means you catch broken journeys, not just dead endpoints. That is genuinely useful for small teams without a dedicated SRE.
The 30-second check frequency for real user flows, APIs and cron jobs is a big differentiator — most monitoring tools miss the app-level view. Covering real user flows alongside API health means you catch broken journeys, not just dead endpoints. That is genuinely useful for small teams without a dedicated SRE.
This one hit home. This morning our chat login died because the auth provider's project got paused: the homepage answered 200 the whole time, a ping monitor would have been green, and the only signal was a user screenshot of a DNS error. A multi-step "open app, sign in, send one message" check every 30 s is exactly what would have caught it. Two questions: can a flow step handle a third-party OAuth redirect (Google sign-in) without me storing real credentials in your dashboard, and does cron monitoring work as a heartbeat URL my job pings, so I can wire it into a nightly script in five minutes? EU hosting is a plus for us in Denmark. Congrats on the launch, signing up for the free tier now.
This solves a problem that’s easy to underestimate. A basic uptime check can tell you the server is responding while the actual user journey—login, API calls, checkout, or another multi-step flow—is completely broken. The 30-second real-flow monitoring is especially interesting because it focuses on what users actually experience, not just whether a URL returns 200. The cron job monitoring and built-in status pages make this even more useful for small teams that don’t want to build their own monitoring stack. I’m building and growing https://speakerrescue.online/ myself, so reliable monitoring is definitely something I can see the value of as a website grows. Great product idea! 🚀

Love the focus on real user flows instead of just checking whether a page returns 200. Monitoring login, checkout, APIs, and cron jobs together feels much closer to how products actually fail in production. The 30-second checks and cron heartbeat monitoring are especially useful. Curious how you handle flaky multi-step flows — do you retry before triggering an alert to avoid false positives? Congrats on the launch!
The 30s interval for cron jobs is the part that stands out — most uptime tools only ping URLs. We run a nightly transcription cron on our project and the real failure mode is always "it silently didn't run", not "the site is down". Does UptimeEye support dead-man-switch style checks (alerting when a job DIDN'T report in), or is it active polling only?

Multi-step flow checks are exactly what ping monitors miss. We had our Stripe checkout return path deadlock the buy buttons for a day while every uptime ping stayed green, and only a user report caught it. Question: for a flow that ends on a third-party page (Stripe Checkout), can a step assert on the redirect host/URL instead of having to complete a payment? And for the cron heartbeats, is there a grace window for jobs with variable runtime, or is it a fixed interval?

Multi-step flow checks every 30s is the right wedge, since a 200 on the homepage says nothing about a broken checkout. The thing I would want documented up front is how you handle flaky-run noise: does a failing step retry from a second region before it pages, and can I see the failing step's screenshot or response body in the alert itself? That detail is usually what decides whether teams keep the alerts on.
The nightly-job story in your intro hits home. We run an hourly cleanup cron on Cloudflare Workers for MoeMail (expiring temp mailboxes + reconciling Stripe payments), and a silent failure there would look exactly like "all green" to a ping monitor. Two questions: does the heartbeat monitor support a per-job expected interval with a grace window (hourly job, alert if no ping within ~75 min)? And in multi-step API checks, can an assertion reference a value from a previous step's response body (create mailbox -> poll inbox -> assert the message arrived)? That's the flow we'd actually want to watch.

"Your homepage is up, your checkout might not be" is the right framing, and the nastiest version of it is state-dependent. A Monthly/Annual toggle rewrites the CTA, the price text updates correctly, and the link behind it now points at a plan key checkout does not accept. The default view tests clean, so every ping monitor and every visual check passes, and it only hits the annual buyer, who is your highest-value one. One request: make the multi-step check assert the checkout page's own order summary, the plan name and amount due today, not just a 200 on the page. A checkout that opens is not a checkout that charges the right thing. Worth running the flow logged out too, since being signed in hides plan gating.
The cron-as-first-class-citizen framing is what stands out to me. I run a give-first proof exchange where an embeddable widget snippet sits on other people's landing pages — a silent script failure there wouldn't touch my own uptime at all, a ping monitor on my domain would stay green, but everyone who embedded the widget would just see a blank box. Could a check assert against a selector/text inside a *third-party* page that loads your script, or is monitoring scoped to endpoints you control directly?
The framing in your first line is the right one, and I would push it one step further than login and checkout. We run a background worker that renders content and then publishes it. Two outages, neither of which a ping monitor or a plain heartbeat would have caught. The first: the render stage runs before the publish stage in the same loop. When publishing broke, the process stayed up and the loop kept turning, so the heartbeat was green the whole time. It looked busier than usual, because work was piling up at the stage that had stopped. What we needed was not "did the job run" but "did the count of things that reached the final state go up since the last check". A heartbeat that only proves the process is alive tells you almost nothing about a multi-stage pipeline. The second: a commit that was never pushed. The platform deploys from the repo, so the worker was healthy, heartbeating, and running two-day-old code. Two days before anyone noticed. Do your cron monitors let a heartbeat carry a payload you can assert on, the way your API checks assert on a response body? Something like "the deployed commit is X" or "processed 4 items this cycle", with an alert when the value stops moving rather than when the ping stops arriving. That is the check I would have paid for, and I have not found it in the usual tools.

UptimeEye Your product has strong potential, but I found a few key improvements that could make it even better. I'd love to share my feedback and suggestions—please contact me at [email protected].
Premium Products




Sponsors
Buy
Makers
Makers
Comments
Hi Fazier! 👋 UptimeEye exists because of a nightly job that silently stopped running on one of our own products — no error, no crash, and the uptime monitor stayed green because the homepage still returned 200. Users noticed before we did. Ping monitors can't see the things that are supposed to happen but don't. So we built UptimeEye: it runs your real user flows (login, checkout, API calls) every 30 seconds, treats cron jobs and scheduled tasks as first-class citizens, and alerts you the moment something breaks. EU-hosted, free tier included. Happy to answer anything!
Monitoring actual user flows instead of just checking for a 200 response makes a lot of sense. A homepage can be perfectly healthy while login or checkout is completely broken. I’m curious how you handle authenticated flows that involve expiring sessions or 2FA — can users periodically refresh credentials without rebuilding the whole monitor? That feels like one of the harder parts of making this reliable long-term.
The difference between checking that a server responds and checking that a user can actually complete their flow is night and day. I've been on teams where status pages said green, uptimebots said green, and users were silently getting errors on checkout or login. The 30-second heartbeat on full user flows plus cron job monitoring catches the things that traditional uptime tools miss. Real-world flows almost always have conditional branches - what if auth fails, what if the third-party payment service is slow. Having a tool that can do multi-step assertions and alert you before customers see the problem is genuinely valuable. The fact that it's EU-hosted and free tier included makes it accessible for small teams too.
What sold me on UptimeEye is the multi-step flow monitoring — it tells me exactly which step broke, not just "your site is down." Pasting a cURL command to create a monitor takes minutes, no agents or SDKs needed. The free tier allowing commercial use with all alert channels is a rare find these days
Monitoring actual user flows instead of just checking for a 200 response makes a lot of sense. A homepage can be perfectly healthy Ping monitors can't see the things that are supposed to happen but don't. So we built UptimeEye: it runs your real user flows (login, checkout, API calls) every 30 seconds
The 30-second check frequency for real user flows, APIs and cron jobs is a big differentiator — most monitoring tools miss the app-level view. Covering real user flows alongside API health means you catch broken journeys, not just dead endpoints. That is genuinely useful for small teams without a dedicated SRE.
The 30-second check frequency for real user flows, APIs and cron jobs is a big differentiator — most monitoring tools miss the app-level view. Covering real user flows alongside API health means you catch broken journeys, not just dead endpoints. That is genuinely useful for small teams without a dedicated SRE.
This one hit home. This morning our chat login died because the auth provider's project got paused: the homepage answered 200 the whole time, a ping monitor would have been green, and the only signal was a user screenshot of a DNS error. A multi-step "open app, sign in, send one message" check every 30 s is exactly what would have caught it. Two questions: can a flow step handle a third-party OAuth redirect (Google sign-in) without me storing real credentials in your dashboard, and does cron monitoring work as a heartbeat URL my job pings, so I can wire it into a nightly script in five minutes? EU hosting is a plus for us in Denmark. Congrats on the launch, signing up for the free tier now.
This solves a problem that’s easy to underestimate. A basic uptime check can tell you the server is responding while the actual user journey—login, API calls, checkout, or another multi-step flow—is completely broken. The 30-second real-flow monitoring is especially interesting because it focuses on what users actually experience, not just whether a URL returns 200. The cron job monitoring and built-in status pages make this even more useful for small teams that don’t want to build their own monitoring stack. I’m building and growing https://speakerrescue.online/ myself, so reliable monitoring is definitely something I can see the value of as a website grows. Great product idea! 🚀
Love the focus on real user flows instead of just checking whether a page returns 200. Monitoring login, checkout, APIs, and cron jobs together feels much closer to how products actually fail in production. The 30-second checks and cron heartbeat monitoring are especially useful. Curious how you handle flaky multi-step flows — do you retry before triggering an alert to avoid false positives? Congrats on the launch!
The 30s interval for cron jobs is the part that stands out — most uptime tools only ping URLs. We run a nightly transcription cron on our project and the real failure mode is always "it silently didn't run", not "the site is down". Does UptimeEye support dead-man-switch style checks (alerting when a job DIDN'T report in), or is it active polling only?
Multi-step flow checks are exactly what ping monitors miss. We had our Stripe checkout return path deadlock the buy buttons for a day while every uptime ping stayed green, and only a user report caught it. Question: for a flow that ends on a third-party page (Stripe Checkout), can a step assert on the redirect host/URL instead of having to complete a payment? And for the cron heartbeats, is there a grace window for jobs with variable runtime, or is it a fixed interval?
Multi-step flow checks every 30s is the right wedge, since a 200 on the homepage says nothing about a broken checkout. The thing I would want documented up front is how you handle flaky-run noise: does a failing step retry from a second region before it pages, and can I see the failing step's screenshot or response body in the alert itself? That detail is usually what decides whether teams keep the alerts on.
The nightly-job story in your intro hits home. We run an hourly cleanup cron on Cloudflare Workers for MoeMail (expiring temp mailboxes + reconciling Stripe payments), and a silent failure there would look exactly like "all green" to a ping monitor. Two questions: does the heartbeat monitor support a per-job expected interval with a grace window (hourly job, alert if no ping within ~75 min)? And in multi-step API checks, can an assertion reference a value from a previous step's response body (create mailbox -> poll inbox -> assert the message arrived)? That's the flow we'd actually want to watch.
"Your homepage is up, your checkout might not be" is the right framing, and the nastiest version of it is state-dependent. A Monthly/Annual toggle rewrites the CTA, the price text updates correctly, and the link behind it now points at a plan key checkout does not accept. The default view tests clean, so every ping monitor and every visual check passes, and it only hits the annual buyer, who is your highest-value one. One request: make the multi-step check assert the checkout page's own order summary, the plan name and amount due today, not just a 200 on the page. A checkout that opens is not a checkout that charges the right thing. Worth running the flow logged out too, since being signed in hides plan gating.
The cron-as-first-class-citizen framing is what stands out to me. I run a give-first proof exchange where an embeddable widget snippet sits on other people's landing pages — a silent script failure there wouldn't touch my own uptime at all, a ping monitor on my domain would stay green, but everyone who embedded the widget would just see a blank box. Could a check assert against a selector/text inside a *third-party* page that loads your script, or is monitoring scoped to endpoints you control directly?
The framing in your first line is the right one, and I would push it one step further than login and checkout. We run a background worker that renders content and then publishes it. Two outages, neither of which a ping monitor or a plain heartbeat would have caught. The first: the render stage runs before the publish stage in the same loop. When publishing broke, the process stayed up and the loop kept turning, so the heartbeat was green the whole time. It looked busier than usual, because work was piling up at the stage that had stopped. What we needed was not "did the job run" but "did the count of things that reached the final state go up since the last check". A heartbeat that only proves the process is alive tells you almost nothing about a multi-stage pipeline. The second: a commit that was never pushed. The platform deploys from the repo, so the worker was healthy, heartbeating, and running two-day-old code. Two days before anyone noticed. Do your cron monitors let a heartbeat carry a payload you can assert on, the way your API checks assert on a response body? Something like "the deployed commit is X" or "processed 4 items this cycle", with an alert when the value stops moving rather than when the ping stops arriving. That is the check I would have paid for, and I have not found it in the usual tools.
UptimeEye Your product has strong potential, but I found a few key improvements that could make it even better. I'd love to share my feedback and suggestions—please contact me at [email protected].
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2025. All Rights Reserved