Throttle
Cut LLM costs
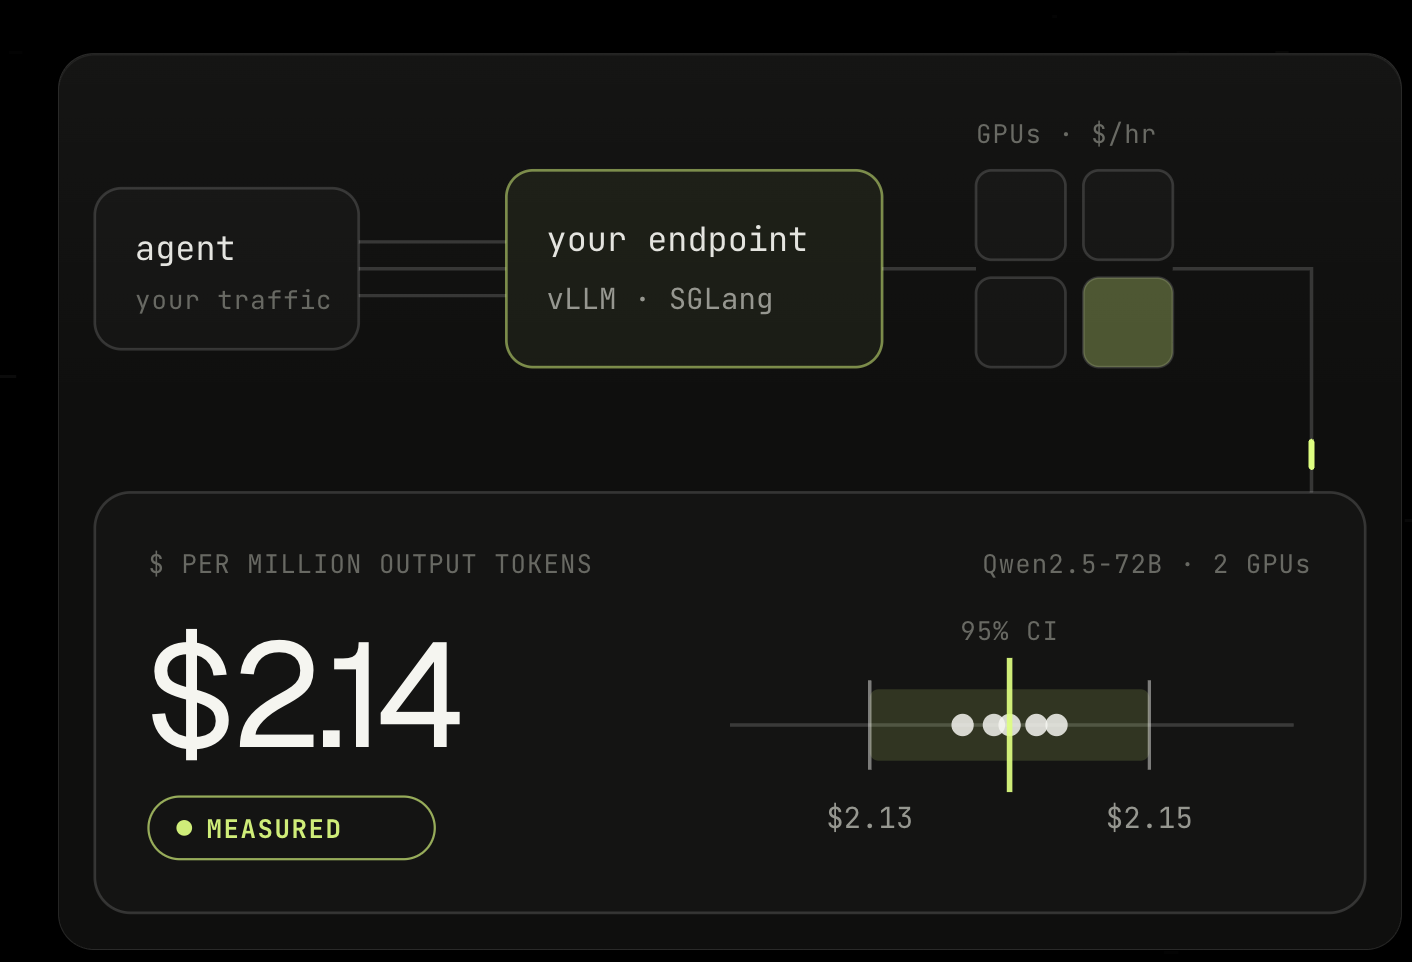
Throttle shows you where your LLM inference money actually goes. Point it at your vLLM, SGLang, Ollama or LMDeploy setup, no code changes, and it measures your traffic, finds the waste, and tells you which config changes will save you money.
iNSTALL IN ONE LINE!!
Features
- Works with vLLM, SGLang, Ollama and LMDeploy
- Measures throughput, latency and cost per million tokens
- Diagnoses whether you’re bottlenecked on memory or dispatch
- Profiles agent sessions to show idle GPU time during tool calls
- Benchmarks configs with real confidence intervals, not guesses
- Open source: pipx install throttle pro
Use Cases
- Cutting the GPU bill on a self hosted model
- Picking the right batch size before you scale up
- Figuring out why your agent workloads are so expensive
- Comparing serving stacks on your own traffic
- Proving savings to your team with real numbers
Fazier Deal
Comments


Hi Fazier, I’m Kush, founder of Throttle. AI is getting cheaper, but running it still isn’t. Most teams are overpaying for their models and can’t see why. Throttle shows you exactly where your AI spend is going and how to cut it. No guesswork, no code changes. In our first test, a single change delivered 3x more output from the same hardware. Spend less. Run more. That’s Throttle. It’s free and open source. If you’re running AI in production, comment below and I’ll personally help you find your savings.
Premium Products


Fazier Deal
Sponsors
Buy
Makers
Makers
Comments
Hi Fazier, I’m Kush, founder of Throttle. AI is getting cheaper, but running it still isn’t. Most teams are overpaying for their models and can’t see why. Throttle shows you exactly where your AI spend is going and how to cut it. No guesswork, no code changes. In our first test, a single change delivered 3x more output from the same hardware. Spend less. Run more. That’s Throttle. It’s free and open source. If you’re running AI in production, comment below and I’ll personally help you find your savings.
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2026. All Rights Reserved