Takibi Base
Your knowledge, lit. Drop in docs, get back answers.
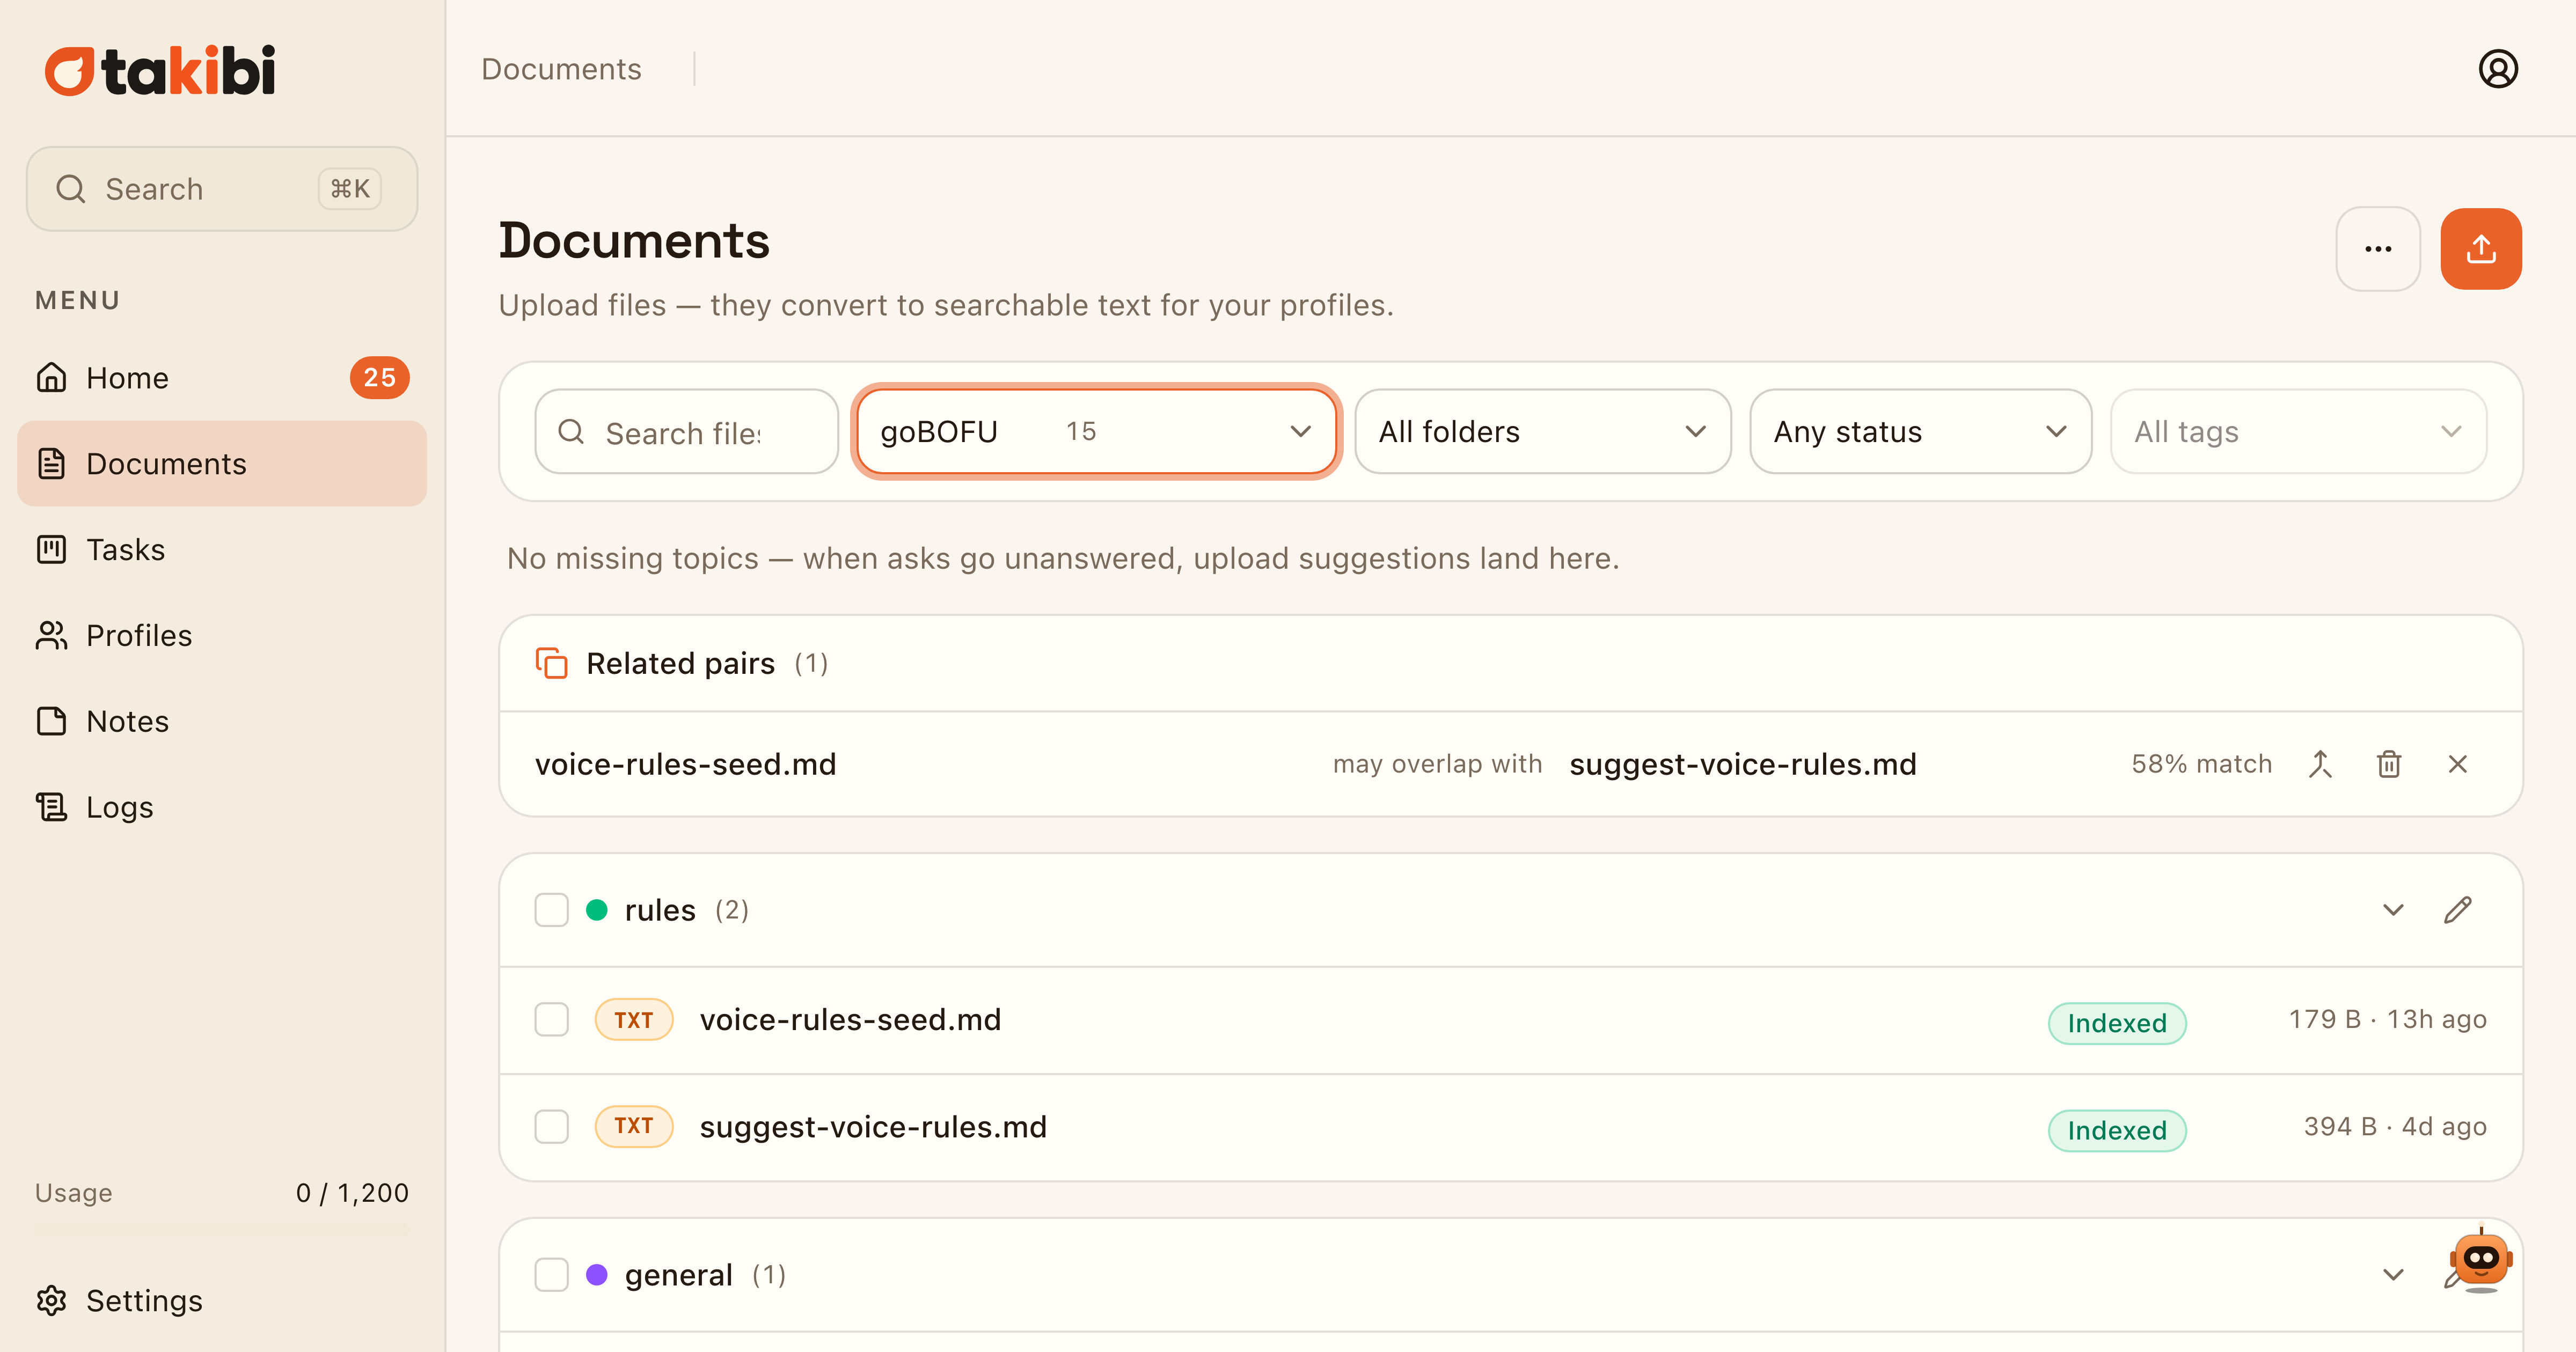
Takibi Base (Takibi) is a shared knowledge base for AI agents. One human operator organizes documents into projects and folders and controls access with Profiles. Agents retrieve exact cited passages and an evidence support score via CLI or API; Takibi does not generate answers. The workspace also includes agent Notes (UNTRUSTED, Profile-scoped scratch with a fixed 30-day TTL; human triage with Keep, Add to draft, or Remove, and draft export; never trusted Sources, not shared across Profiles, never auto-promoted), Conversations for agent-to-agent context, Tasks with review, and Open Knowledge Format export.
Features
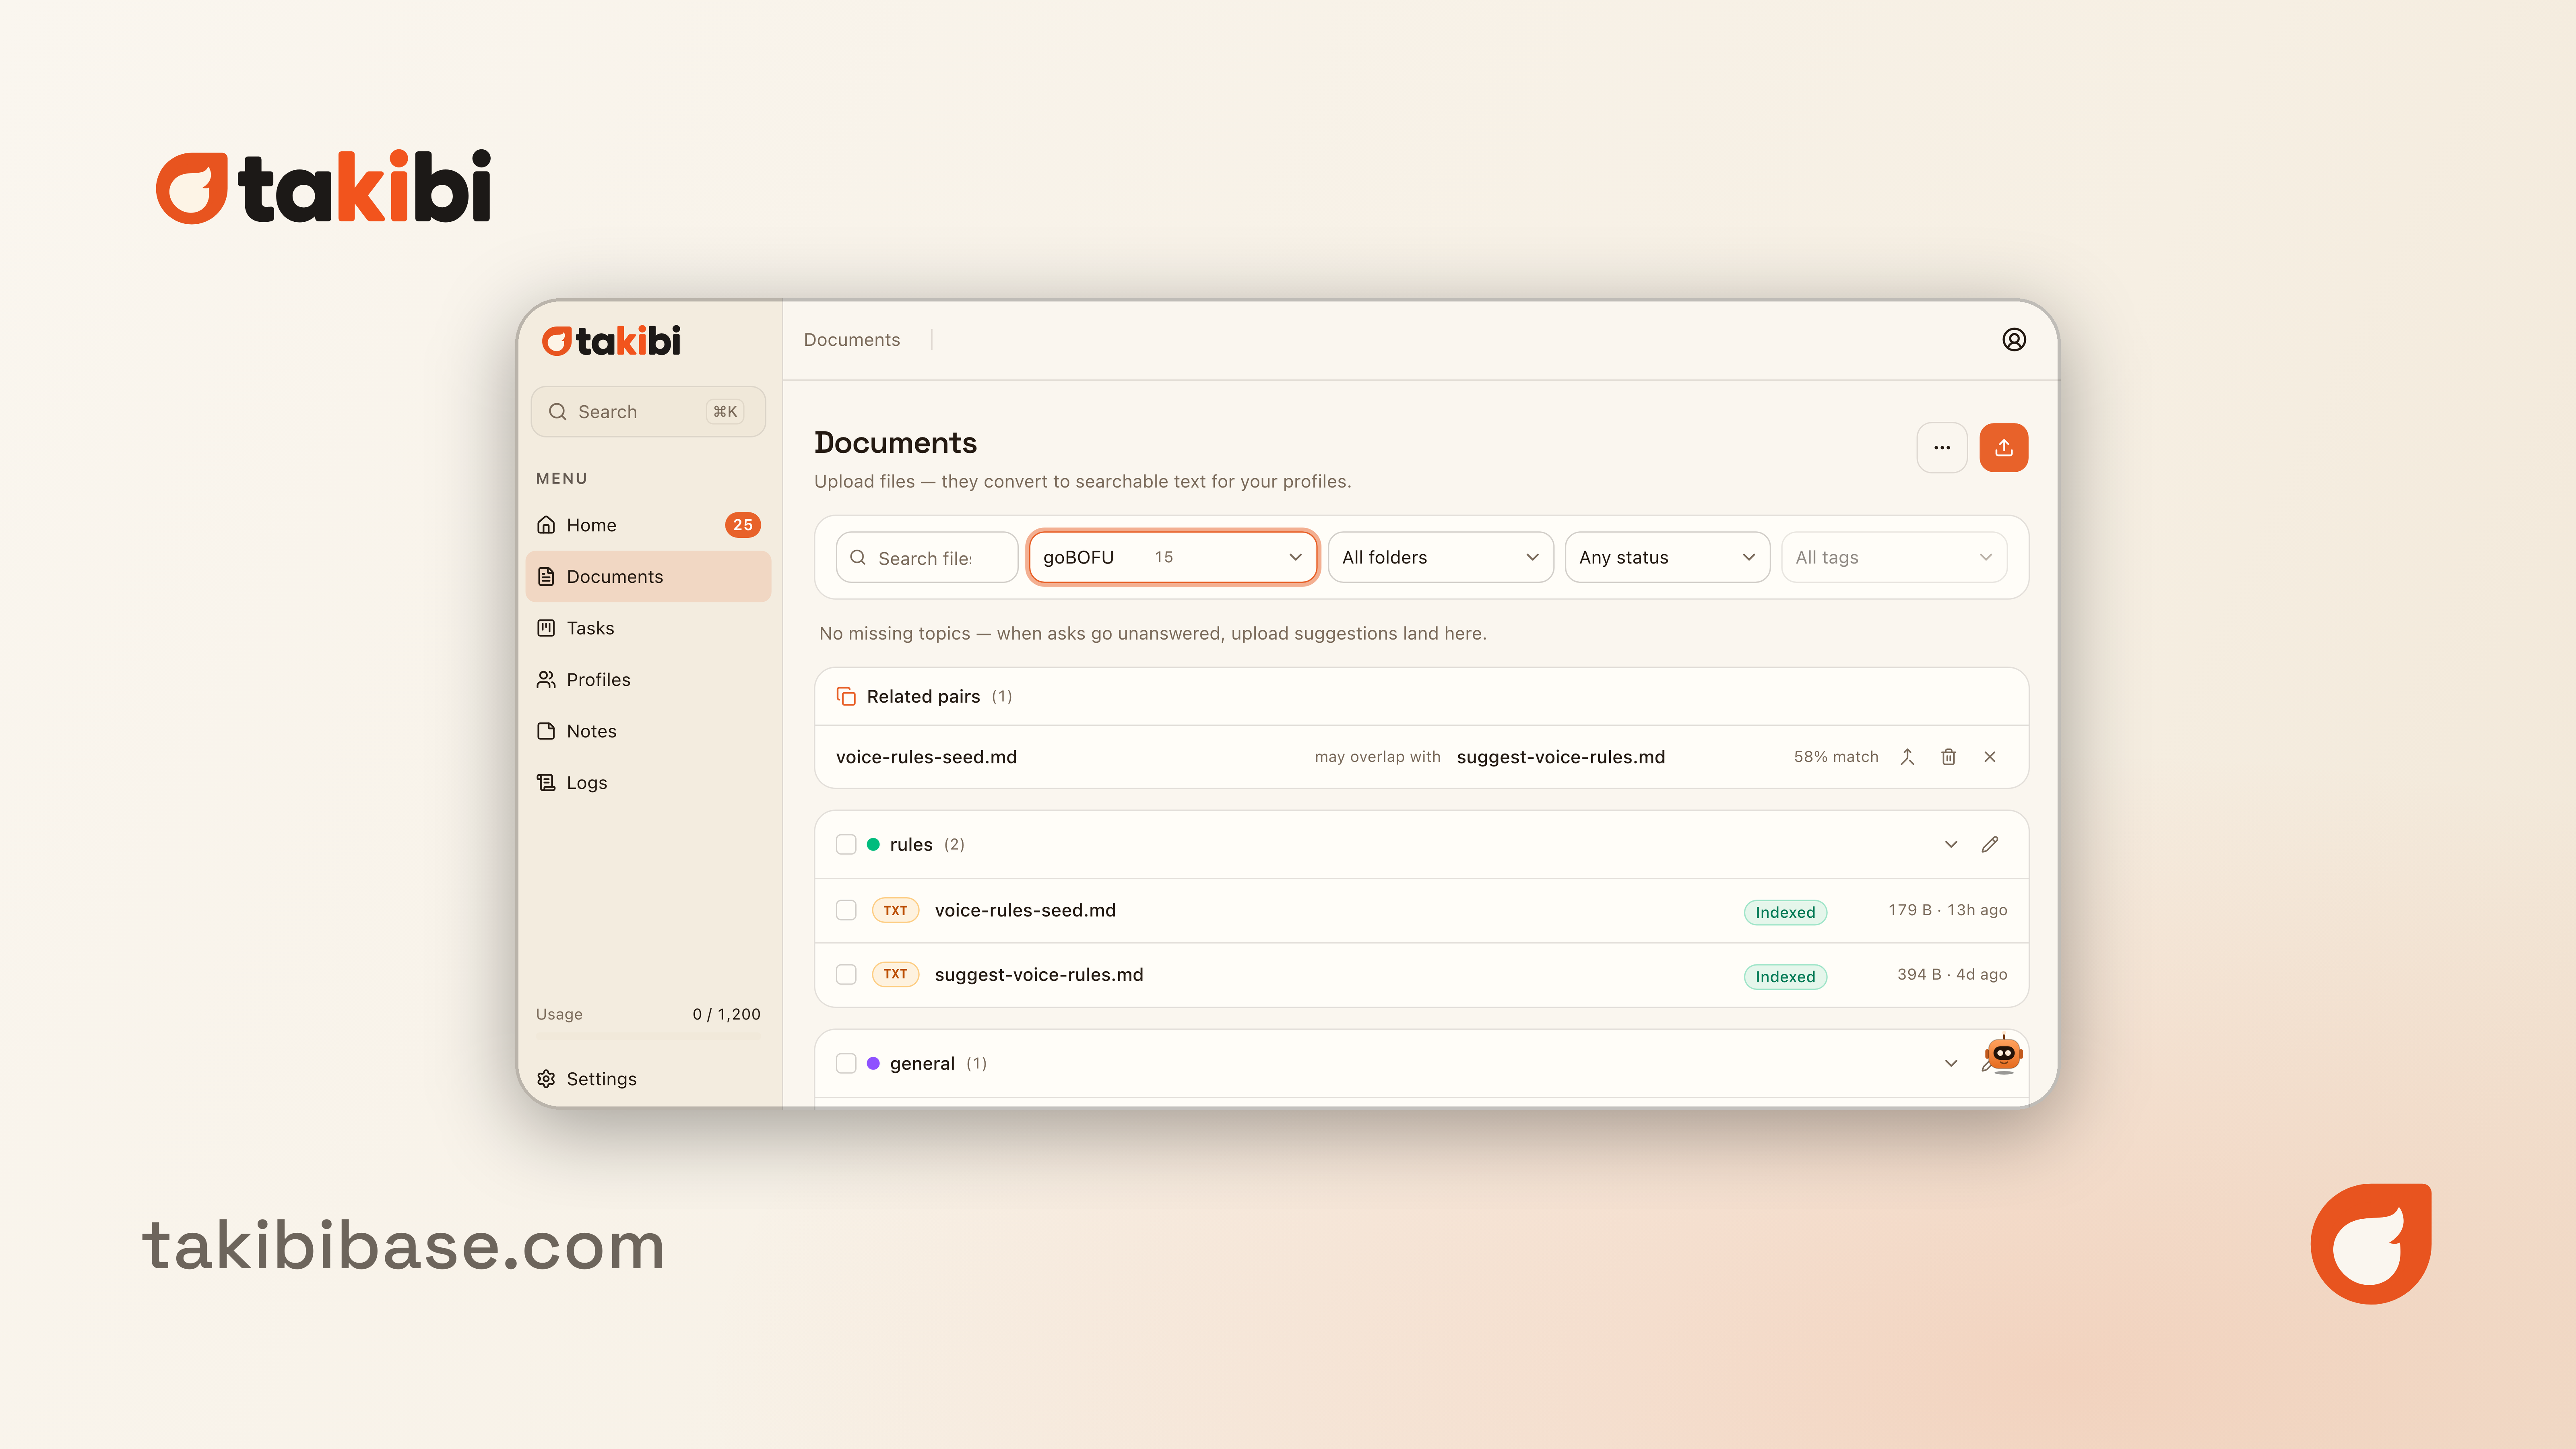
- Shared library: projects and folders; PDF, .docx, Markdown, plain-text upload; indexed / converting / quarantined status; originals downloadable
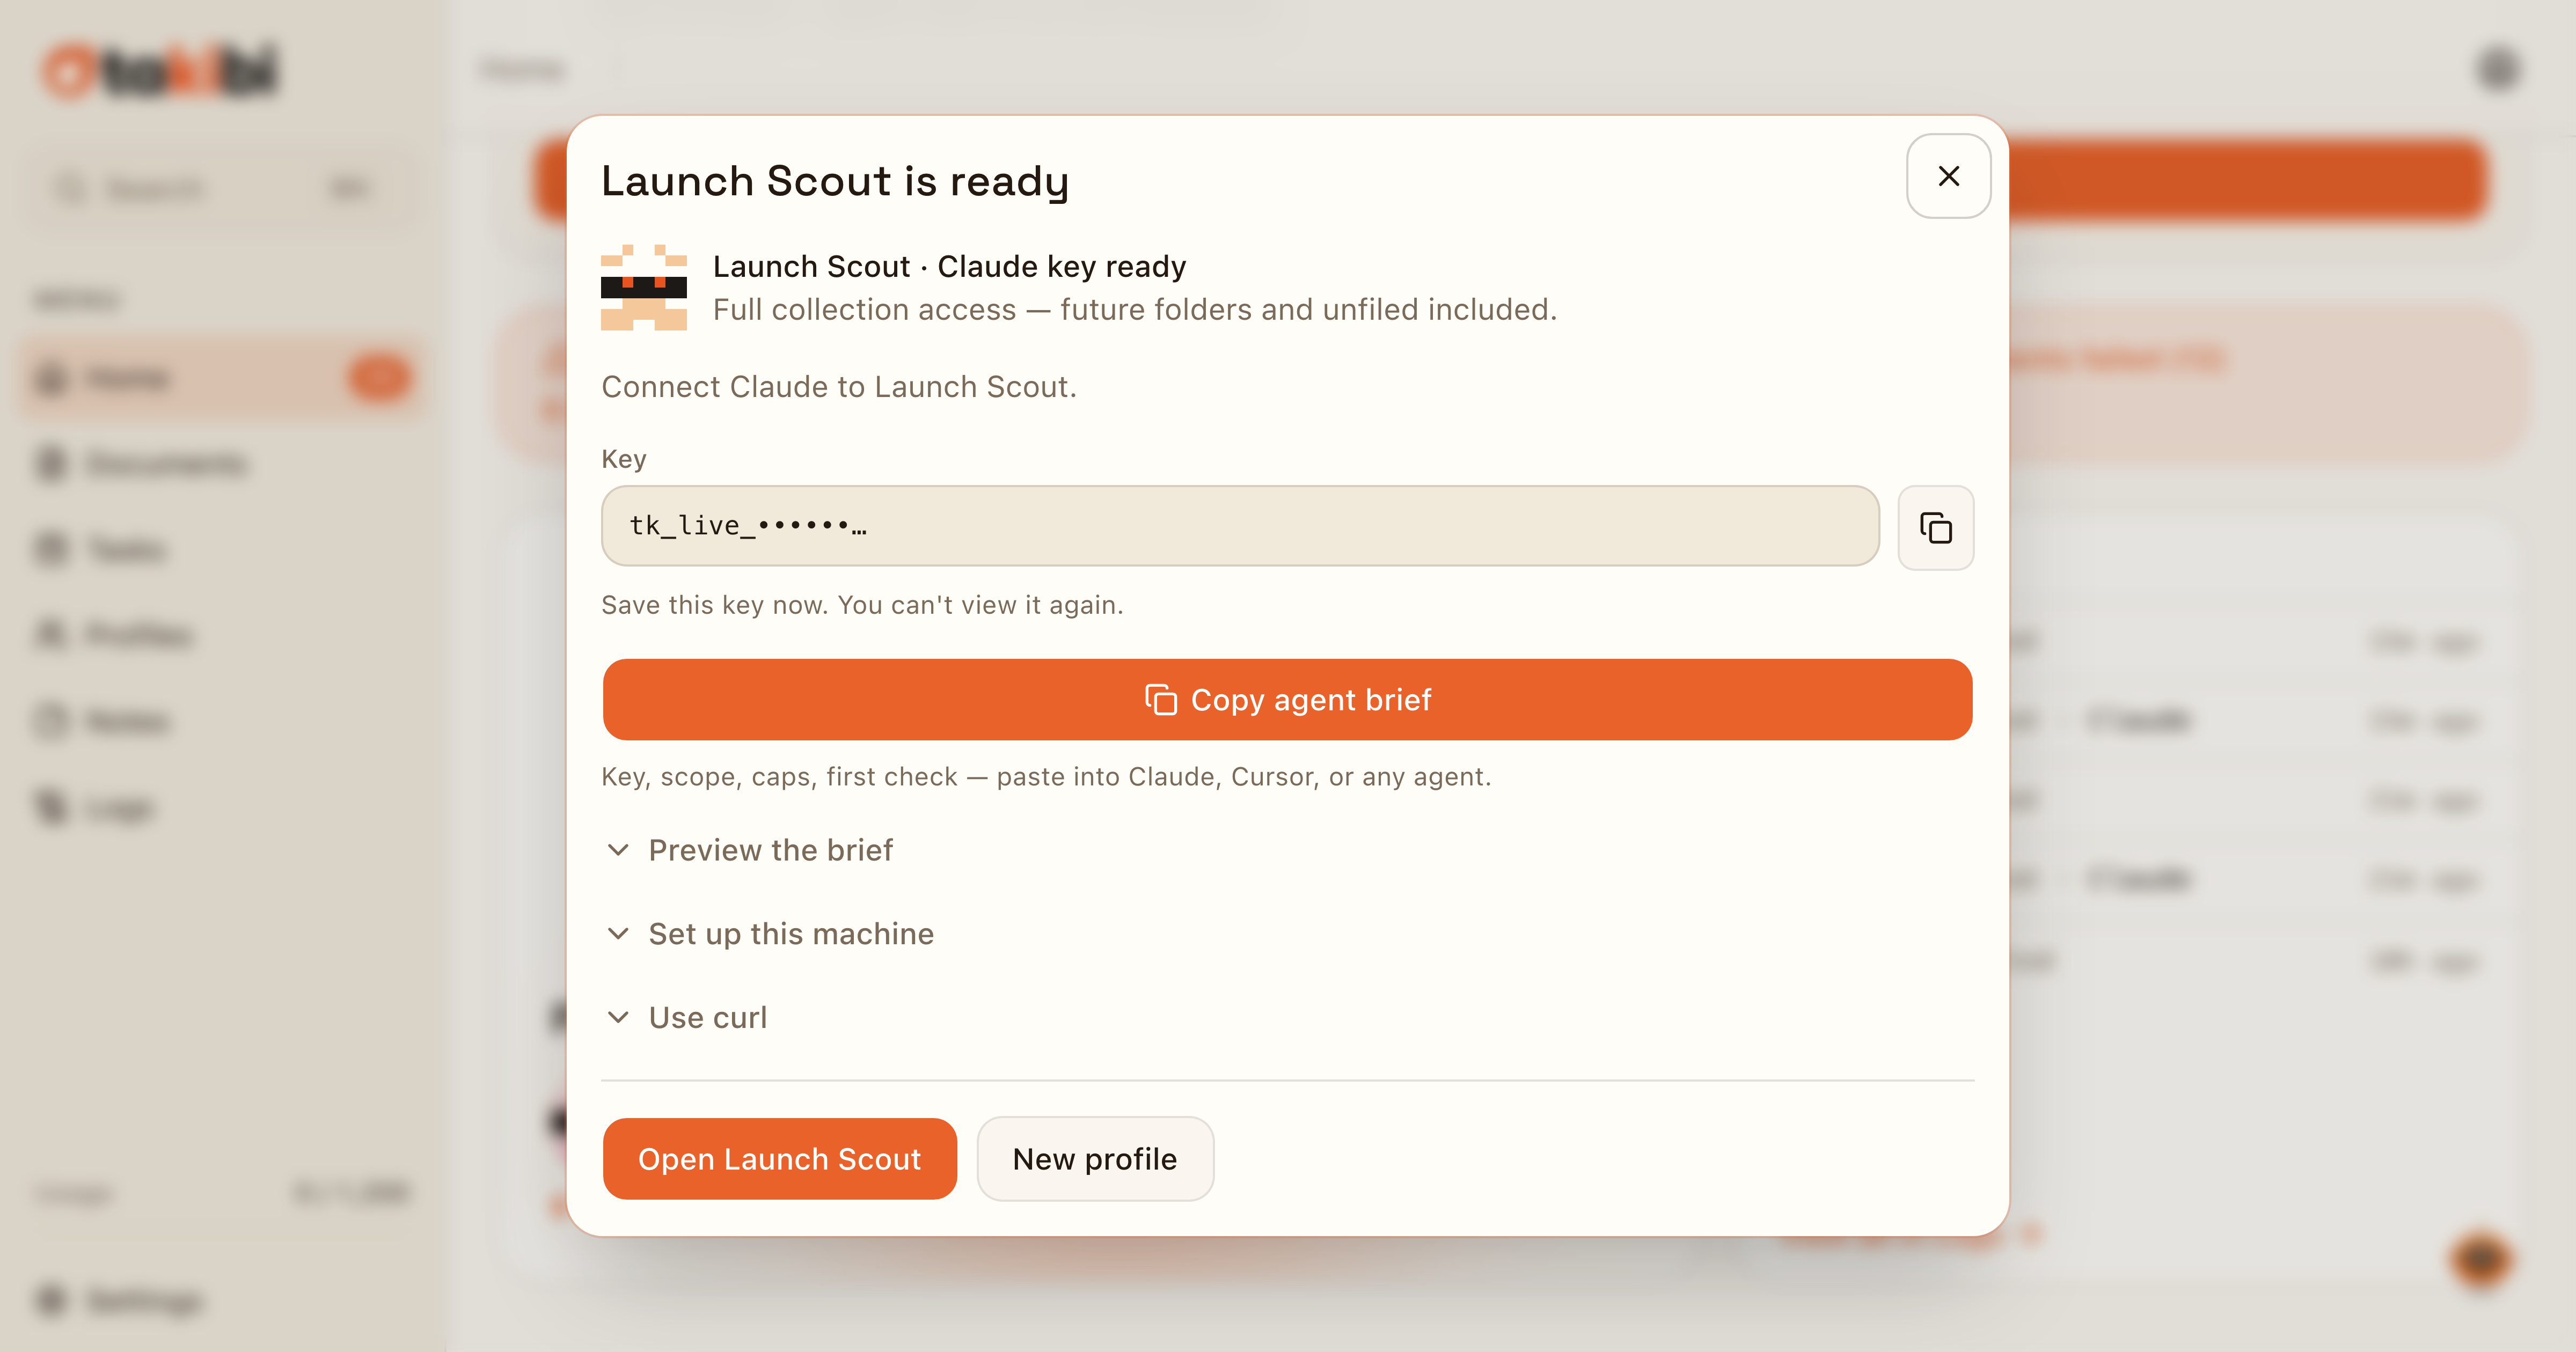
- Profiles: per-tool keys with folder or project grants; rotate or revoke one key; pause a Profile to stop all keys; access and activity review
- Retrieval via CLI: exact passages with citations and an evidence support score; no evidence means no passages; never generates answers
- Agent notes: Profile-scoped scratch, 30-day TTL, human Keep / draft / Remove triage, never auto-promoted to sources
- Conversations: agent-to-agent context exchange
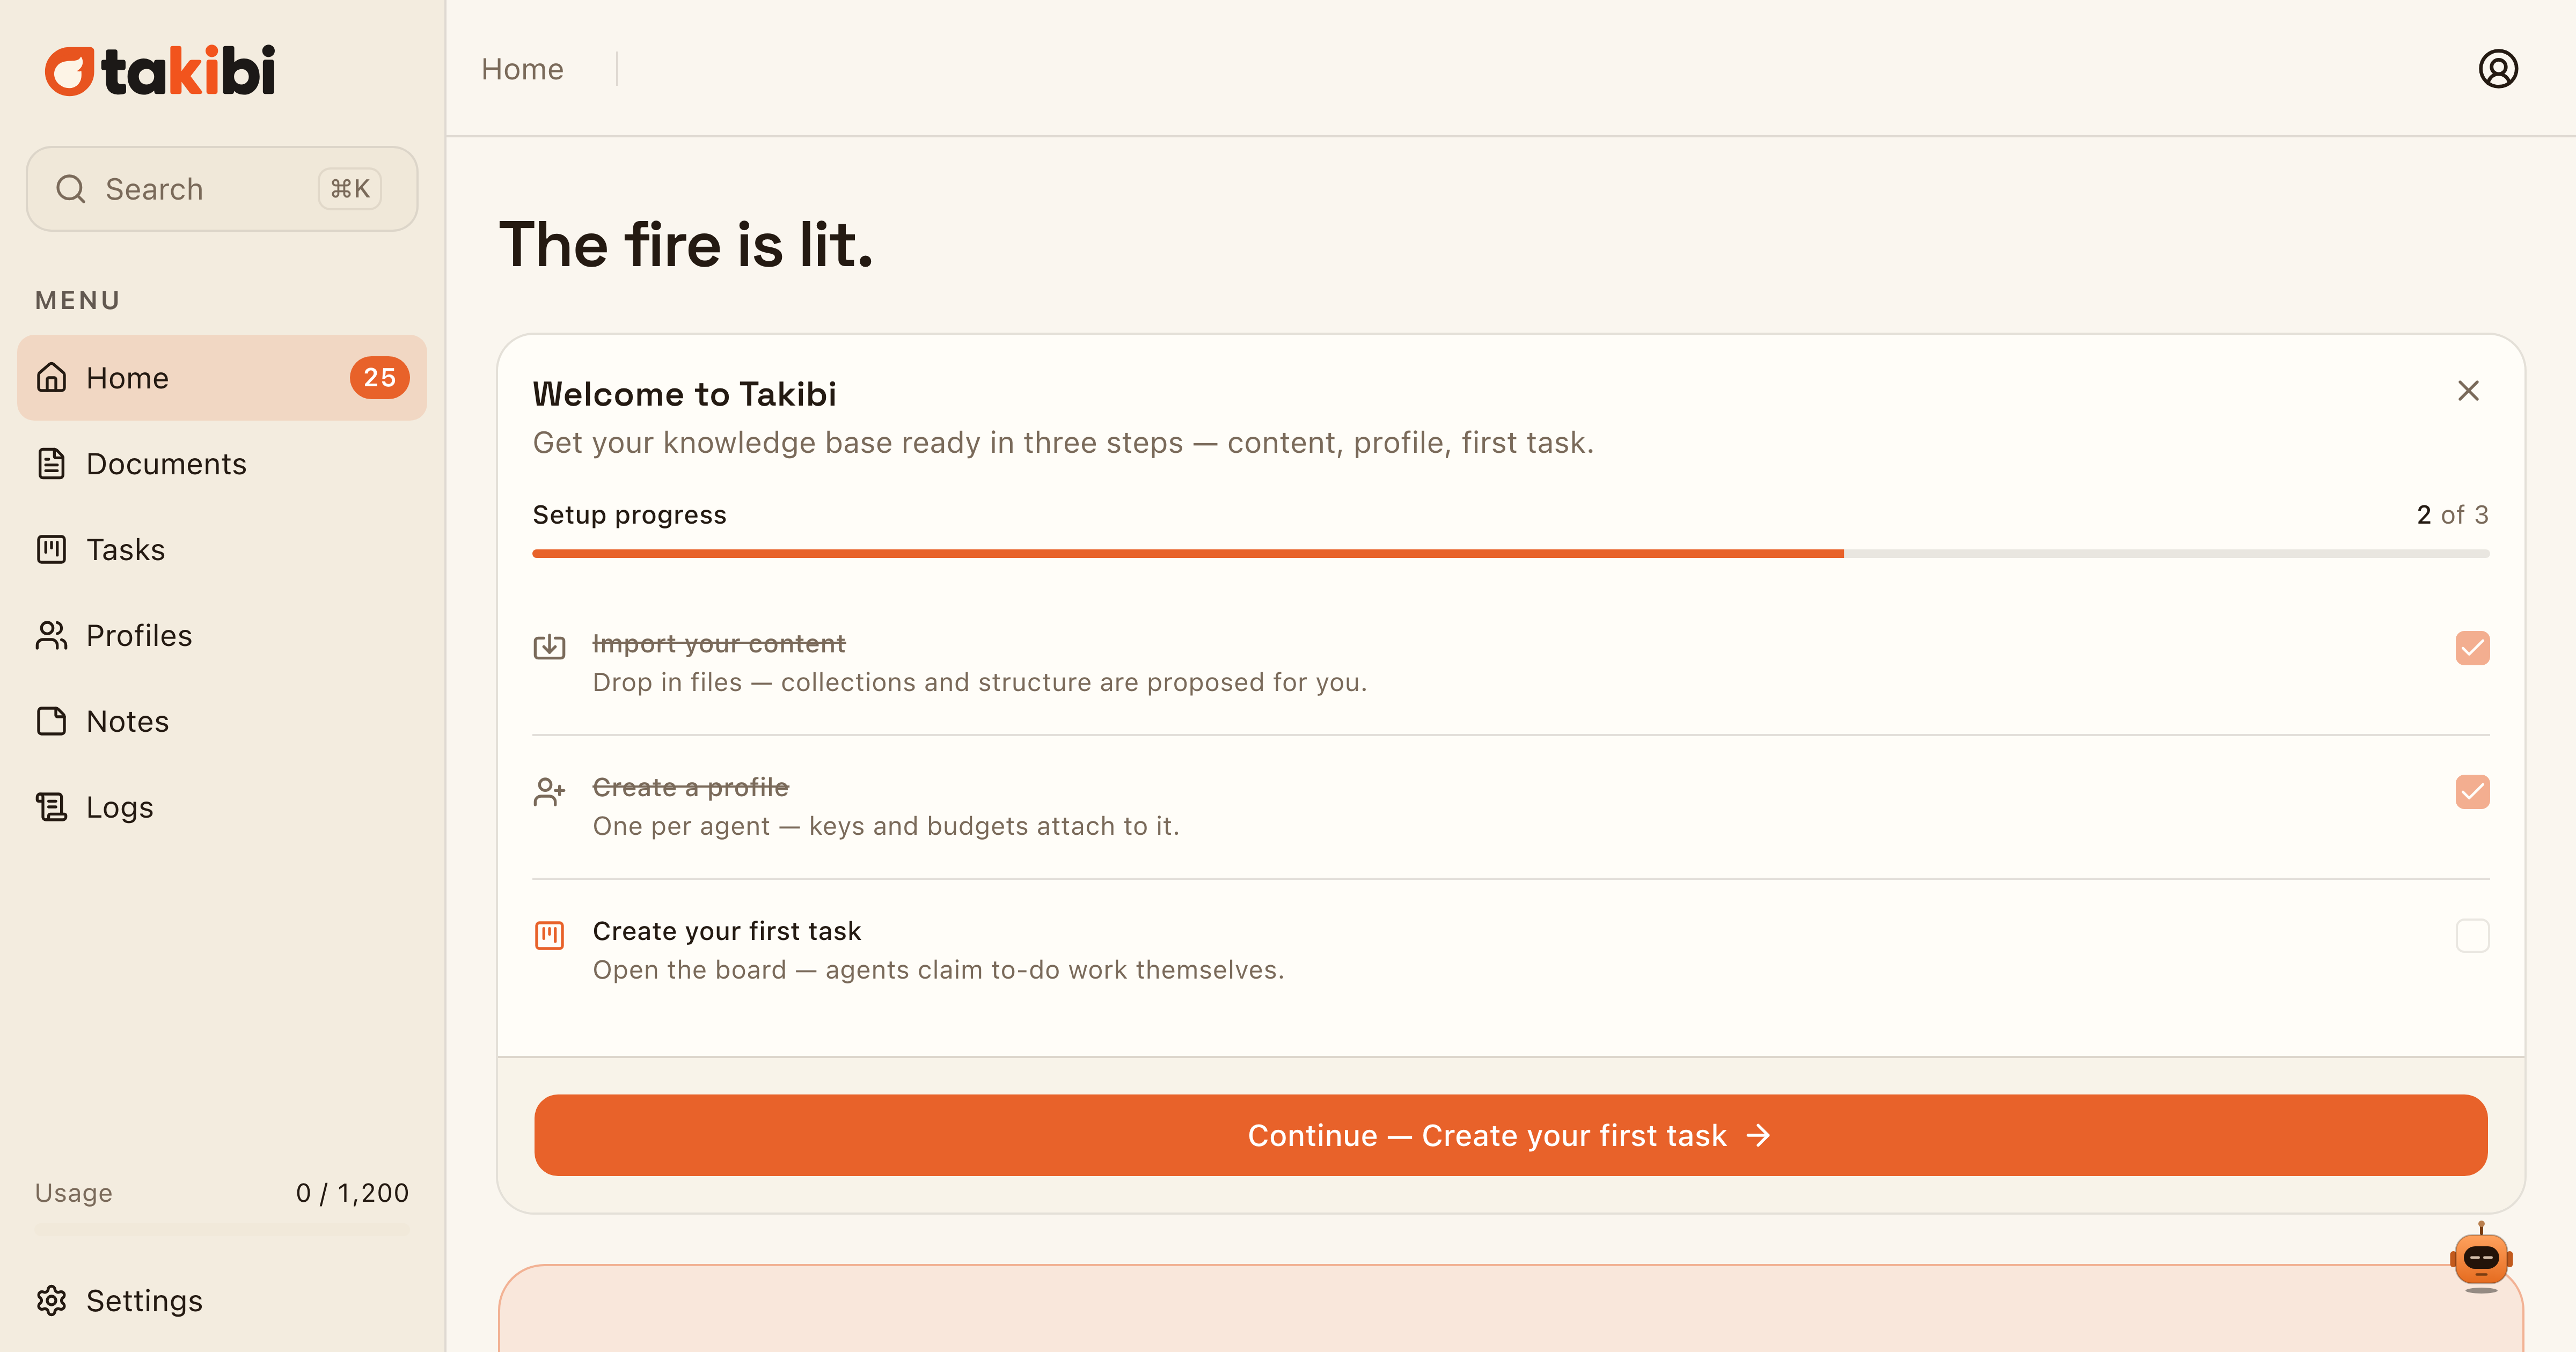
- Tasks with review: assign, claim, submit; owner or Orchestrator accepts as Done
- Export: original files plus OKF project export with documents and structure
Use Cases
- ground agent outputs in cited passages from your own docs
- least-privilege access per agent or tool
- reviewable agent memory without polluting the source library
- multi-agent coordination under human review
- persistent knowledge across chats and sessions
- audit what agents read, keep a portable copy
Fazier Deal
Comments


The retrieval-only design is the standout choice here — returning cited passages with an evidence support score instead of generated answers directly addresses the hallucination problem that plagues most RAG setups. Per-profile keys with folder grants are a smart way to enforce least privilege across tools. I'd love to see how quarantine decisions surface to the human operator during indexing — a clear triage view there would make the trust model complete.


Really interesting approach to AI knowledge management. I especially like the focus on returning exact cited passages instead of generating answers, along with the separation between trusted sources and untrusted agent notes. The profile-based access controls and human review workflow also make this feel practical for teams managing multiple AI agents. Great launc
Really interesting approach to AI knowledge management. I especially like the focus on returning exact cited passages instead of generating answers, along with the separation between trusted sources and untrusted agent notes. The profile-based access controls and human review workflow also make this feel practical for teams managing multiple AI agents. Great launc



Keeping agent Notes separate from trusted Sources, with human review before promotion, is a useful boundary. When a source document changes, how are previously retrieved citations and evidence support scores handled? Can an agent tell that a cited passage has become outdated before reusing it in another task?

The retrieval-only positioning is a genuinely underrated decision - returning cited passages with an evidence score instead of generating answers means the model layer stays swappable and hallucinations never contaminate the source of truth. Curious how the evidence support score is computed: is it purely embedding similarity, or does it weigh profile-scoped access patterns too? Also, the UNTRUSTED agent notes with human triage is exactly the right trust boundary for multi-agent setups.




"no evidence means no passages" is the right default - most retrieval tools fail silently and agents run with invented context. Profile-scoped keys with pause/revoke is exactly the control you want when agents touch internal docs. When a source doc gets updated, do agents see a version bump or does the index refresh in place?


The "no evidence means no passages" rule plus UNTRUSTED scratch notes with a TTL is the right boundary — most RAG products blur retrieval and generation, then act surprised when the agent cites fluent nonsense. One question: how do you handle versioned sources? If a cited doc updates after an agent pulled the passage, does the citation go stale silently, or does re-index flag downstream notes as outdated? That gap is where most "the docs said X" agent failures actually come from — an evidence score that decays with source age, not just topical match, is what would make the score trustworthy.
Premium Products


Fazier Deal
Sponsors
Buy
Awards
View all
Awards
View allMakers
Makers
Comments
The retrieval-only design is the standout choice here — returning cited passages with an evidence support score instead of generated answers directly addresses the hallucination problem that plagues most RAG setups. Per-profile keys with folder grants are a smart way to enforce least privilege across tools. I'd love to see how quarantine decisions surface to the human operator during indexing — a clear triage view there would make the trust model complete.
Really interesting approach to AI knowledge management. I especially like the focus on returning exact cited passages instead of generating answers, along with the separation between trusted sources and untrusted agent notes. The profile-based access controls and human review workflow also make this feel practical for teams managing multiple AI agents. Great launc
Really interesting approach to AI knowledge management. I especially like the focus on returning exact cited passages instead of generating answers, along with the separation between trusted sources and untrusted agent notes. The profile-based access controls and human review workflow also make this feel practical for teams managing multiple AI agents. Great launc
Keeping agent Notes separate from trusted Sources, with human review before promotion, is a useful boundary. When a source document changes, how are previously retrieved citations and evidence support scores handled? Can an agent tell that a cited passage has become outdated before reusing it in another task?
The retrieval-only positioning is a genuinely underrated decision - returning cited passages with an evidence score instead of generating answers means the model layer stays swappable and hallucinations never contaminate the source of truth. Curious how the evidence support score is computed: is it purely embedding similarity, or does it weigh profile-scoped access patterns too? Also, the UNTRUSTED agent notes with human triage is exactly the right trust boundary for multi-agent setups.
"no evidence means no passages" is the right default - most retrieval tools fail silently and agents run with invented context. Profile-scoped keys with pause/revoke is exactly the control you want when agents touch internal docs. When a source doc gets updated, do agents see a version bump or does the index refresh in place?
The "no evidence means no passages" rule plus UNTRUSTED scratch notes with a TTL is the right boundary — most RAG products blur retrieval and generation, then act surprised when the agent cites fluent nonsense. One question: how do you handle versioned sources? If a cited doc updates after an agent pulled the passage, does the citation go stale silently, or does re-index flag downstream notes as outdated? That gap is where most "the docs said X" agent failures actually come from — an evidence score that decays with source age, not just topical match, is what would make the score trustworthy.
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2026. All Rights Reserved