Sourcive
See what AI assistants say about you, and get recommended
People have started asking AI assistants the questions they used to type into Google. Which tool should I use. Who is good at this. What do people recommend. The assistant gives them three or four names, and if you are not one of them, you never hear about it. There is no impression count and no missed-click report. You just do not come up.
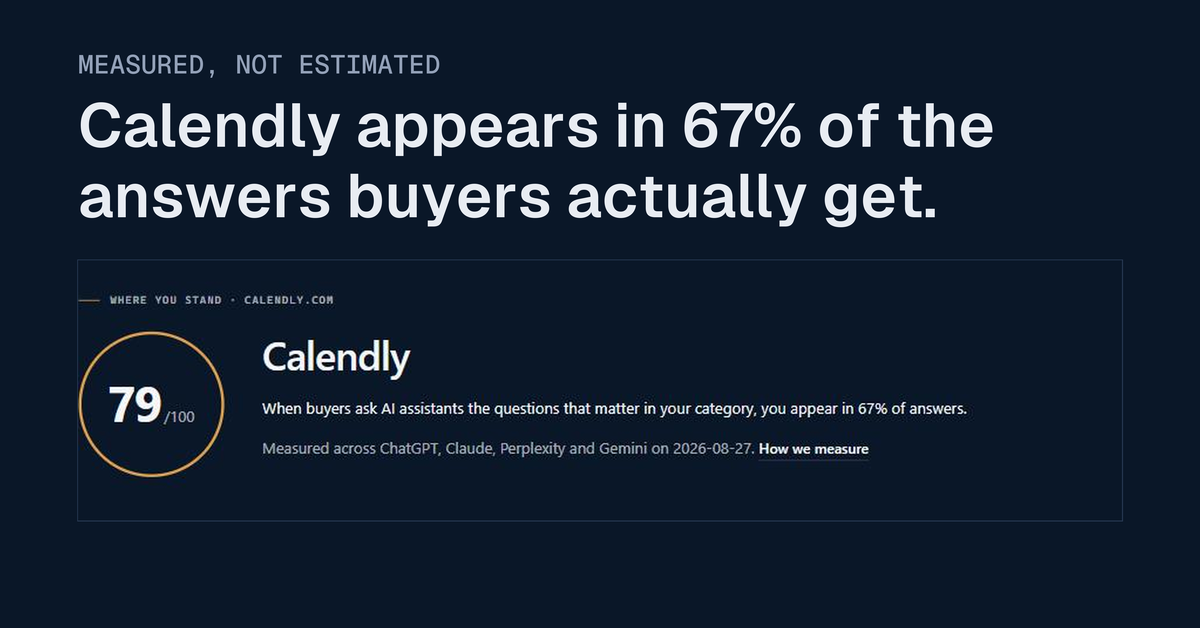
Sourcive tells you whether you come up. We work out what you sell and who you are up against, then put the real buyer questions in your category to ChatGPT, Claude, Perplexity and Gemini through their APIs and read the answers. You see your mention rate, who gets named instead of you, and the answers themselves, word for word. That part is free.
Paying gets you the fixing. You get the buyer questions where you never appear, in priority order, each one saying where to go and answer it. Alongside that, the pages and communities the models actually cited, so you know where to turn up. Then the practical bits: an llms.txt for your site, schema to paste in, your homepage and about copy rewritten so a model can make sense of it, a FAQ, and ten fixes ranked by what will move the needle.
It runs again every month, re-asks the same questions, and checks whether last month's fixes made it onto your site, because the usual reason nothing improves is that nobody did them.
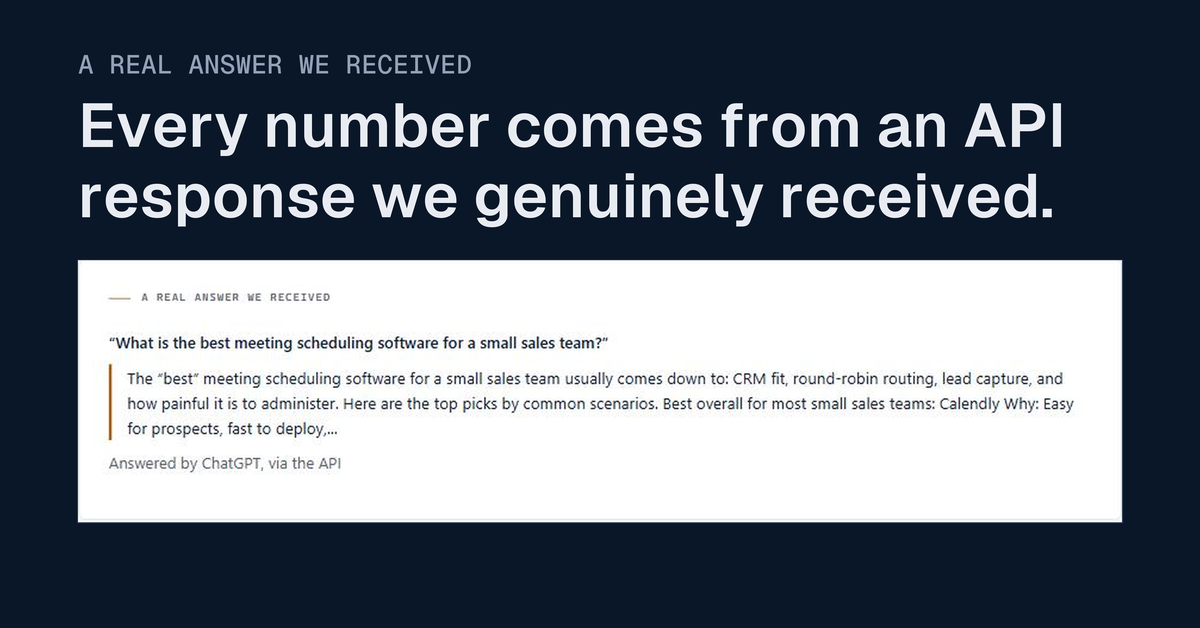
One thing we will not do: guess. Every number came back from a real API call. We never ask one model what another one would probably say, and every report states what we asked and when.
Free to see where you stand. £39 a month to change it.
Features
Real questions put to ChatGPT, Claude, Perplexity and Gemini through their own APIs
Your mention rate, and who gets named instead of you
The answers themselves, word for word, so you can see how you are described
The buyer questions where you never appear, in priority order, each with somewhere to go and answer it
The pages and communities the models actually cited when they answered
An llms.txt, schema to paste in, rewritten homepage and about copy, and a FAQ
Ten fixes ranked by what will move the needle
A monthly re-run that checks whether last month's fixes made it onto your site
Free to check where you stand. £39 a month to change it
Use Cases
You suspect buyers are asking AI which tool to use, and you have no idea what it says
Your Google rankings are fine but enquiries are drying up
You want to know which competitor gets named when you do not
You need to know where to publish so the models actually see you
You are already paying for an AI visibility tracker and want the fixes, not more charts
You need to show someone whether any of this work moved the number
Comments


The monthly re-check is the part most tools in this space skip. Everyone audits once; almost nobody verifies the fixes actually shipped. Curious how you weight the buyer questions when a product straddles two categories - do you pick the category with more query volume, or the one where the mention rate is worse? Also smart that you show the cited pages and communities. That list alone is a distribution map most founders pay consultants for.

Really nice to see this, it's close to what I'm building (but my target audience is South Africa), and you're doing it well. I especially like that the free tier shows a real quoted AI answer, not just a number. One thing I keep wrestling with: AI answers change run to run, so how many runs go into your "mention rate"? Curious how you keep that honest.


The API-based approach (asking the models directly rather than crawling) is a genuinely different measurement than crawler-based checkers, and it sidesteps a real gap those have: about 1 in 10 sites in a census I ran of the top 5,000 block AI search crawlers (OAI-SearchBot, PerplexityBot, etc.) via robots.txt while still allowing Googlebot, so a crawler-based tool would misread them as simply low-quality rather than structurally blocked. Querying the models directly avoids that failure mode entirely - though it also means a mention-rate result can't tell a client *why* they're missing when the actual cause is a robots.txt rule, not a content gap. Might be worth a robots.txt spot-check alongside the API queries for that subset of cases.
We built Sourcive after watching enquiries dry up while our search rankings stayed exactly where they were. People had started asking an assistant instead, and there is no analytics for that. You are either named in the answer or you are not, and nobody tells you which. Most tools in this space now measure it. The part we could not find anywhere was the fixing. So the paid report is a list of the specific buyer questions where you never come up, in priority order, each one saying where to go and answer it, plus the pages and communities the models actually cited when they answered. Then it re-runs monthly and checks whether the fixes made it onto your site, because the usual reason nothing improves is that nobody did them. The check is free and does not need a card. If you run it, the thing I would most like to hear is whether the questions we generated for your category are the ones your buyers actually ask. That is the part where being wrong makes everything downstream worthless, and it is the hardest to test from the outside.
Premium Products




Sponsors
Buy
Awards
View all
Awards
View allMakers
Makers
Comments
The monthly re-check is the part most tools in this space skip. Everyone audits once; almost nobody verifies the fixes actually shipped. Curious how you weight the buyer questions when a product straddles two categories - do you pick the category with more query volume, or the one where the mention rate is worse? Also smart that you show the cited pages and communities. That list alone is a distribution map most founders pay consultants for.
Really nice to see this, it's close to what I'm building (but my target audience is South Africa), and you're doing it well. I especially like that the free tier shows a real quoted AI answer, not just a number. One thing I keep wrestling with: AI answers change run to run, so how many runs go into your "mention rate"? Curious how you keep that honest.
The API-based approach (asking the models directly rather than crawling) is a genuinely different measurement than crawler-based checkers, and it sidesteps a real gap those have: about 1 in 10 sites in a census I ran of the top 5,000 block AI search crawlers (OAI-SearchBot, PerplexityBot, etc.) via robots.txt while still allowing Googlebot, so a crawler-based tool would misread them as simply low-quality rather than structurally blocked. Querying the models directly avoids that failure mode entirely - though it also means a mention-rate result can't tell a client *why* they're missing when the actual cause is a robots.txt rule, not a content gap. Might be worth a robots.txt spot-check alongside the API queries for that subset of cases.
We built Sourcive after watching enquiries dry up while our search rankings stayed exactly where they were. People had started asking an assistant instead, and there is no analytics for that. You are either named in the answer or you are not, and nobody tells you which. Most tools in this space now measure it. The part we could not find anywhere was the fixing. So the paid report is a list of the specific buyer questions where you never come up, in priority order, each one saying where to go and answer it, plus the pages and communities the models actually cited when they answered. Then it re-runs monthly and checks whether the fixes made it onto your site, because the usual reason nothing improves is that nobody did them. The check is free and does not need a card. If you run it, the thing I would most like to hear is whether the questions we generated for your category are the ones your buyers actually ask. That is the part where being wrong makes everything downstream worthless, and it is the hardest to test from the outside.
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2025. All Rights Reserved