Sentl.AI
What AI says about your brand
Sentl.AI is an AI visibility monitoring tool for brands and agencies. On a schedule, it asks models from OpenAI, Anthropic, Google and Perplexity the questions your buyers ask, and records what they answer and which domains and pages they use as sources. You write the rules: the correct facts for each question. A separate model grades every answer against them and explains the score, so you see where AI gets your brand wrong and which sources to work on. The GEO work on those sources is done by your team or your agency, and each run measures what it changed. Free welcome credits, plans from €99/month.
Features
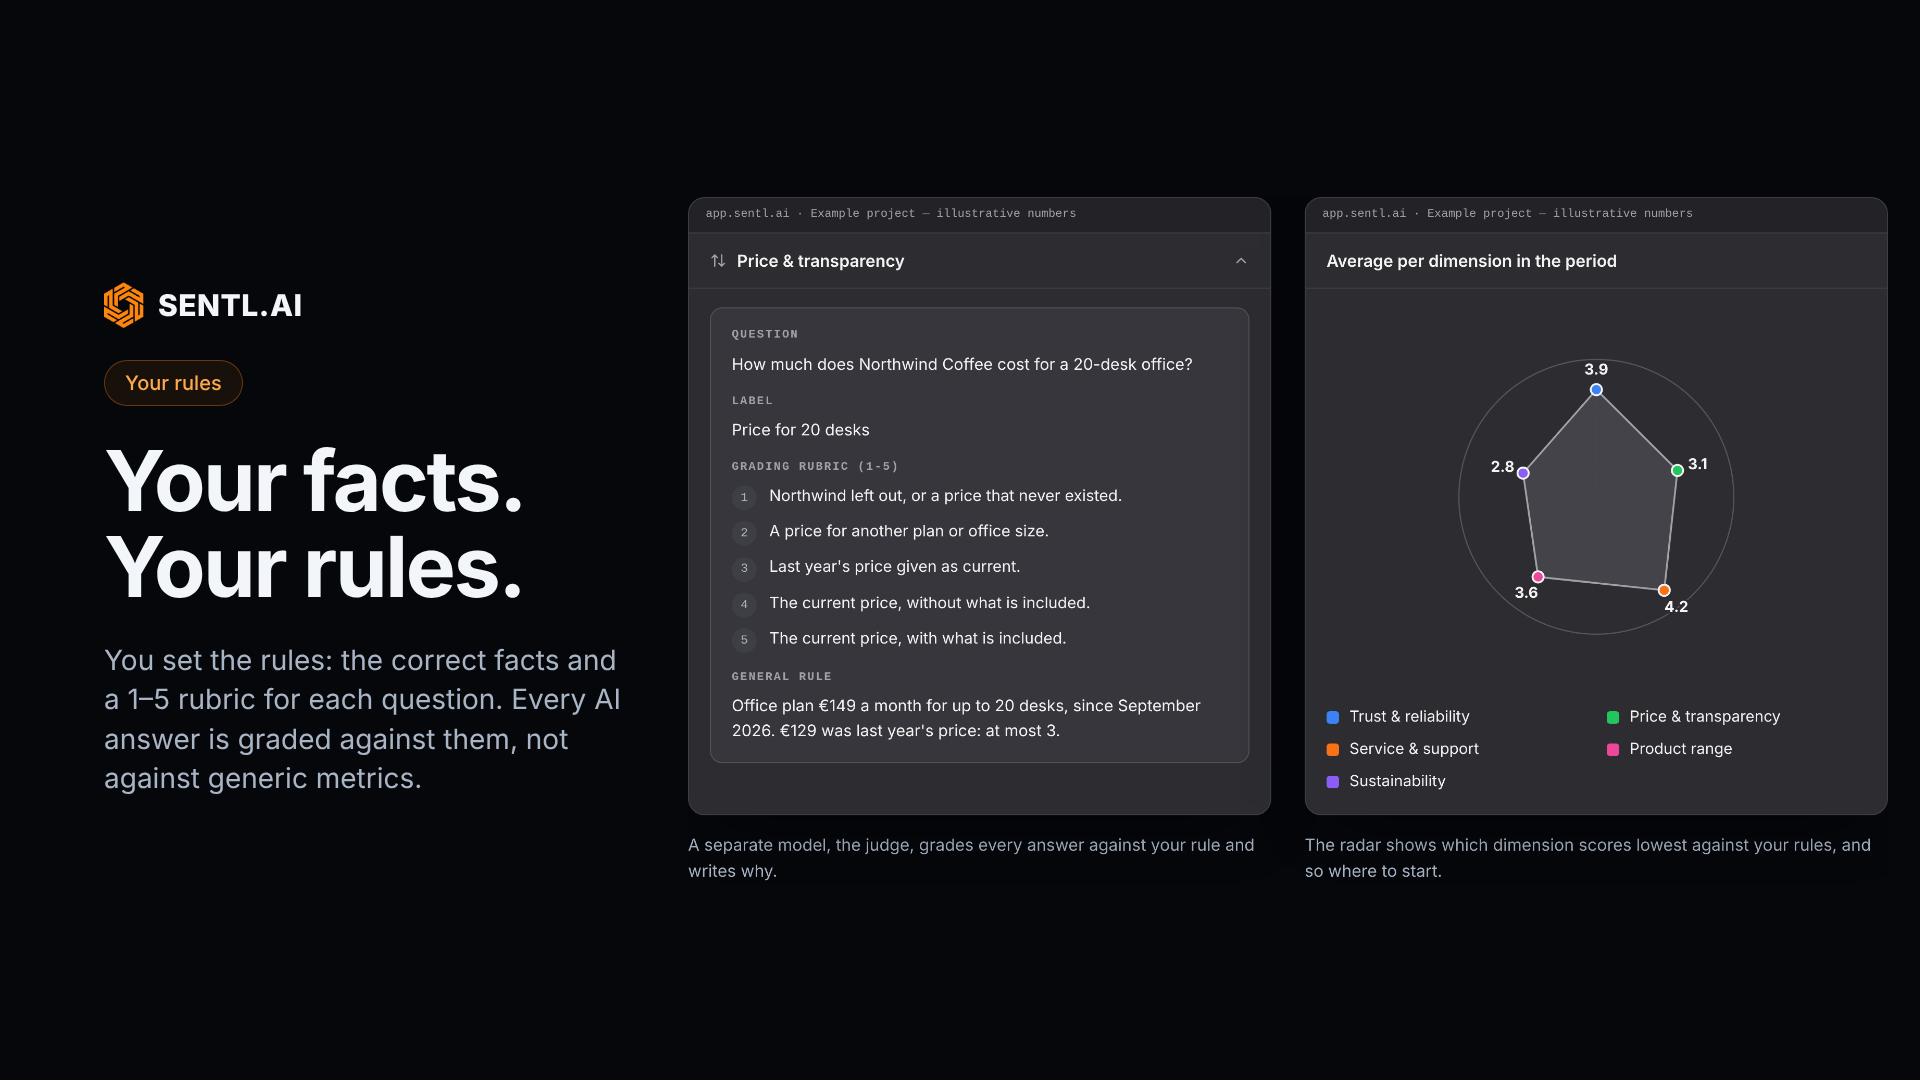
- Questions and rules you write: the correct facts and a 1–5 rubric for each question;
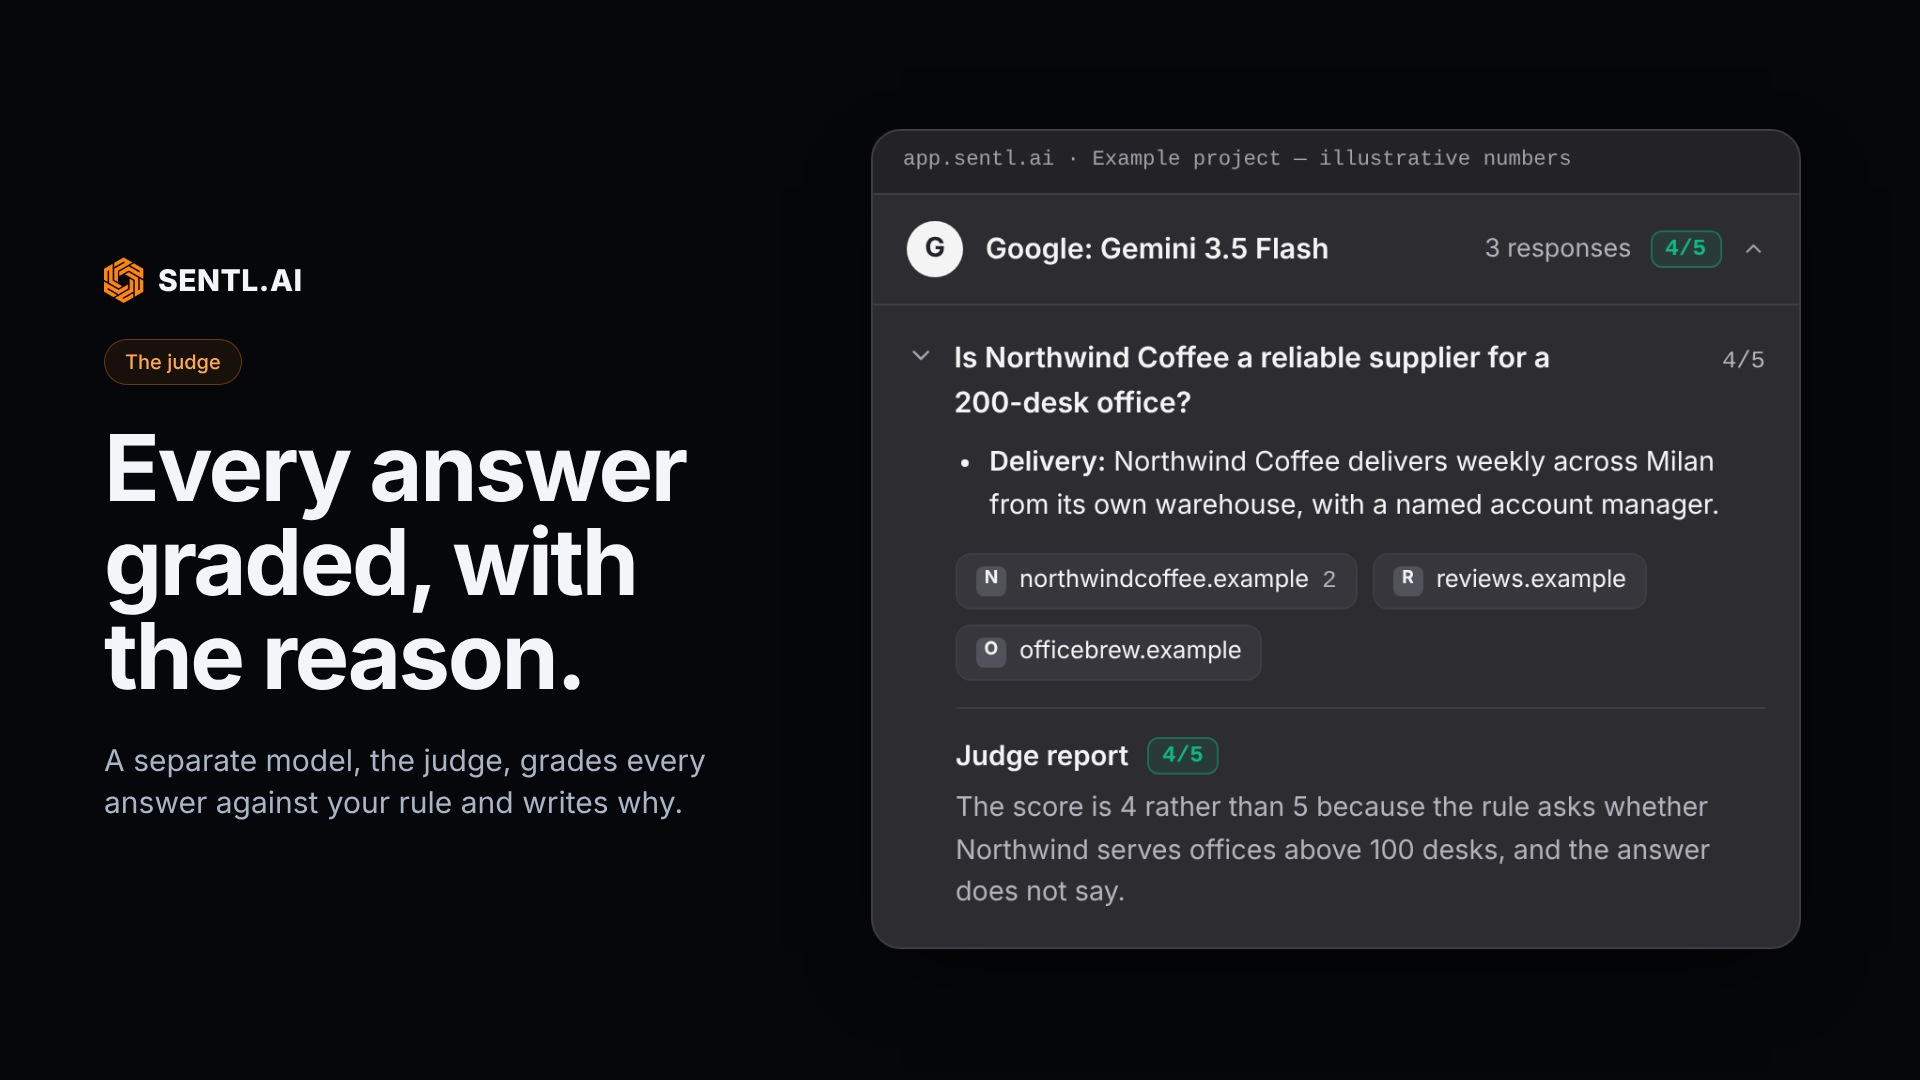
- A separate judge model, never the one that answered, grades every answer and writes why;
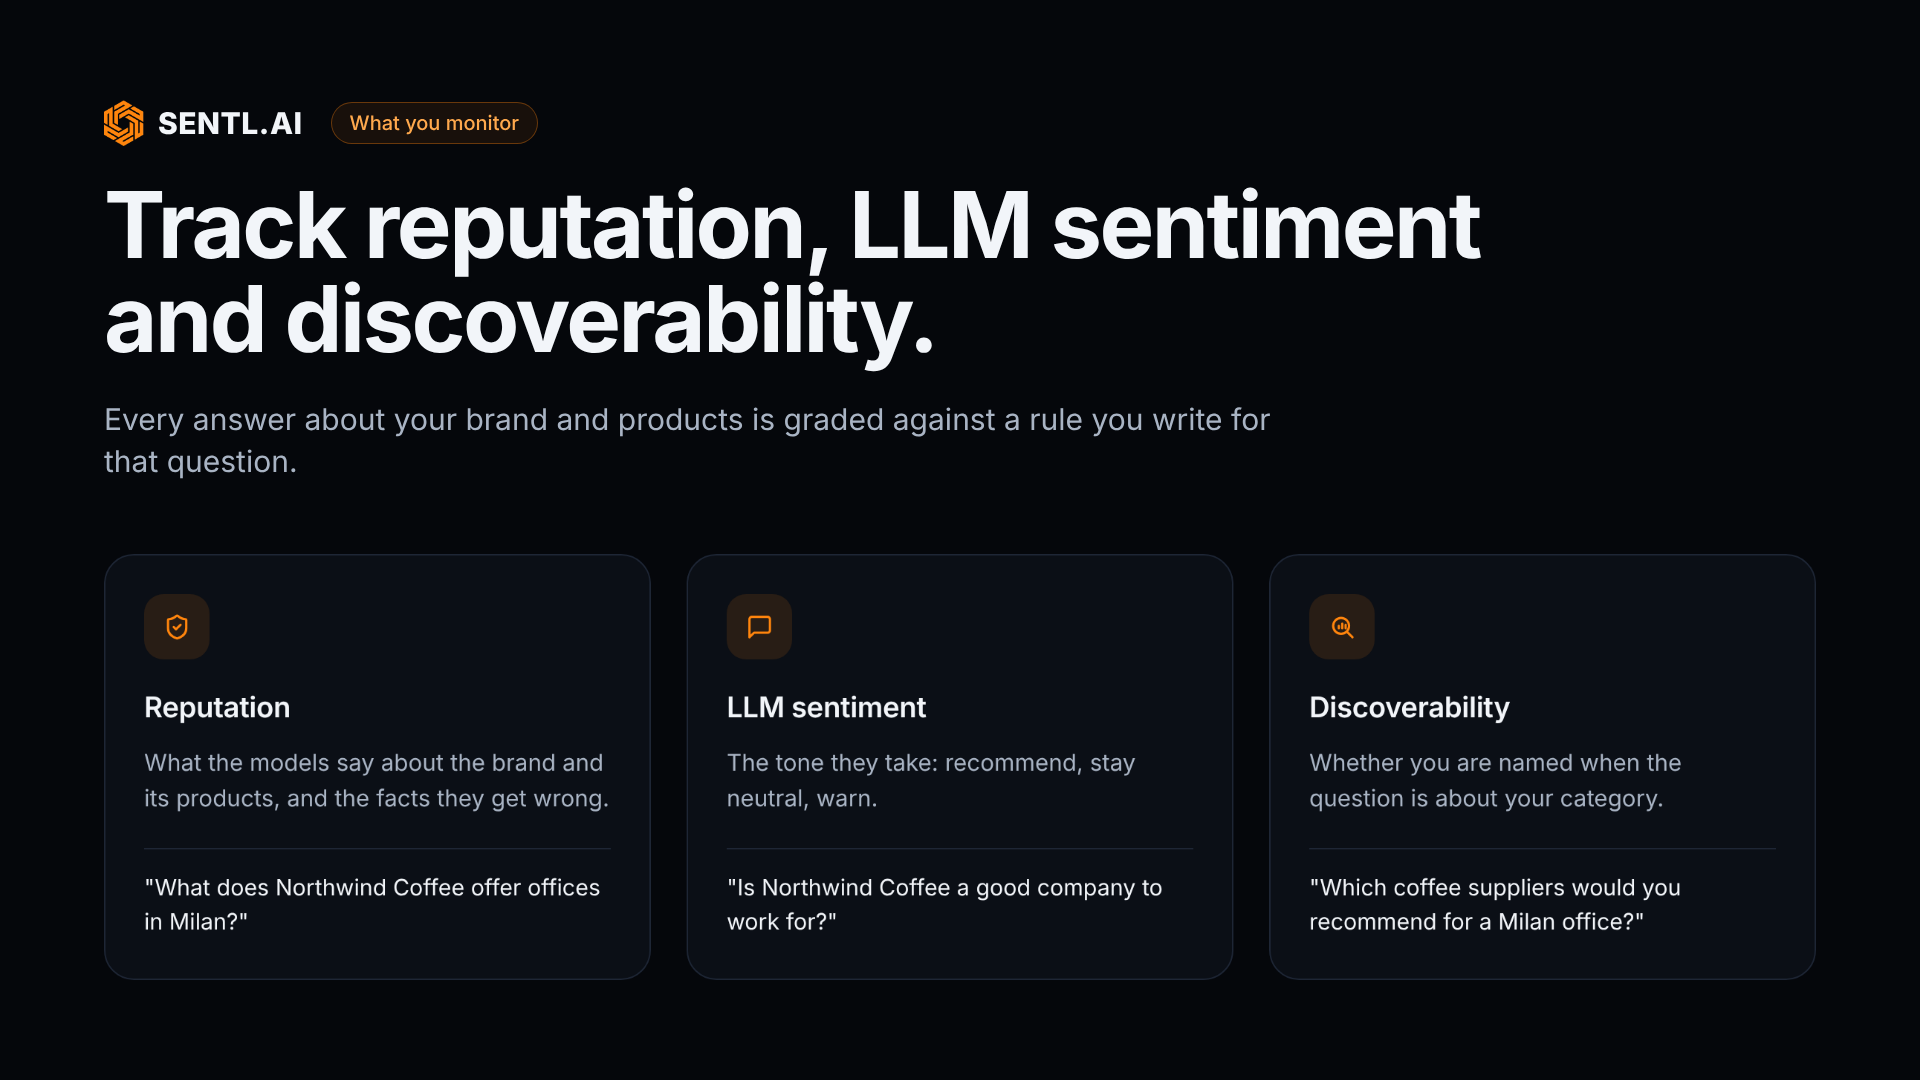
- Three areas: reputation, LLM sentiment, discoverability;
- Custom dimensions with a radar view (e.g. price, service, trust);
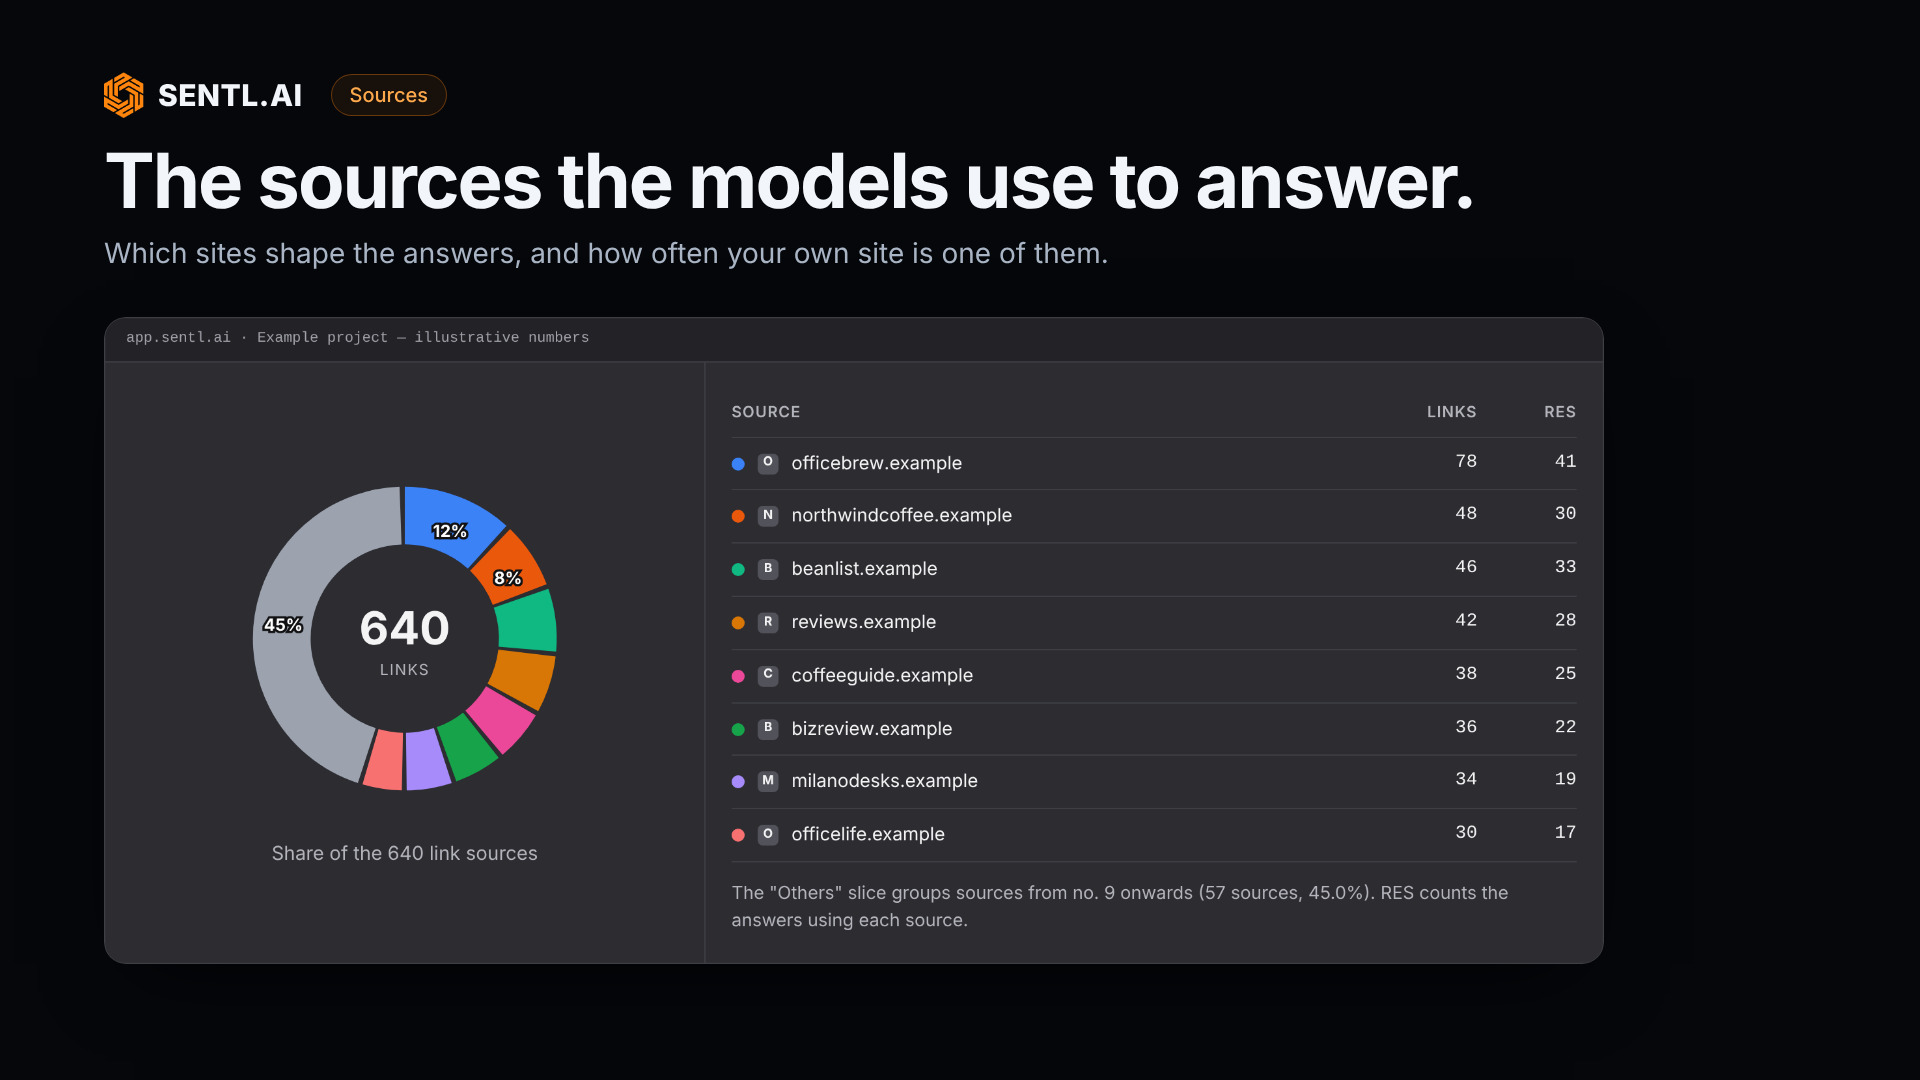
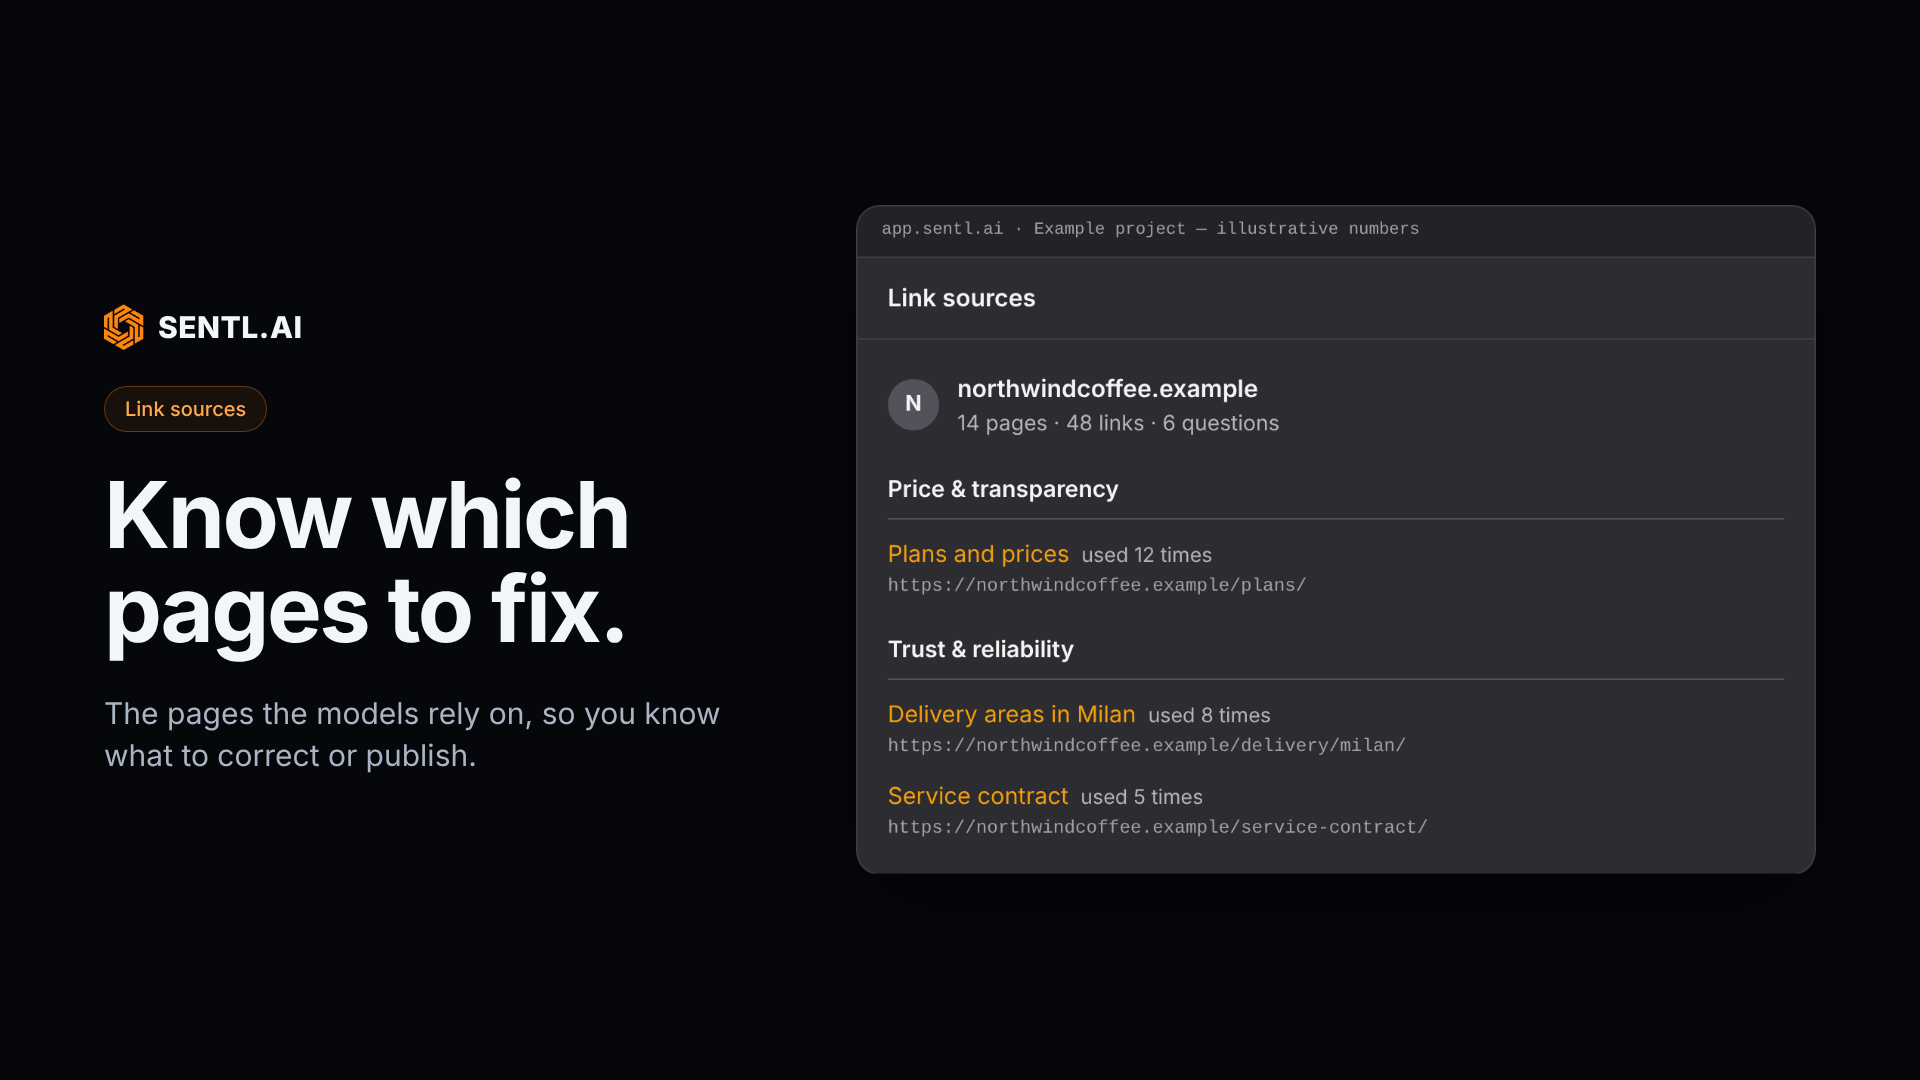
- Sources by domain and by page, with how many answers use each one;
- Daily, weekly or monthly runs, with rounds to measure natural variation;
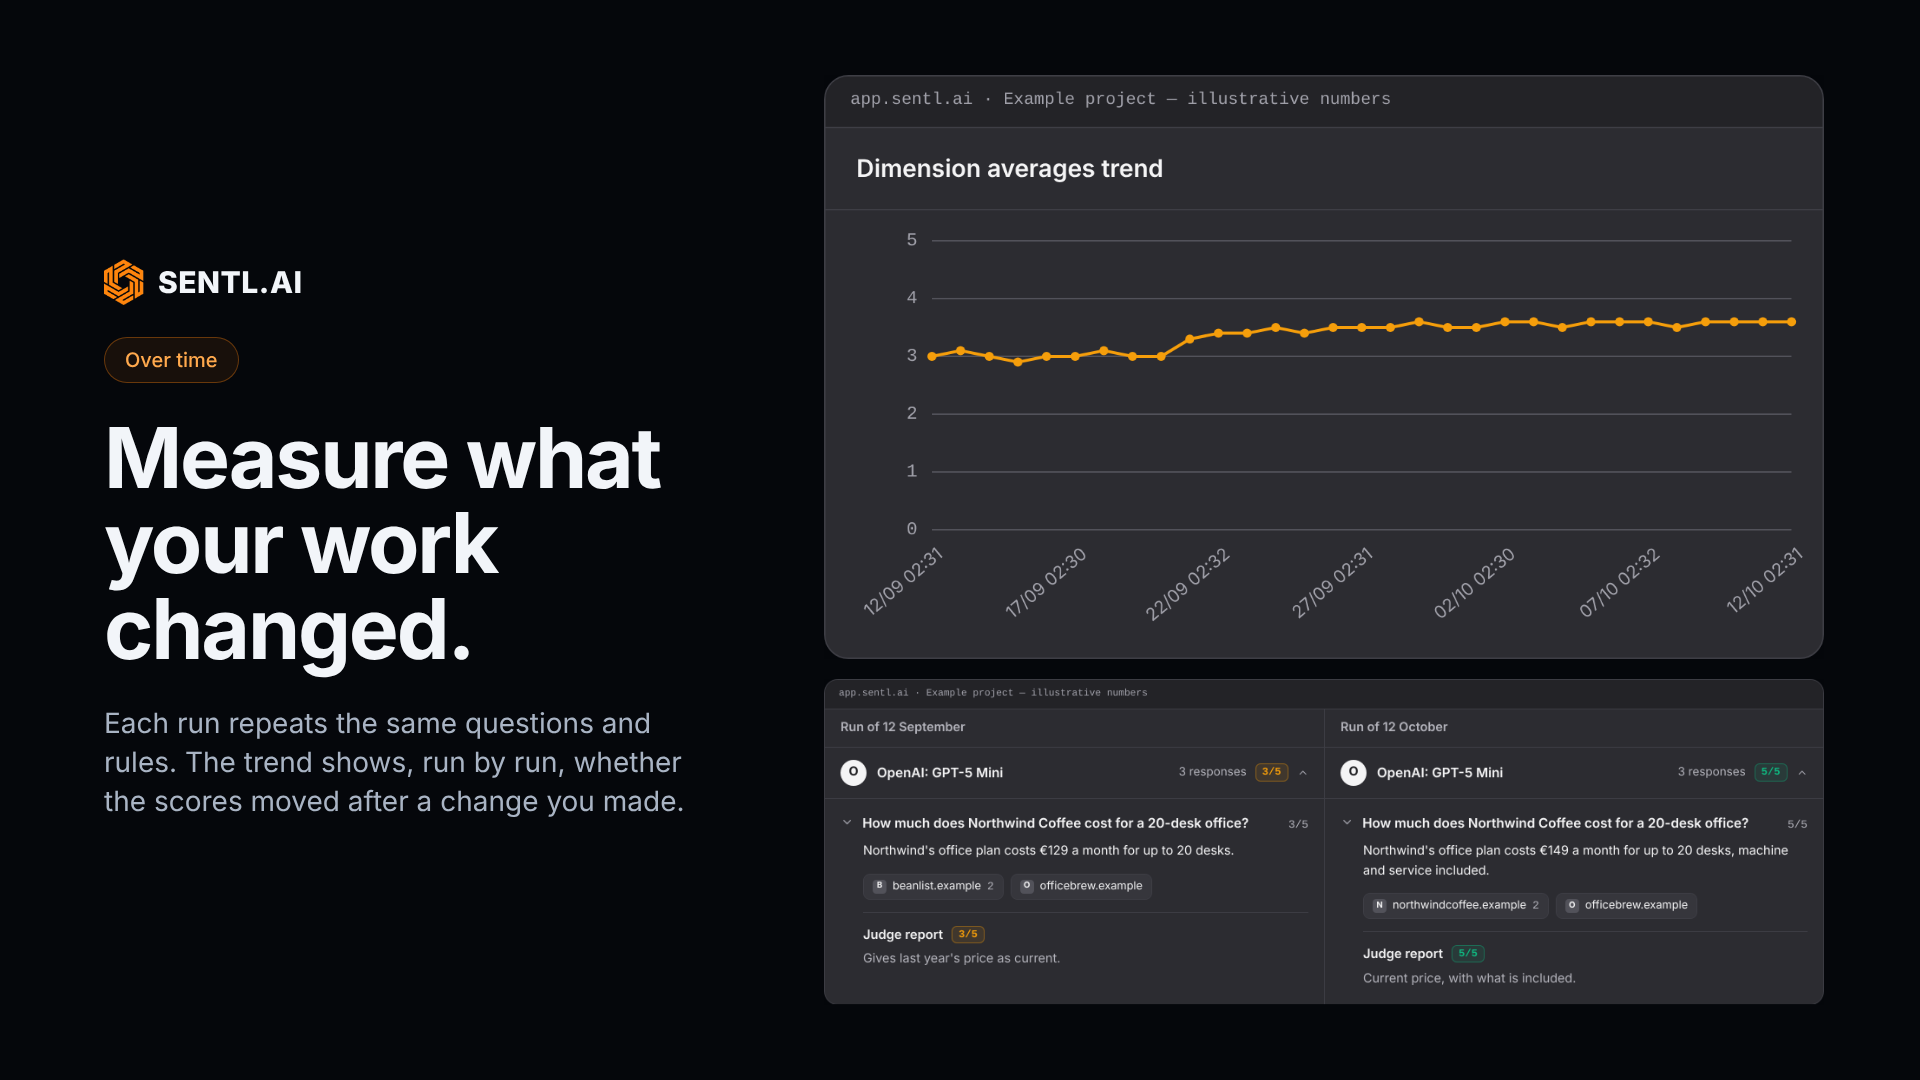
- A trend per dimension, run after run, to see what each change moved;
- Set up projects, start runs and ask for the monthly report from Claude or ChatGPT, via MCP;
- European servers.
Use Cases
- B2B marketing teams: check what AI models tell buyers about your products, prices and category.
- Communications and reputation: find the wrong facts and warnings that customers, candidates, investors and journalists get from AI models, and the pages they come from;
- Product and pricing teams: confirm the models quote current prices and plans after a change;
- Agencies (SEO, GEO, PR, reputation management, digital): measure AI visibility for your clients and show what your work changed. Resell it under the reseller partner plan; the product stays Sentl.AI-branded.
Comments

Hi Fazier, I’m Paolo, the person behind Sentl.AI. We started building this after a simple question kept coming back: “What does ChatGPT say about us?” We checked by hand. The answers changed every time, depended on the account, and cited pages nobody on the team had ever looked at. Nothing could be compared month to month. Sentl.AI asks the same questions to models from OpenAI, Anthropic, Google, Perplexity and xAI on a schedule, in clean sessions and several rounds each. It stores every answer and the pages behind it. The part we care about most: you decide what a good answer is. For each question you write the correct facts and a 1–5 grading rubric. A judge model, never the one that answered, grades every answer against your rule and explains the score. A coffee brand and a law firm shouldn’t be judged by the same metrics. Keep track of what the models say about you, run after run, and see which pages to work on to change their answers. A question for you: do you check what AI models say about your product today? If you do, how?
Premium Products


Sponsors
Buy
Makers
Makers
Comments
Hi Fazier, I’m Paolo, the person behind Sentl.AI. We started building this after a simple question kept coming back: “What does ChatGPT say about us?” We checked by hand. The answers changed every time, depended on the account, and cited pages nobody on the team had ever looked at. Nothing could be compared month to month. Sentl.AI asks the same questions to models from OpenAI, Anthropic, Google, Perplexity and xAI on a schedule, in clean sessions and several rounds each. It stores every answer and the pages behind it. The part we care about most: you decide what a good answer is. For each question you write the correct facts and a 1–5 grading rubric. A judge model, never the one that answered, grades every answer against your rule and explains the score. A coffee brand and a law firm shouldn’t be judged by the same metrics. Keep track of what the models say about you, run after run, and see which pages to work on to change their answers. A question for you: do you check what AI models say about your product today? If you do, how?
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2026. All Rights Reserved