Launch
CiteRocket
Visit
Example Image

CiteRocket

The Reddit API for your next build
Visit

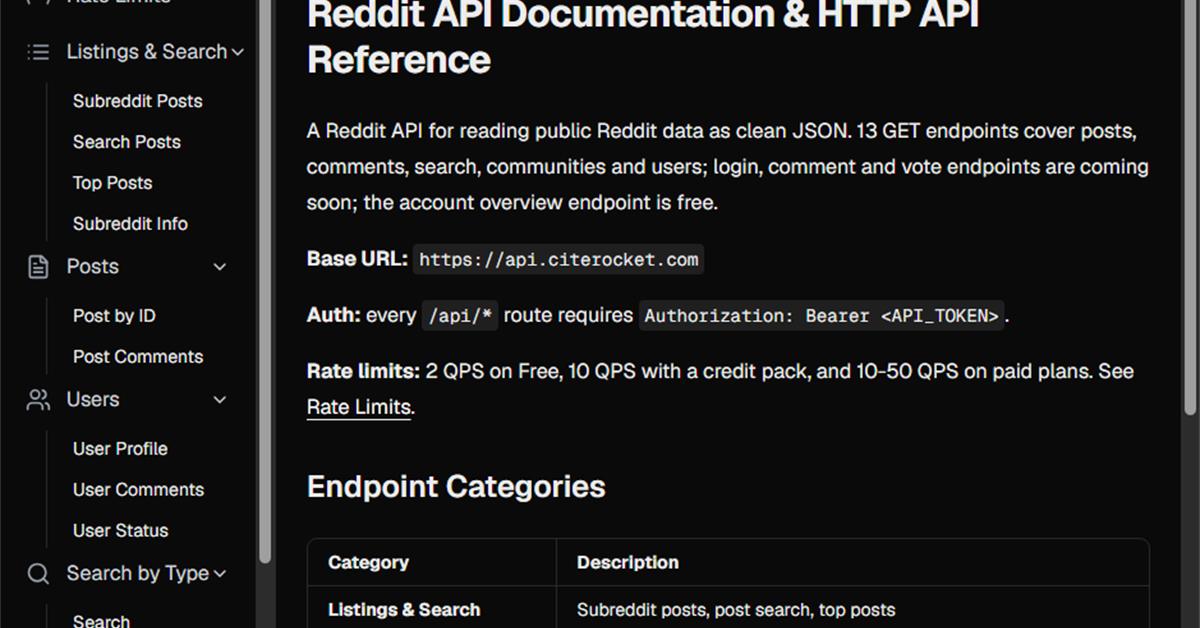
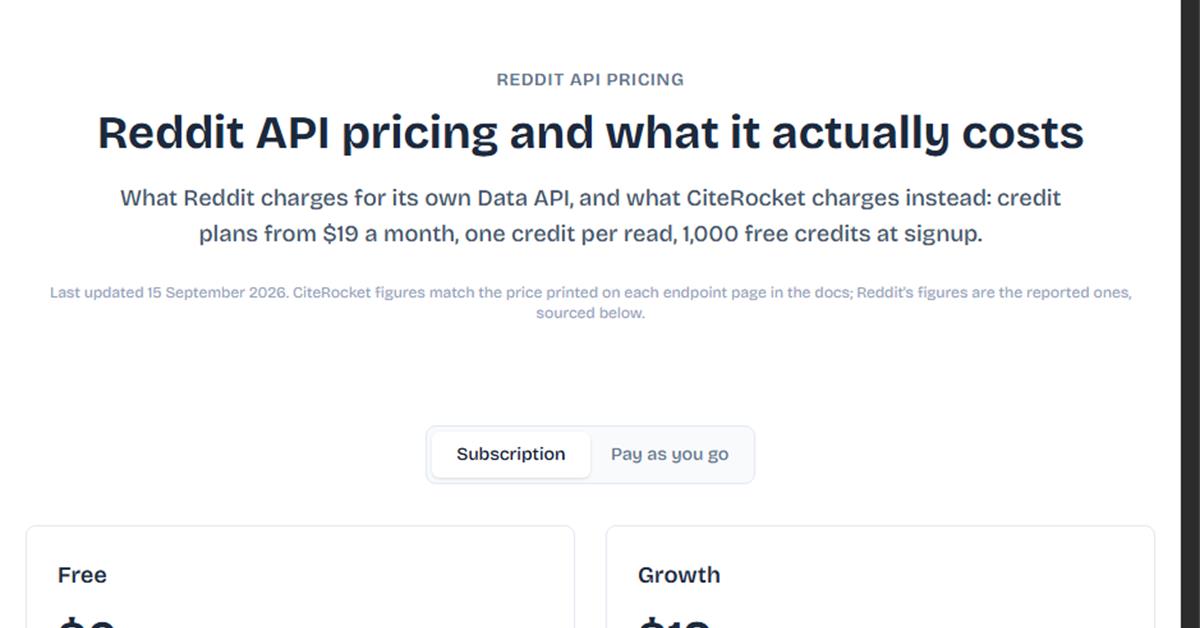
CiteRocket is a managed Reddit API for developers, apps and AI agents. One Bearer token and 13 read endpoints for posts, comments, search, subreddits and users. No Reddit developer account, no OAuth flow, no approval wait. Start free with 1,000 credits and no card.

Example Image
Example Image
Example Image
Example Image

Features

One Bearer token, no OAuth app and no Reddit approval wait

Clean JSON for posts, comments, search, subreddits and users

13 read endpoints with pagination

Free tier with 1,000 credits and no card

Use Cases

Monitor brand and keyword mentions across Reddit

Research subreddits before launching a product

Feed Reddit conversations to AI agents and MCP clients

Build dashboards and alerts on Reddit data

Comments

I built CiteRocket because getting Reddit data should not require an OAuth app and a week of waiting. One API key, clean JSON, 13 read endpoints, and a free tier with 1,000 credits. Happy to answer questions about limits or pricing.

Skipping Reddit's OAuth and approval wait is a real pain point solved. How do the 1,000 free credits map to calls? Is one search or one comment-tree fetch a single credit, or does pagination count per page?

The no-OAuth, single Bearer token approach is a nice fit for agent workflows. Do you cache repeated reads of the same thread server-side, and do cached hits still consume credits? That would matter a lot for dashboards that poll the same subreddit.

tbh,i was looking for this kinda of project. thanks buddy. gonna use it in one of my web app.

Exposing 13 read endpoints behind a single Bearer token is a neat way to skip Reddit's OAuth approval for agent projects. I'm curious how rate limits work in practice: if I poll a few subreddits for keyword mentions every few minutes, how would you estimate monthly credit use, and are comment-tree fetches priced differently from searches?

The no-OAuth, single Bearer token approach is a nice fit for agent workflows.

Dope, this will be useful

Premium Products
Comments

I built CiteRocket because getting Reddit data should not require an OAuth app and a week of waiting. One API key, clean JSON, 13 read endpoints, and a free tier with 1,000 credits. Happy to answer questions about limits or pricing.

Skipping Reddit's OAuth and approval wait is a real pain point solved. How do the 1,000 free credits map to calls? Is one search or one comment-tree fetch a single credit, or does pagination count per page?

The no-OAuth, single Bearer token approach is a nice fit for agent workflows. Do you cache repeated reads of the same thread server-side, and do cached hits still consume credits? That would matter a lot for dashboards that poll the same subreddit.

tbh,i was looking for this kinda of project. thanks buddy. gonna use it in one of my web app.

Exposing 13 read endpoints behind a single Bearer token is a neat way to skip Reddit's OAuth approval for agent projects. I'm curious how rate limits work in practice: if I poll a few subreddits for keyword mentions every few minutes, how would you estimate monthly credit use, and are comment-tree fetches priced differently from searches?

The no-OAuth, single Bearer token approach is a nice fit for agent workflows.

Dope, this will be useful

Premium Products