AnswerLine
See what AI answers about your brand
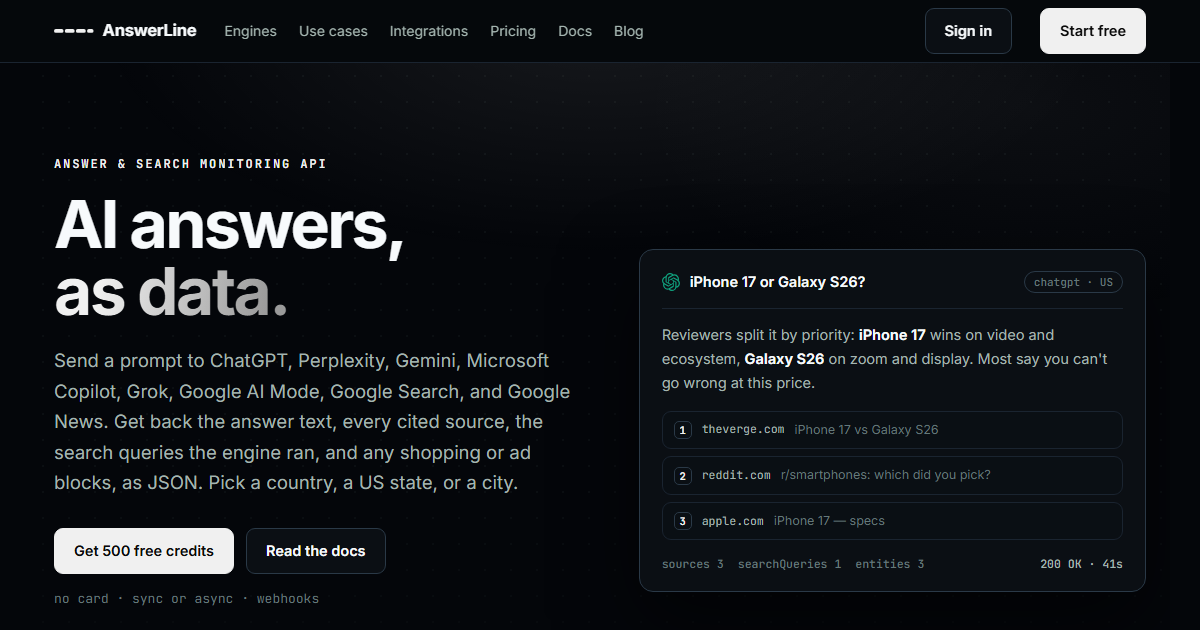
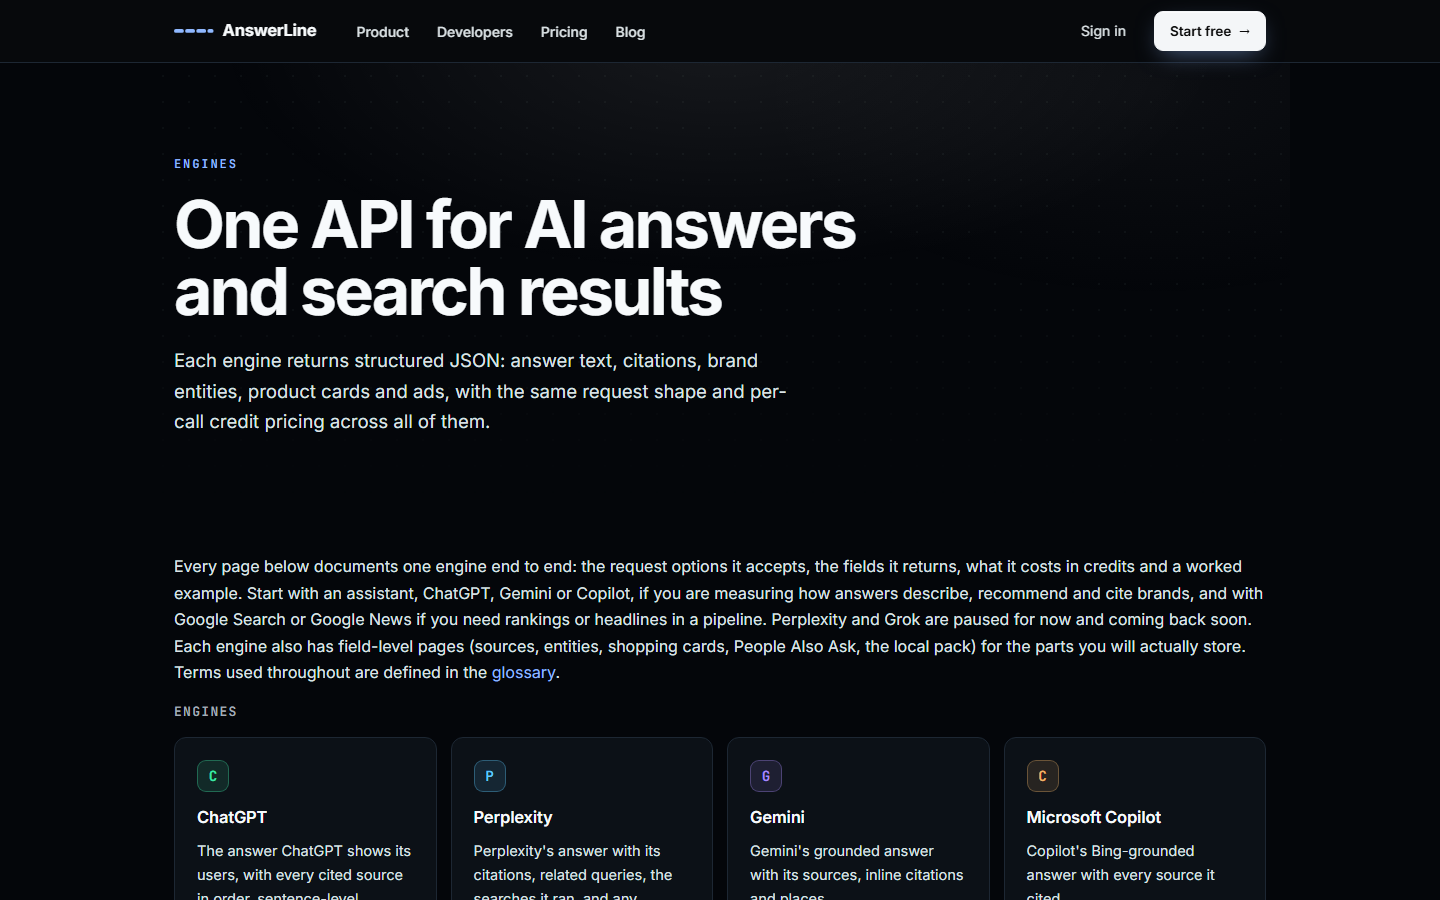
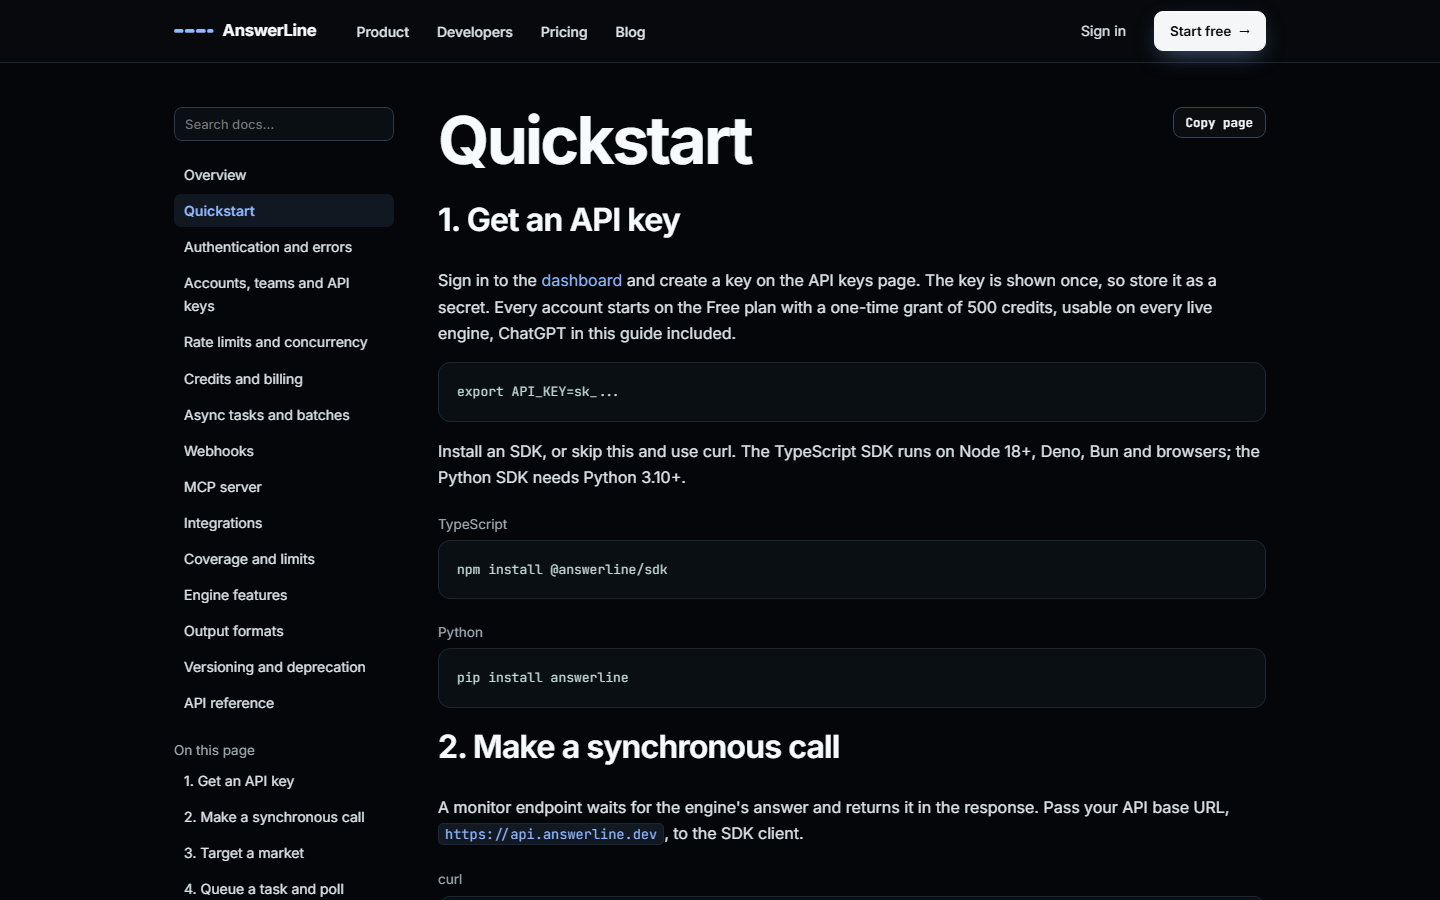
AnswerLine is an API that returns what AI assistants and AI search surfaces actually answer. Send a prompt or keyword, get back the real answer from ChatGPT, Gemini, Copilot, Google AI Mode, AI Overview and Google News as structured JSON, including cited sources and per-country variations. Sync endpoints for single lookups and async batch endpoints for monitoring thousands of prompts. An MCP server is included so any MCP-compatible assistant can query live answers directly.
Features
Real answers from ChatGPT, Gemini, Copilot, Google AI Mode, AI Overview and Google News as JSON
Cited sources per answer, per-country results
Sync and async batch endpoints
MCP server for AI assistants
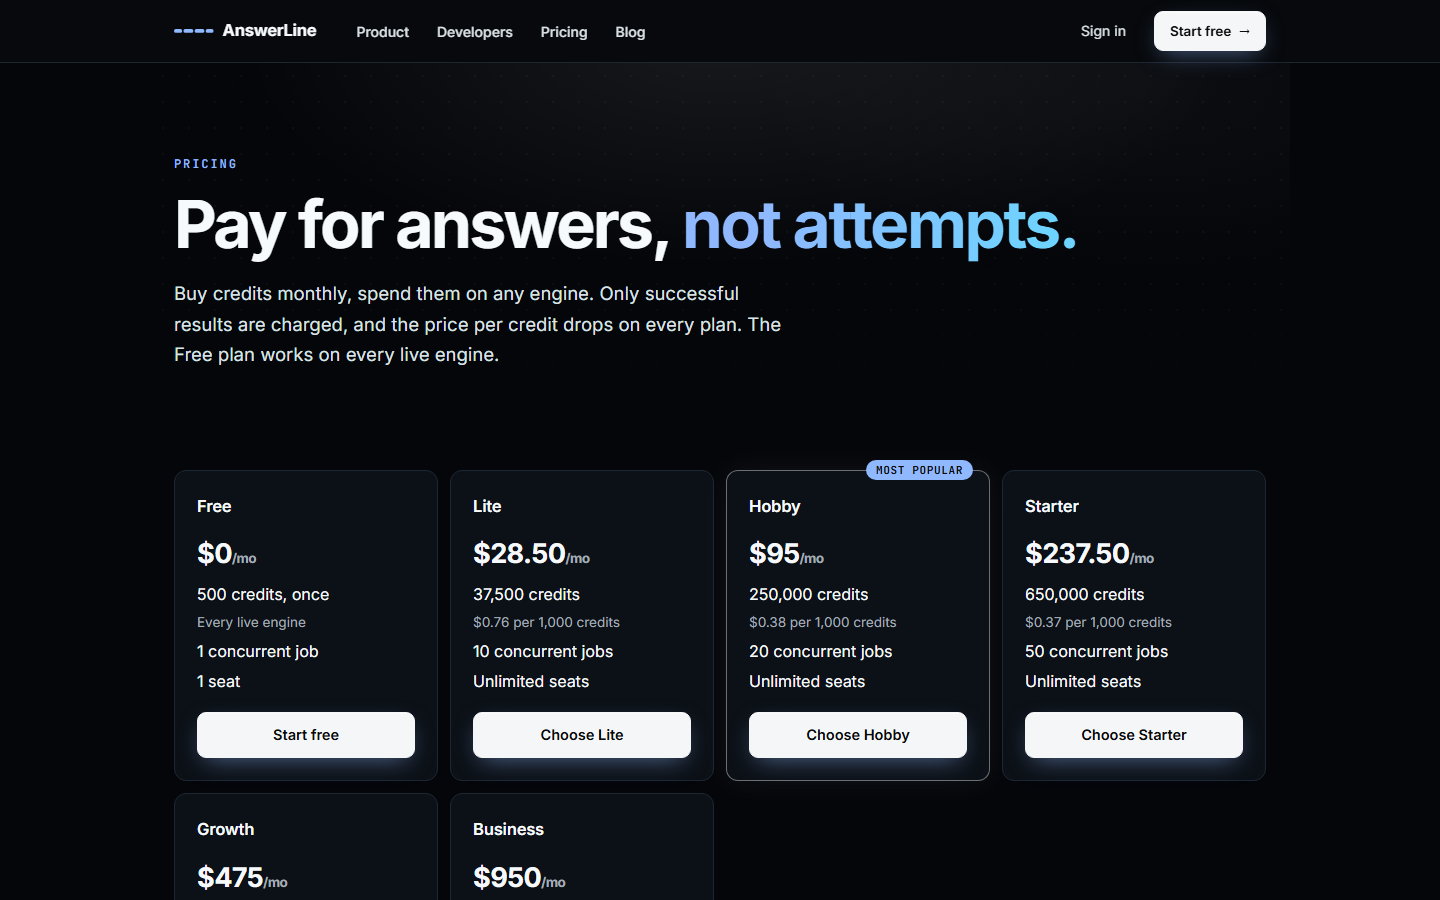
Free tier, no card required
Use Cases
Brand monitoring in AI answers
SEO and keyword research with real SERP and AI data
AI-visibility tracking for agencies
Feeding agent pipelines with live answer data
News monitoring via Google News

Comments


Built AnswerLine after spending too long scraping AI answers by hand for brand monitoring. It returns what ChatGPT, Gemini, Copilot, AI Mode, AI Overview and Google News actually answer — real answers with cited sources, not guesses from model weights. Sync + batch endpoints, per-country, and an MCP server so assistants can query it directly. Failed lookups are free. Happy to answer anything about how the engines differ.
This is exactly the kind of tracking we've been doing by hand: asking the same set of questions every month and noting whether we get named or cited. AI answers vary a lot between runs, so how do you handle that? Do you sample a prompt several times and report how often a brand shows up, or is it one answer per call?

Premium Products

















































Sponsors
Buy

Makers
Makers
Comments
Built AnswerLine after spending too long scraping AI answers by hand for brand monitoring. It returns what ChatGPT, Gemini, Copilot, AI Mode, AI Overview and Google News actually answer — real answers with cited sources, not guesses from model weights. Sync + batch endpoints, per-country, and an MCP server so assistants can query it directly. Failed lookups are free. Happy to answer anything about how the engines differ.
This is exactly the kind of tracking we've been doing by hand: asking the same set of questions every month and noting whether we get named or cited. AI answers vary a lot between runs, so how do you handle that? Do you sample a prompt several times and report how often a brand shows up, or is it one answer per call?
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2026. All Rights Reserved