VeritasLinks
See how AI models judge your company, and why
You asked ChatGPT about your own company once and got an answer. Ask again and you get a different one. Ask Claude and it describes almost another company. So which one is true?
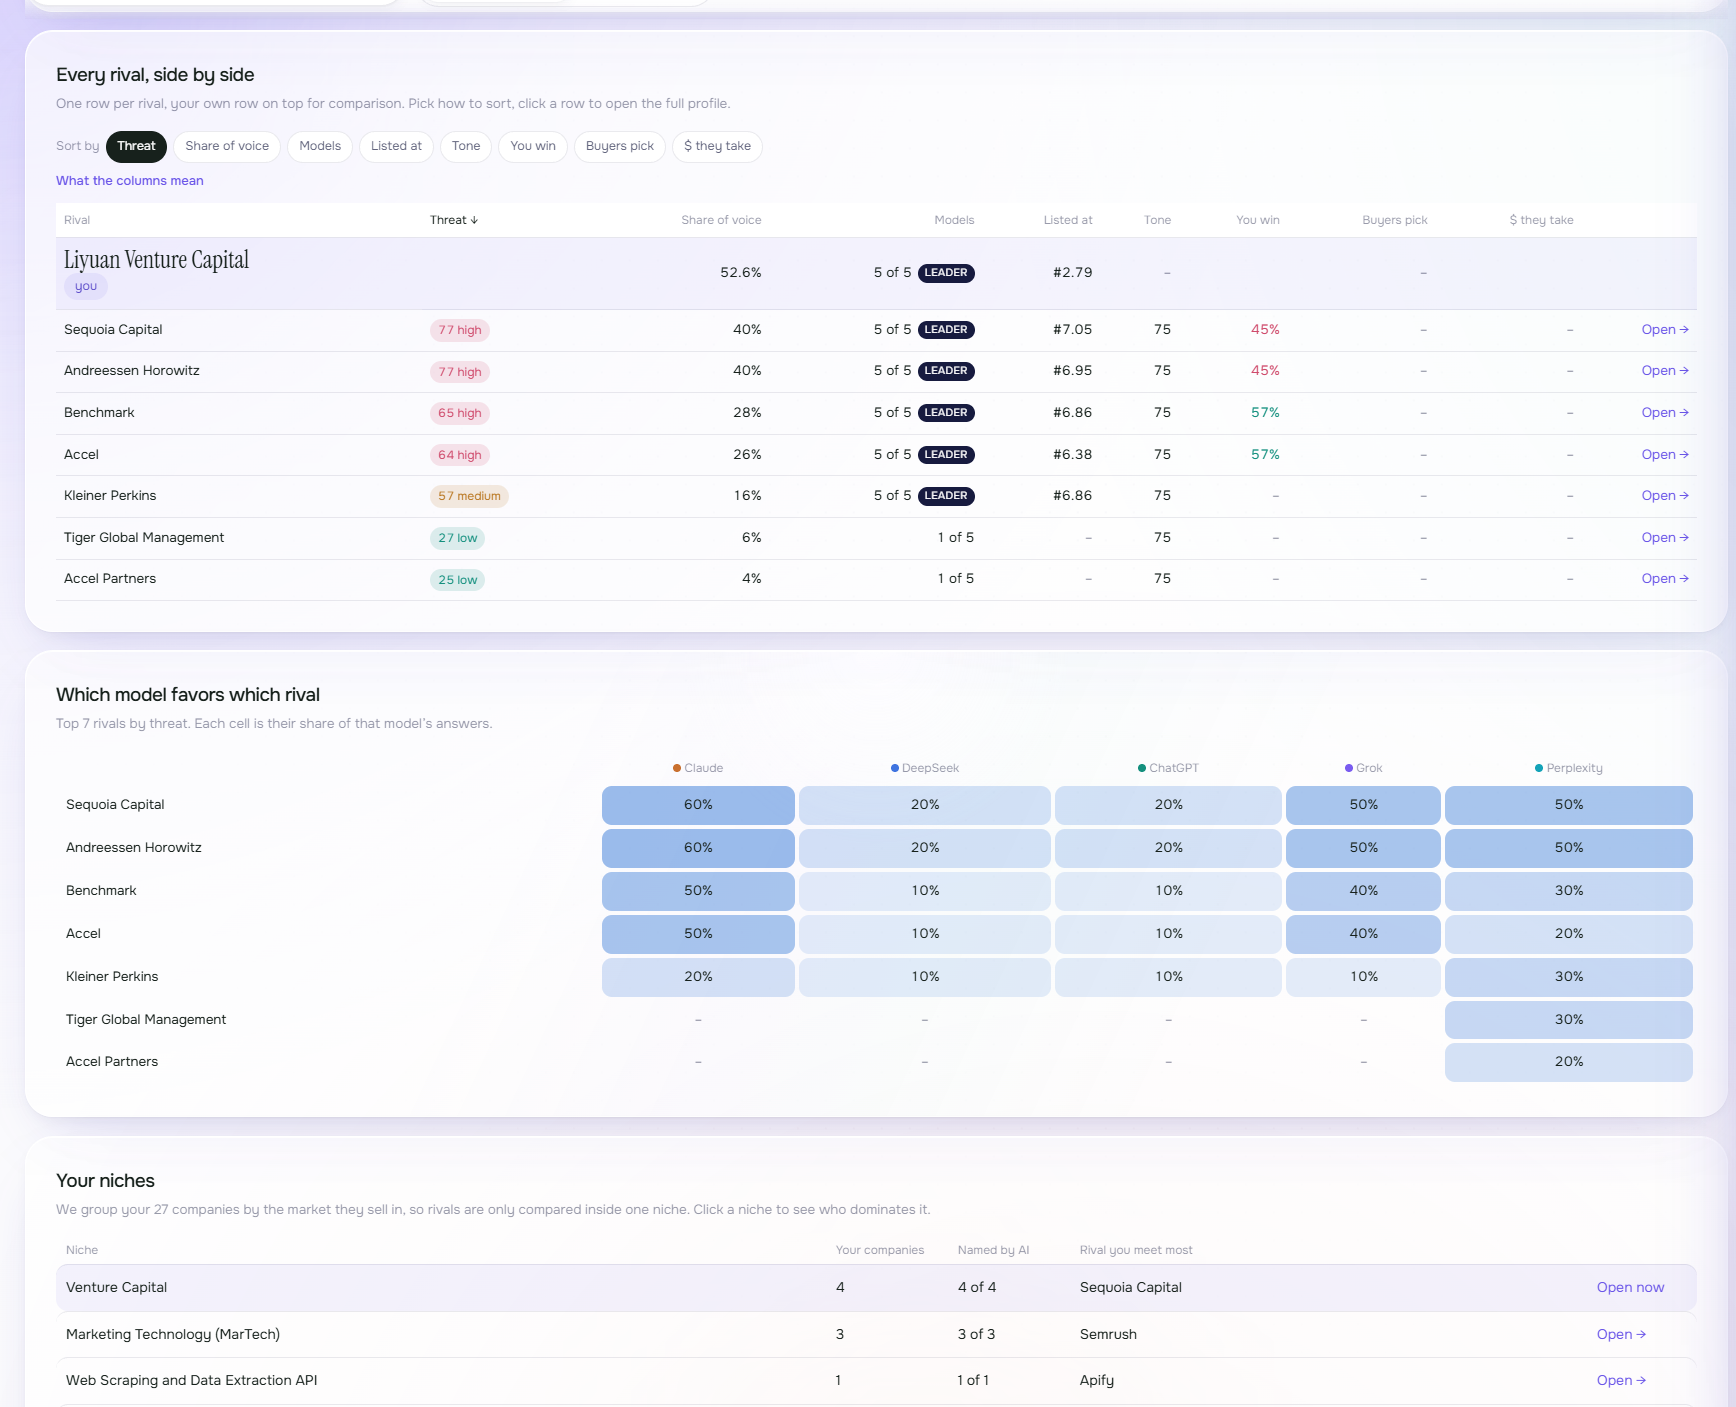
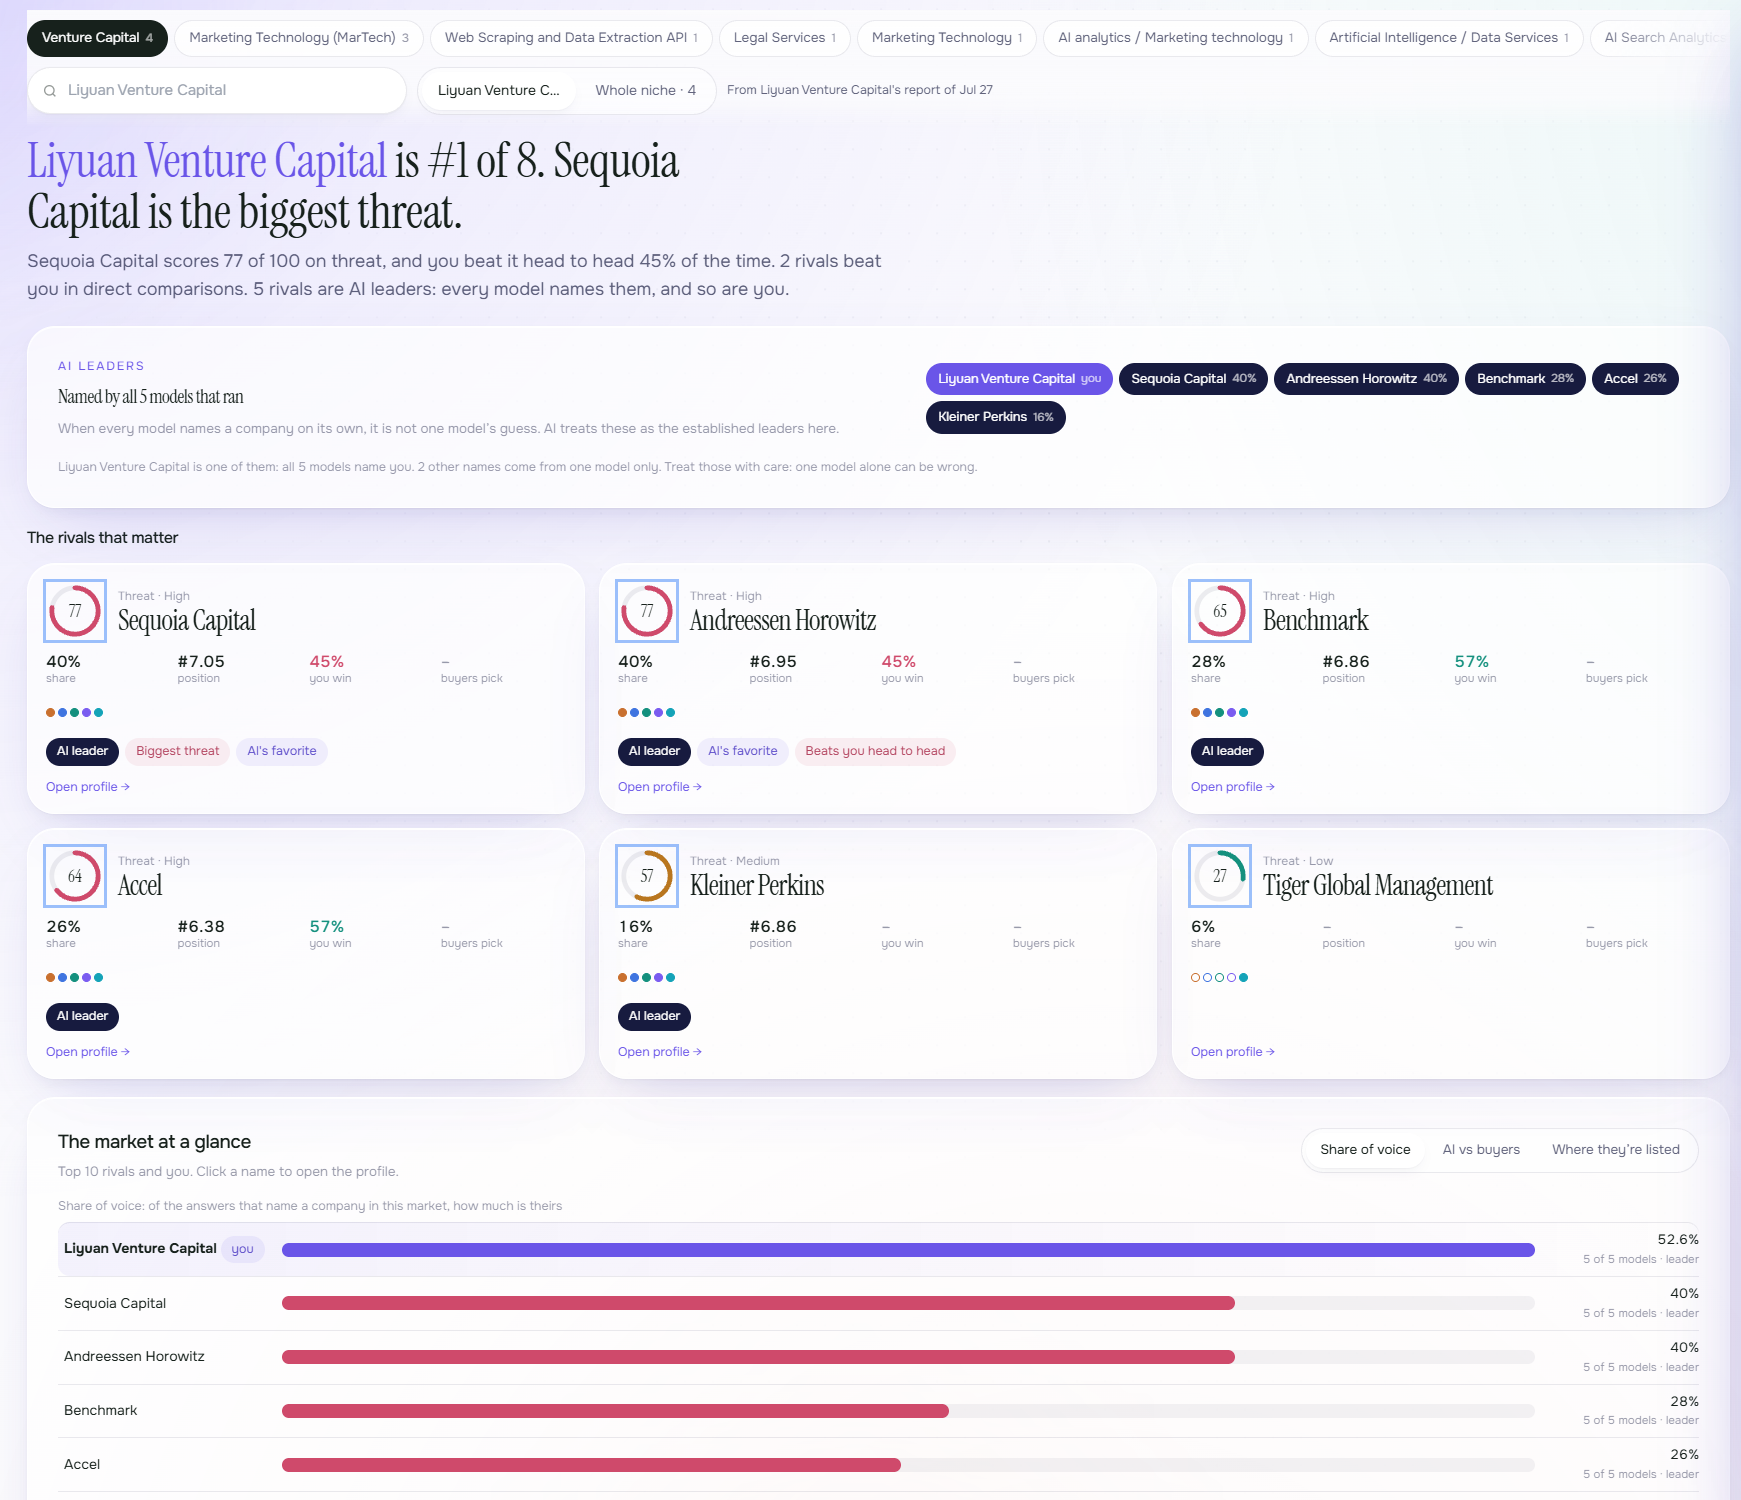
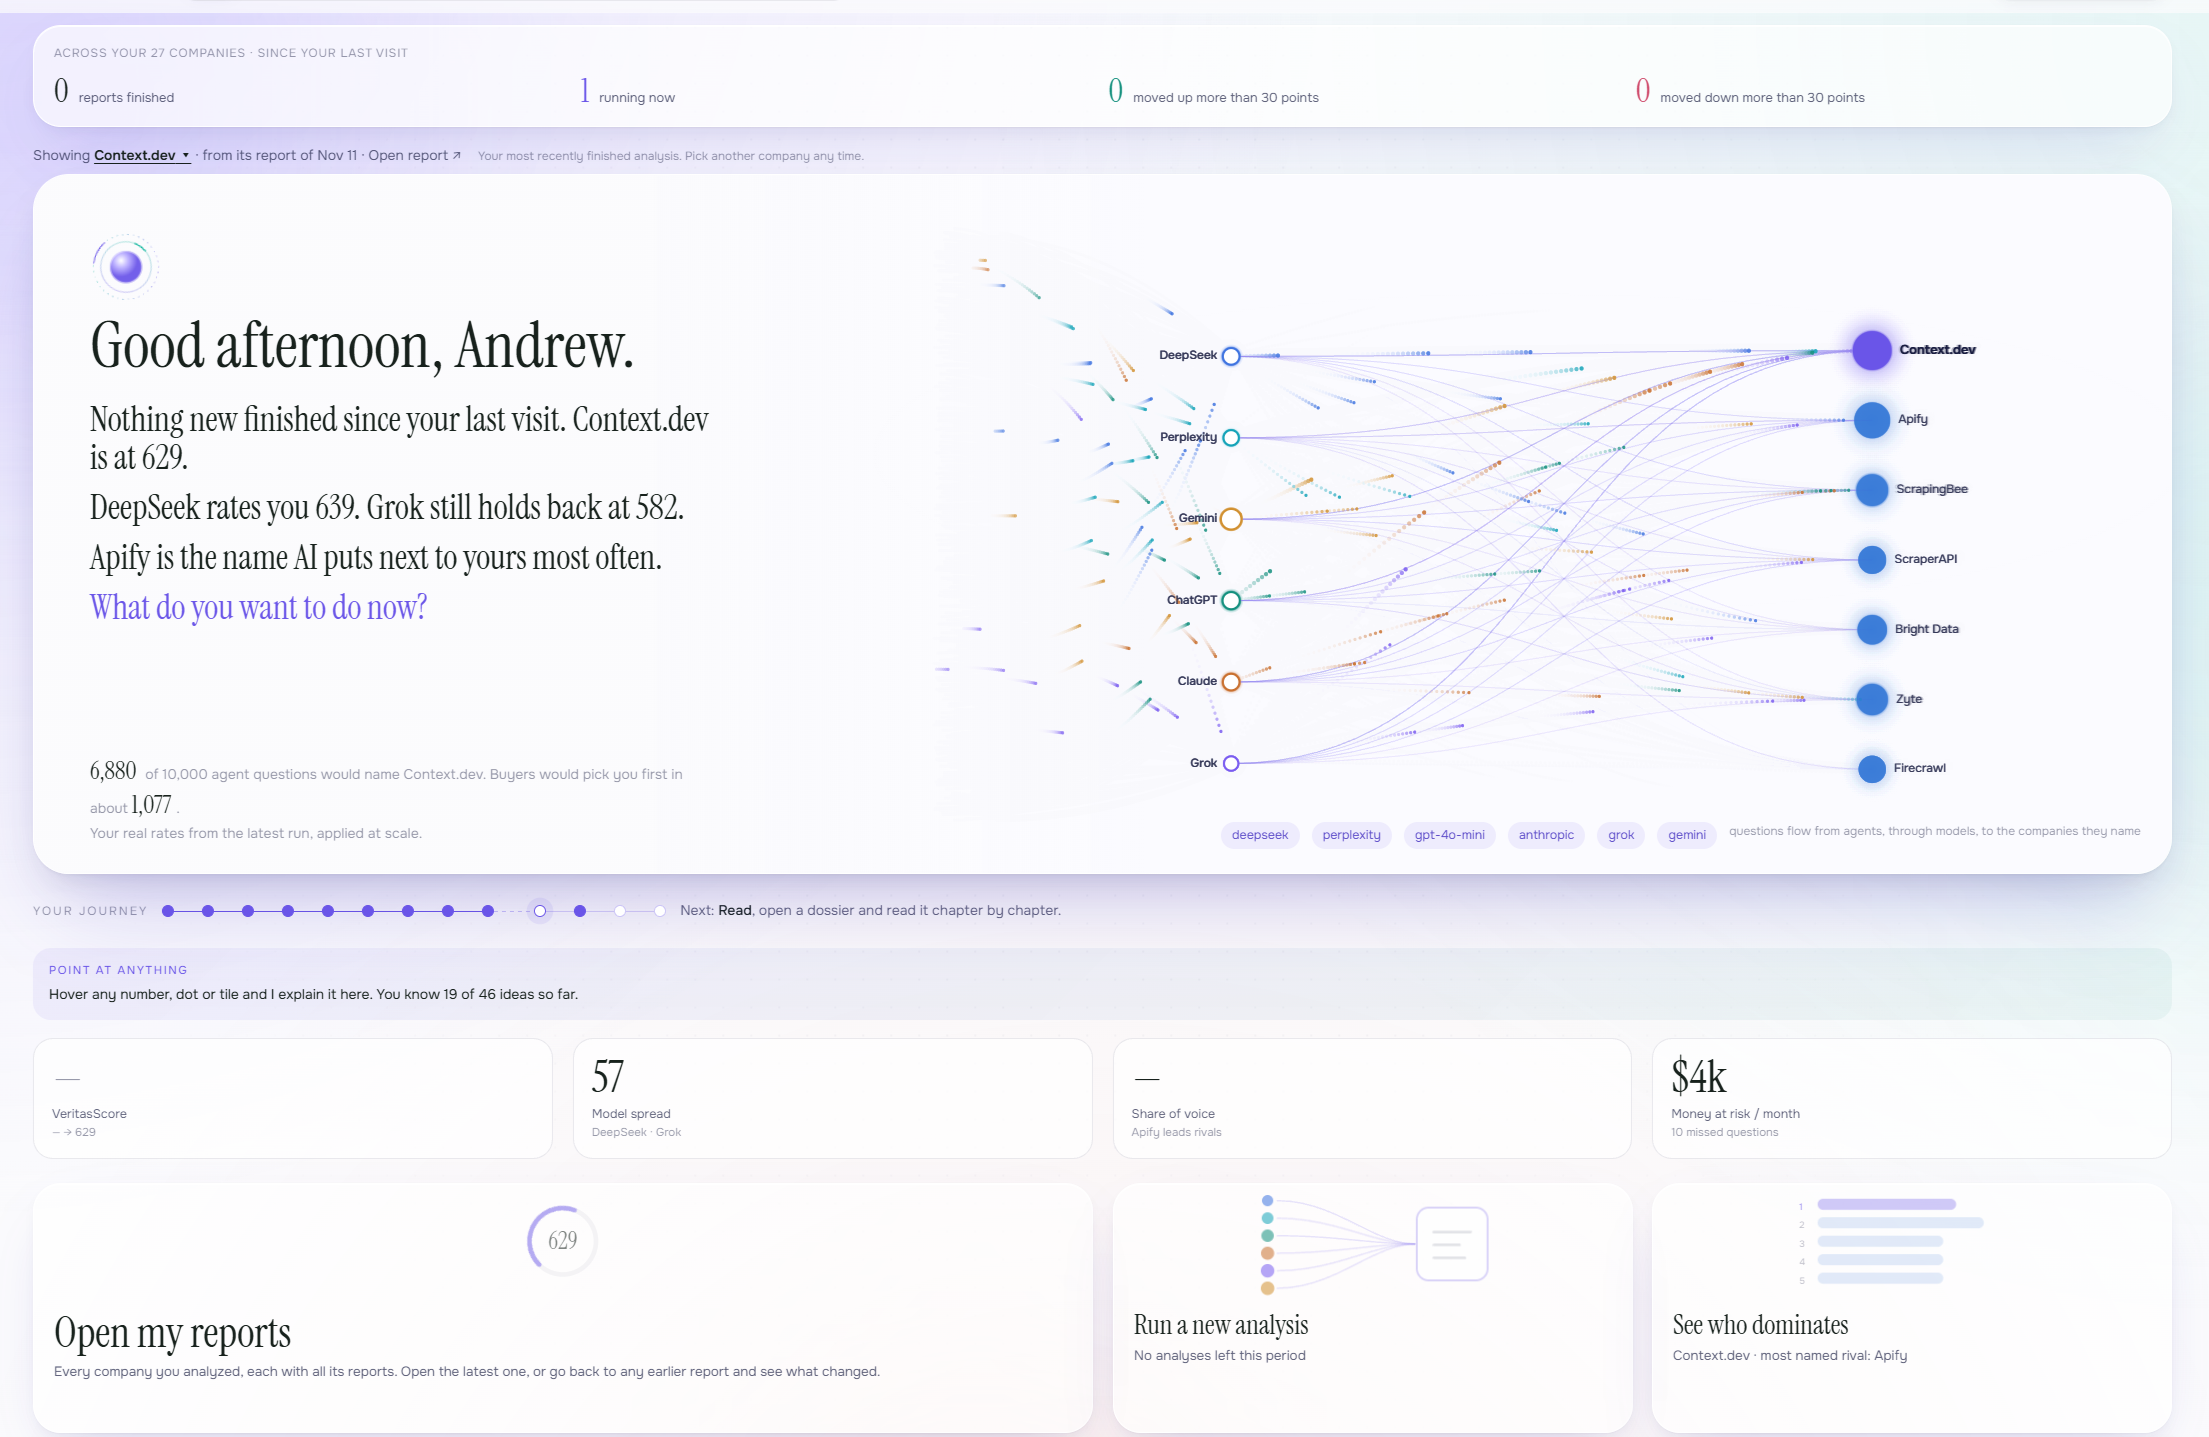
VeritasLinks runs every question many times across ChatGPT, Claude, Grok, Perplexity and DeepSeek and measures the spread, so you see what the models actually believe about you, not one random draw. It goes past "were we mentioned" to the judgment underneath: how credible each model finds you, where the models disagree with each other, and what a simulated panel of your buyers objects to before they pick a competitor.
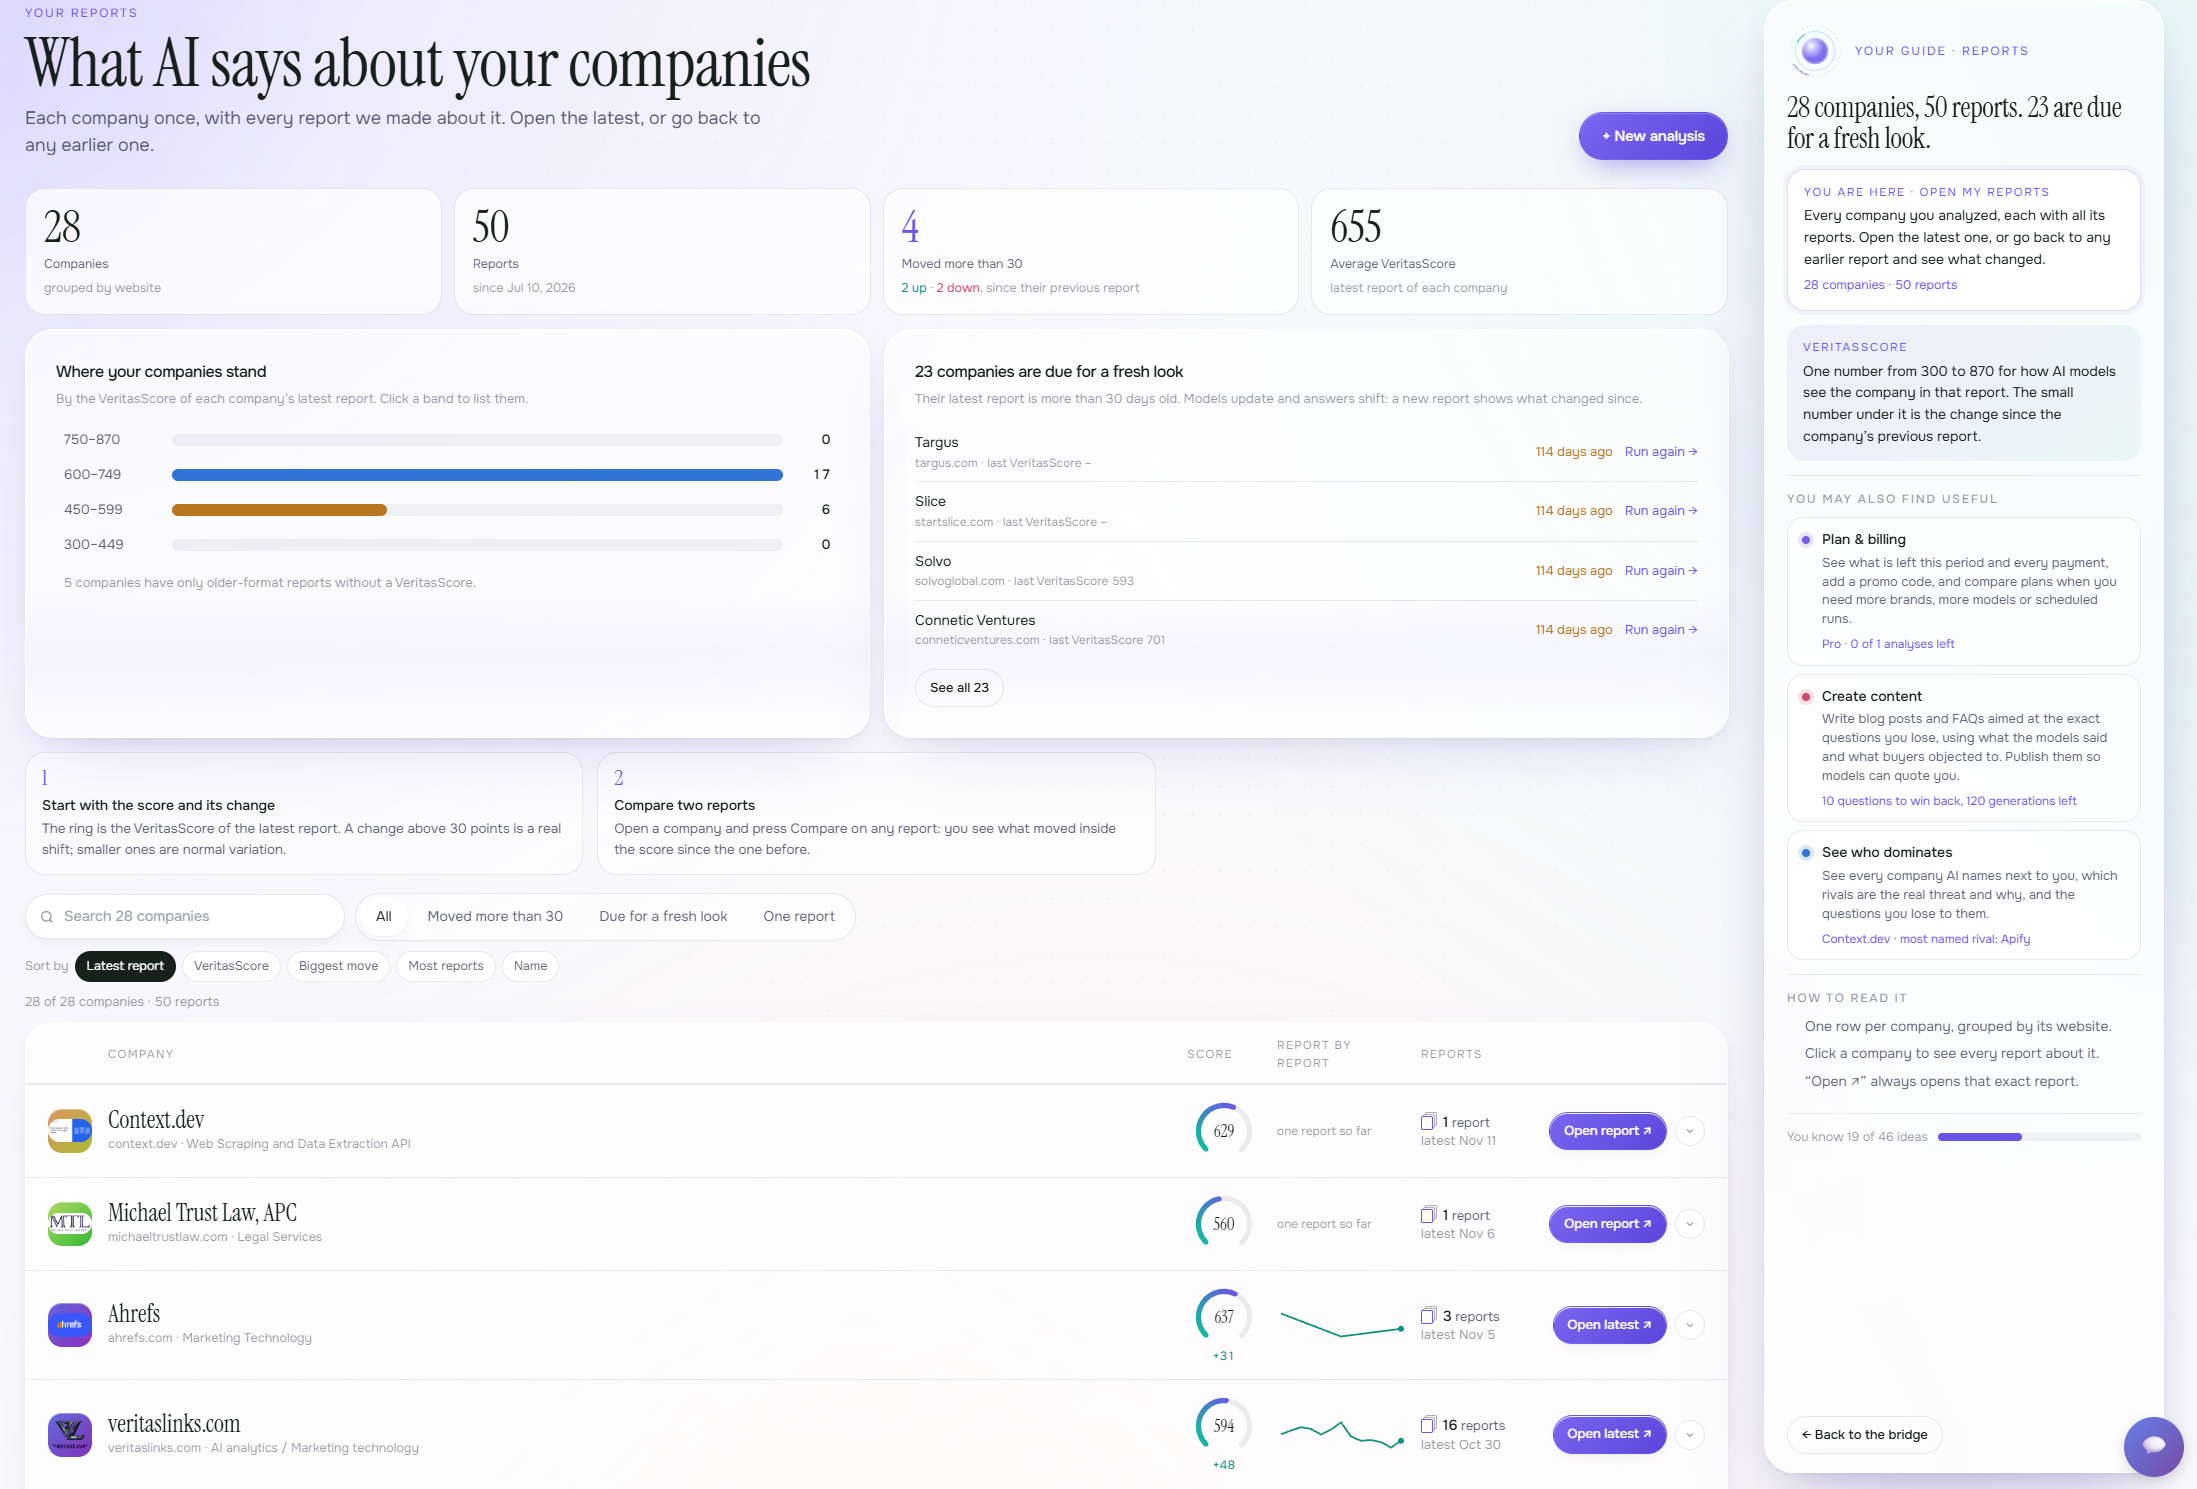
Every analysis ends with a VeritasScore from 300 to 870, a per-model breakdown and the reasons behind each number. Built by a founder who designed the scoring model at a national credit bureau. The methodology is published on SSRN.
Features
- Every question runs many times on five models, so you see the range, not one draw
- Split-perception: where ChatGPT, Claude, Grok, Perplexity and DeepSeek disagree about you
- AI focus group: simulated buyers in your niche voice their real objections
- AI investor review of your pitch deck or website
- VeritasScore 300 to 870 with per-model scores and the reasons behind them
- Competitors the models name next to you, with their own scores
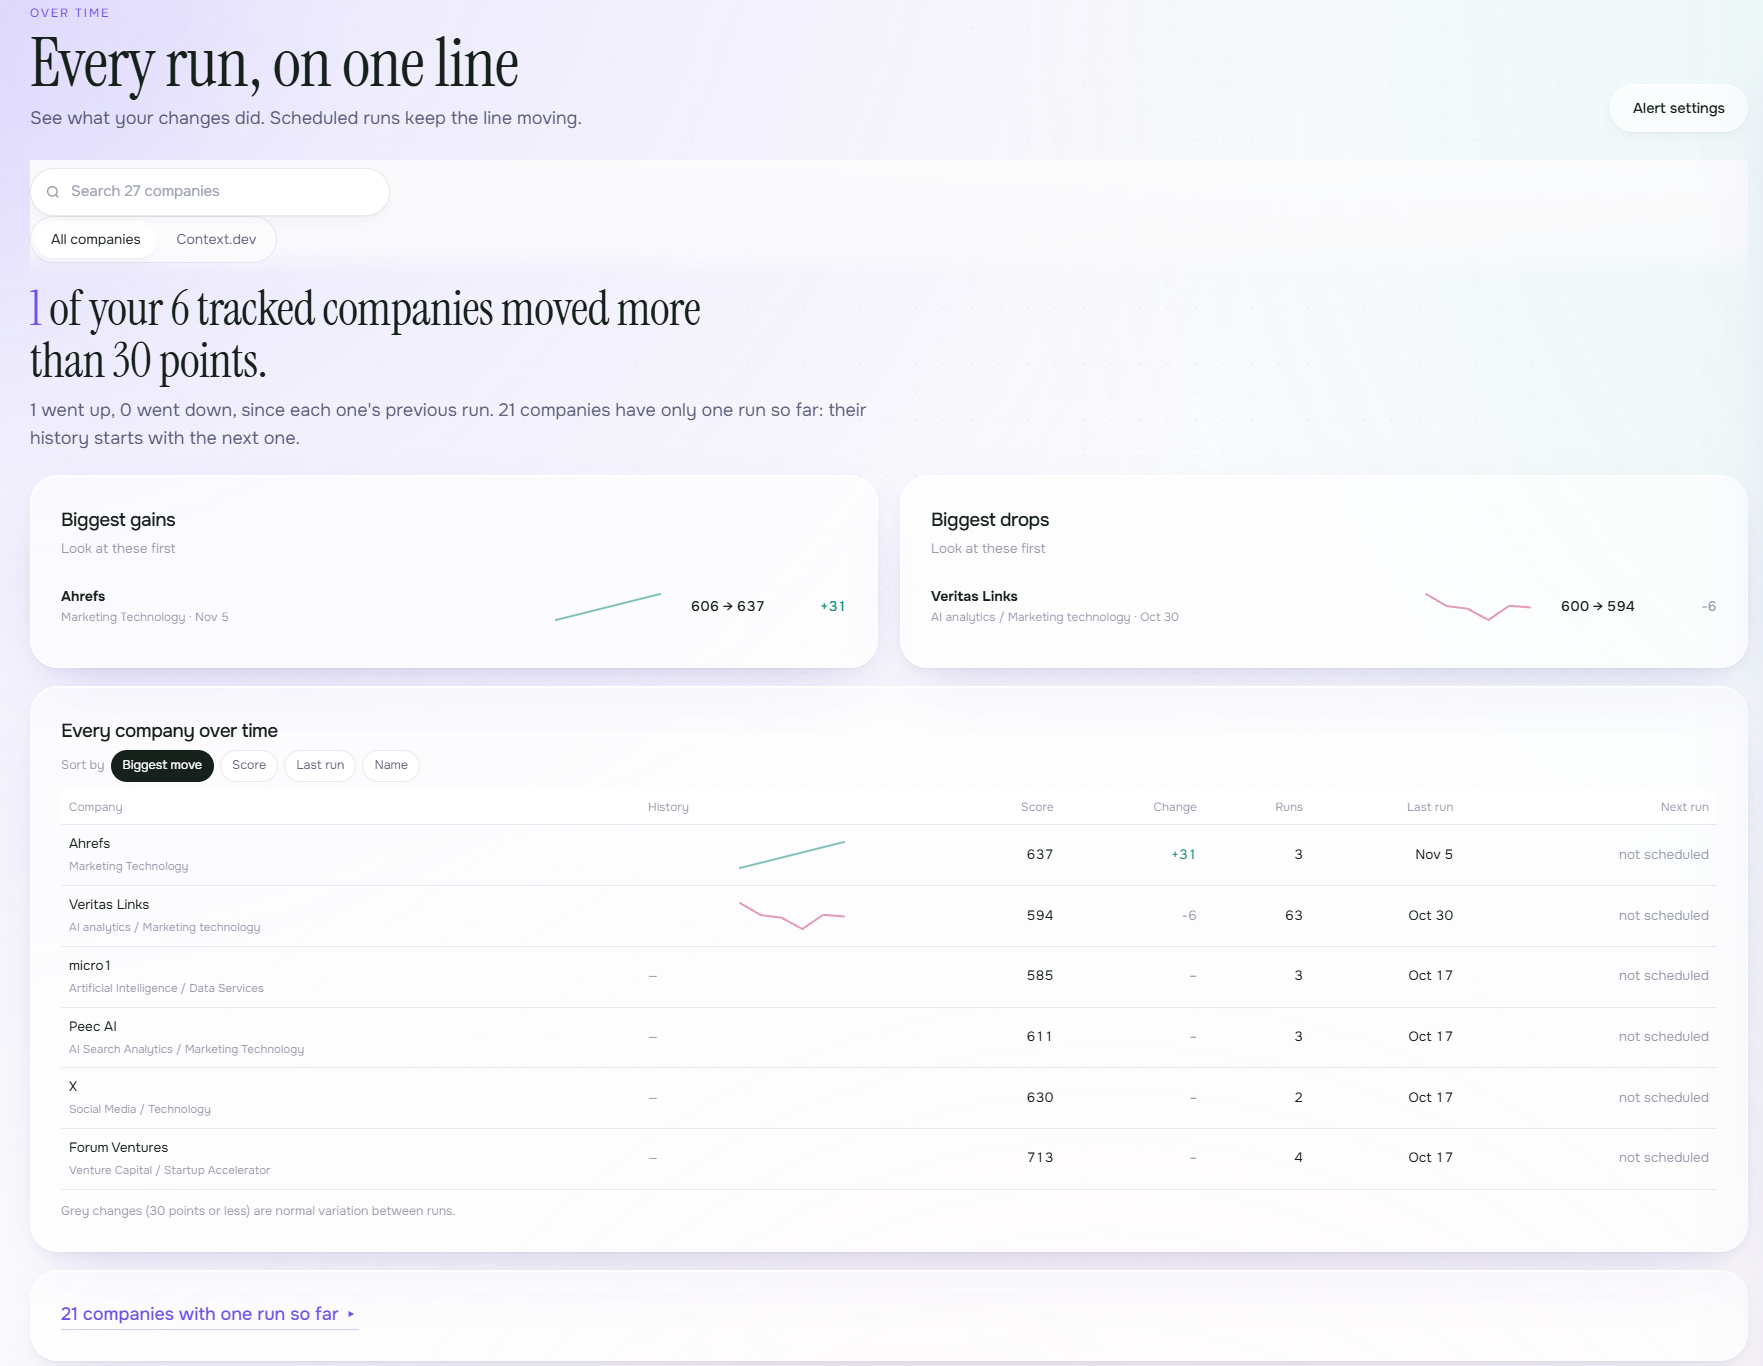
- Ongoing monitoring with an alert when your score moves
Use Cases
- Founders checking how AI describes their startup before investors look it up
- Brands finding out why models name a competitor instead of them
- Agencies running white-label AI perception reports for clients
- Due diligence teams checking how AI models portray a target company
Fazier Deal

Comments


Hi Fazier, I'm Andrew, founder of VeritasLinks. In 2014 I built the scoring model for Ukraine's national credit bureau. A bureau score only means something because it's the same number no matter who pulls it. When I started asking ChatGPT, Claude and Perplexity about companies, my own included, I got the opposite. A different story every time, and models that flatly disagreed with each other about the same company. Meanwhile people already pick vendors, partners and even acquisition targets off these answers. And most tools that "track AI visibility" ask a question once and turn that one random answer into a percentage. So VeritasLinks asks every question many times across five models, measures how far the answers spread, and shows where the models disagree and why. On top of that a simulated panel of your buyers argues about you, and an investor-style review reads your pitch the way an analyst researching you through AI would. It all rolls up into one VeritasScore from 300 to 870 with the reasons behind it. The methodology is published on SSRN if you want the numbers. Run your own company on the free plan and see what the models really think of you. I'll be in the comments all day.
Premium Products














































Fazier Deal
Makers
Makers
Comments
Hi Fazier, I'm Andrew, founder of VeritasLinks. In 2014 I built the scoring model for Ukraine's national credit bureau. A bureau score only means something because it's the same number no matter who pulls it. When I started asking ChatGPT, Claude and Perplexity about companies, my own included, I got the opposite. A different story every time, and models that flatly disagreed with each other about the same company. Meanwhile people already pick vendors, partners and even acquisition targets off these answers. And most tools that "track AI visibility" ask a question once and turn that one random answer into a percentage. So VeritasLinks asks every question many times across five models, measures how far the answers spread, and shows where the models disagree and why. On top of that a simulated panel of your buyers argues about you, and an investor-style review reads your pitch the way an analyst researching you through AI would. It all rolls up into one VeritasScore from 300 to 870 with the reasons behind it. The methodology is published on SSRN if you want the numbers. Run your own company on the free plan and see what the models really think of you. I'll be in the comments all day.
Premium Products
New to Fazier?

Find your next favorite product or submit your own. Made by @FalakDigital.
Copyright ©2026. All Rights Reserved